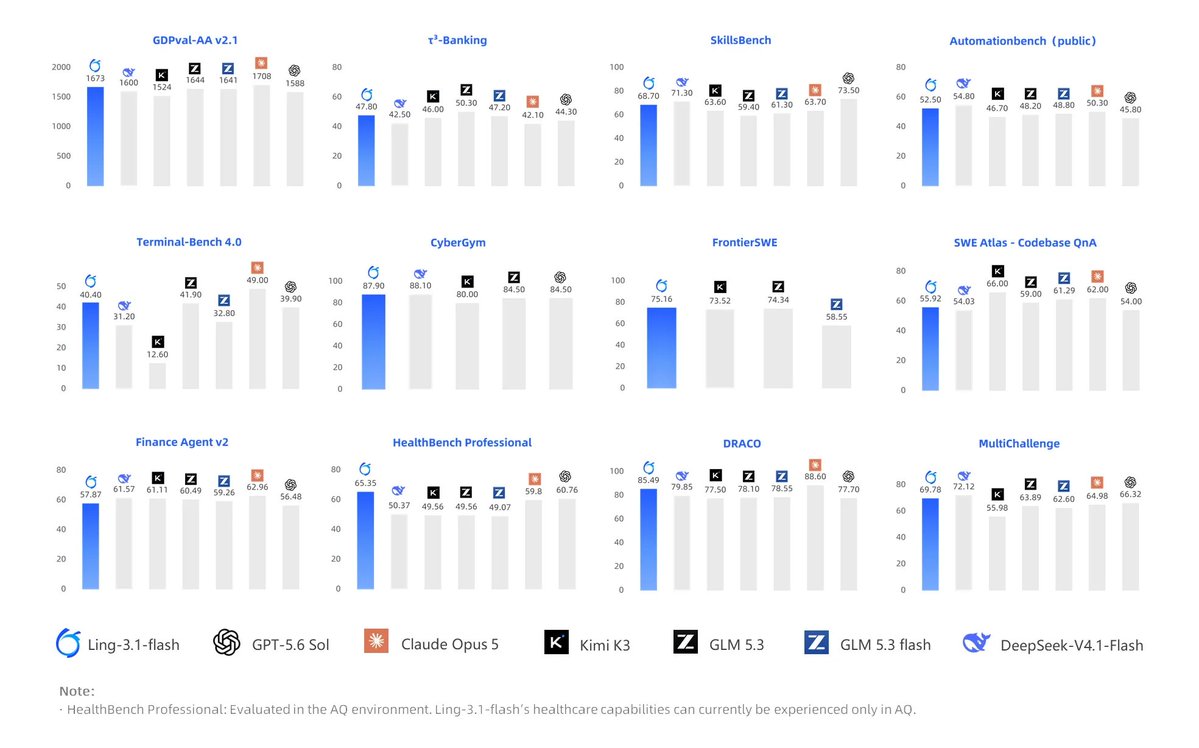
Ling-3.1-flash is now open source: ~560B total parameters, ~25B active per token and up to 1M context.
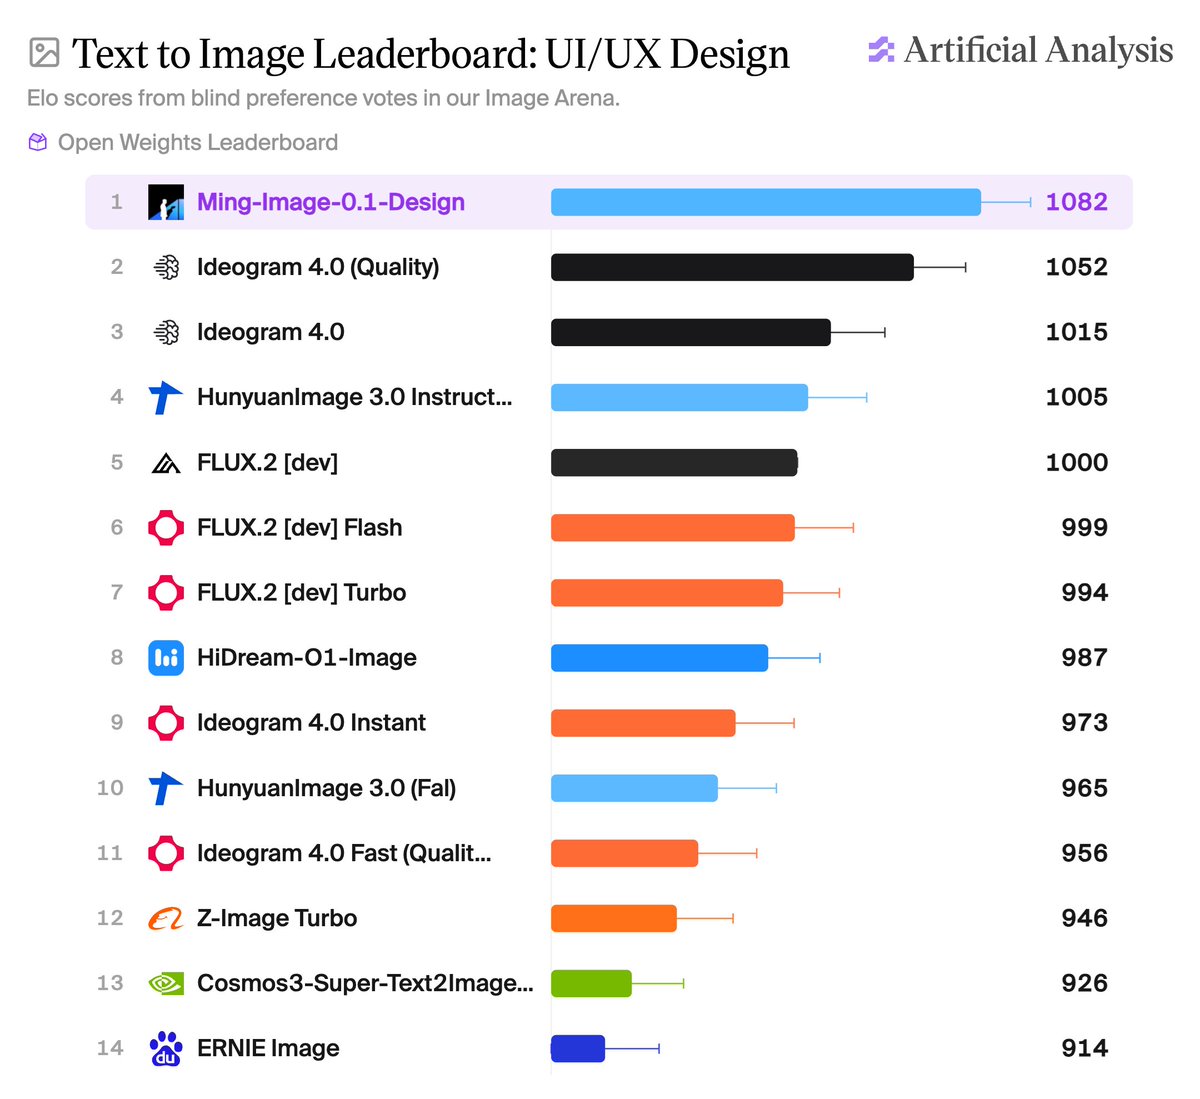
Built for real work, it can turn a rough brief into a page, mobile UI or interactive prototype teams can review and refine. See the demo.
A 560B mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → with 25B active parameters and 1M context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → is now open, and quantizationShrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.Full definition → cuts weights from about 534GB to 292GB, letting a tested Hopper setup drop from 8 GPUs to 4.
Terms in this piece · Glossary
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.