Grok Voice 3.0 tops Artificial Analysis Speech to Speech Index
- Source
- x.com
- Date

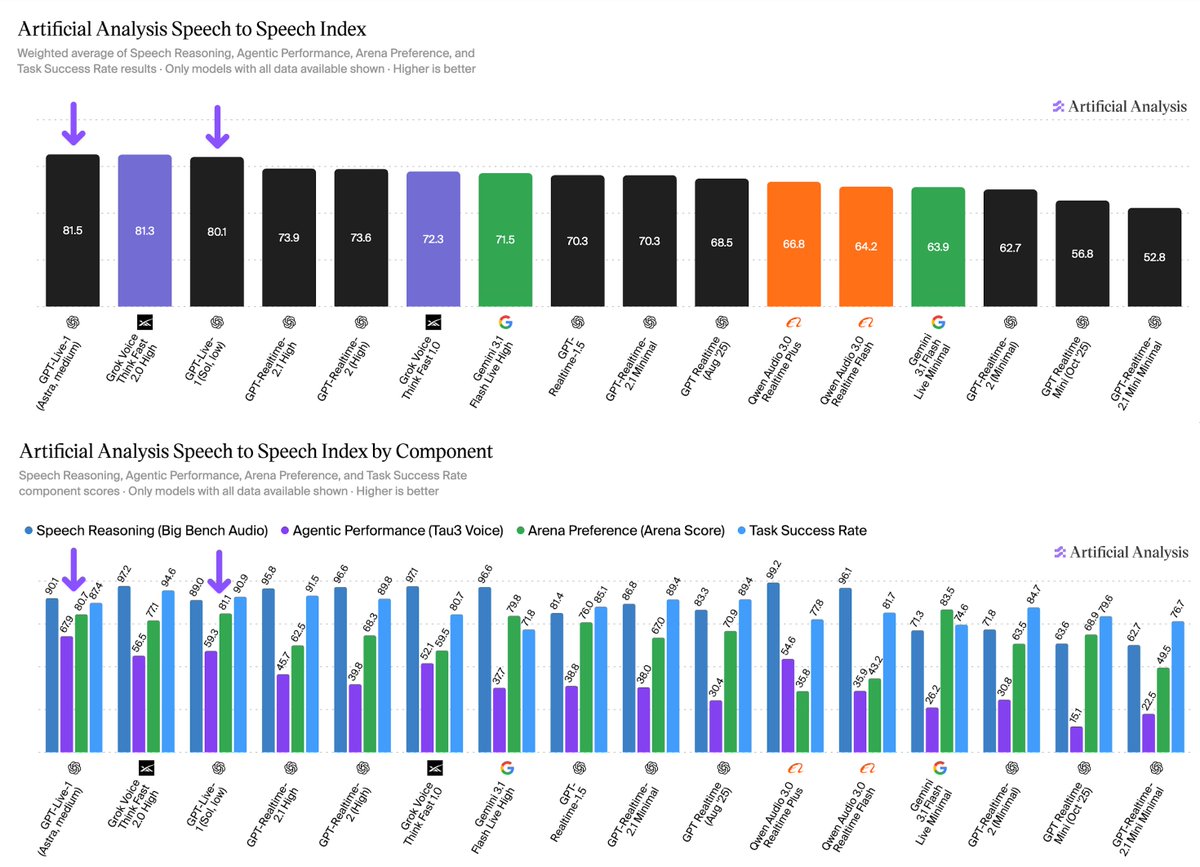
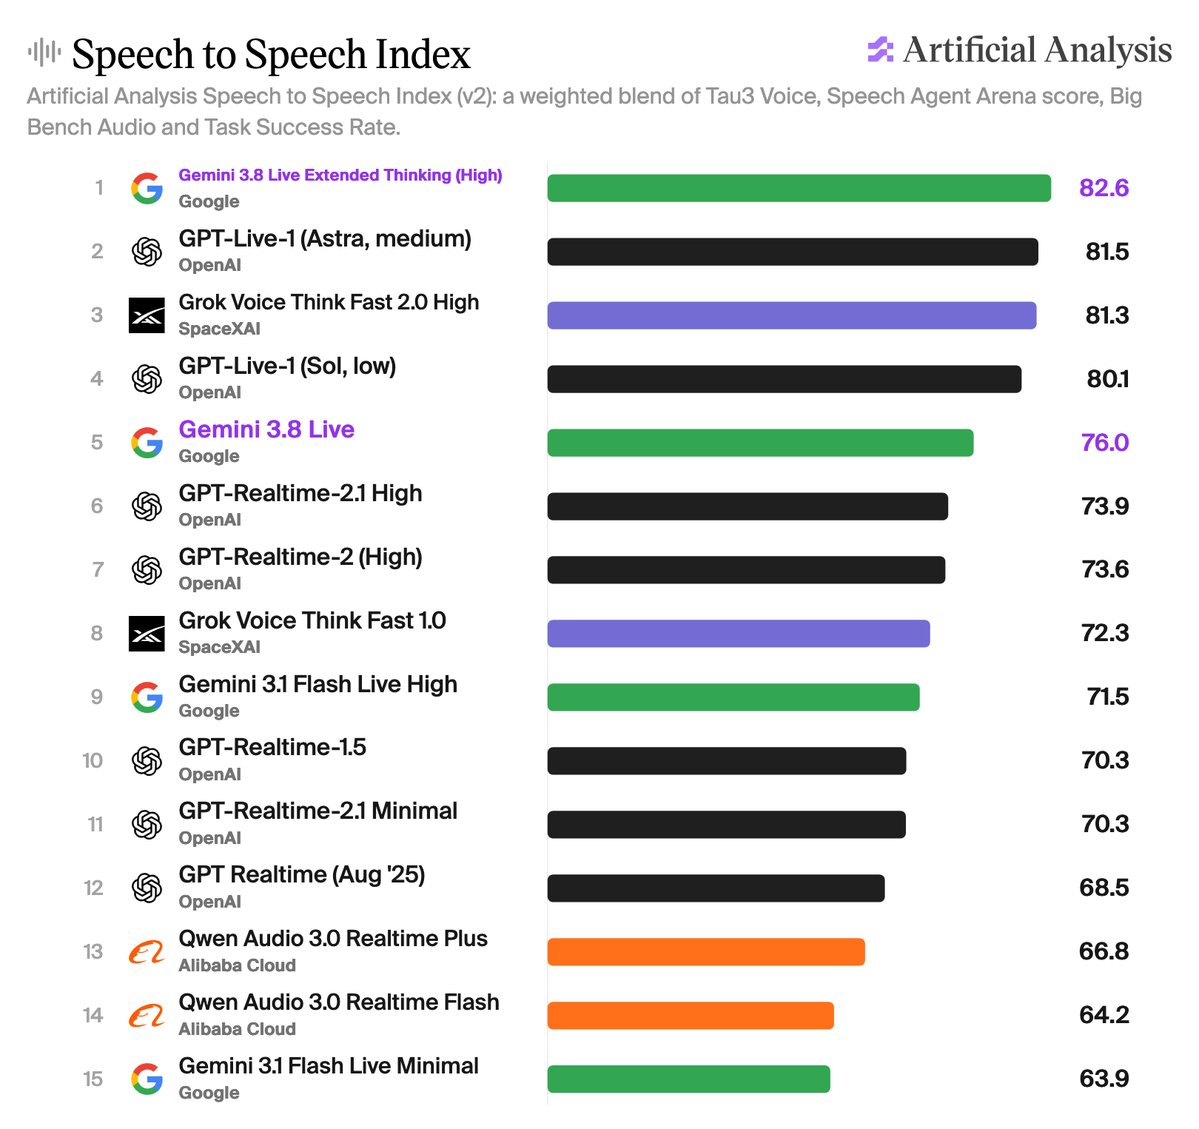
SpaceXAI’s Grok Voice 3.0 is the new leading Speech to Speech model, debuting at #1 on the Artificial Analysis Speech to Speech Index at 86.9, while also being competitive on latency Grok Voice 3.0 is @spacexai 's successor to Grok Voice 2.0, a Speech to Speech model available through the SpaceXAI Realtime API at $0.08 per minute. We evaluated Grok Voice 3.0 with the Rex voice through the SpaceXAI Realtime API. Key takeaways: ➤ Speech to Speech Index: Grok Voice 3.0 debuts at #1 at 86.9, ahead of GPT-Live-1 (Astra, medium) at 83.2, Gemini 3.8 Live Extended Thinking (High) at 82.6 and GPT-Live-1 (Sol, low) at 80.1. It is up on Grok Voice 2.0 at 81.3 (+5.6 points) and Grok Voice 1.0 at 73.7 (+13.2 points), released just under six months ago. The Index averages Speech Reasoning (Big Bench Audio), Agentic Performance (Tau Voice), Arena Preference, and Task Success Rate ➤ Speech Agent Arena: Grok Voice 3.0 ranks #3 in preference at Elo 1070, behind Gemini 3.1 Flash Live Minimal (1100) and Gemini 3.8 Live (1088) and ahead of GPT-Live-1 (Sol, low) at 1057, and #1 on Task Success Rate at 94.8%, highest on the board, just ahead of Grok Voice 2.0 at 94.6%. Grok Voice 2.0 trails at Elo…

Context
Grok Voice 3.0 led Artificial Analysis's composite speech-to-speech index in its October 14 report, scoring 86.9, but ranked third on preference in the evaluator's Speech Arena. The index averages reasoning, agent performance, arena preference and task completion, so its leader need not win every component. Evaluation report.
The same report gives Grok Voice 3.0 the highest task-success rate on the arena board, 94.8%, just ahead of Grok Voice 2.0. That measures whether a spoken task was completed, a different outcome from which model was preferred in head-to-head comparisons. Together, the results distinguish completing a spoken task from providing the most-liked interaction. Arena results.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…