How NVIDIA Groq 3 LPX Unlocks Ultrafast Interactivity at Long Context on NVIDIA Vera Rubin
- Source
- developer.nvidia.com
- Author
- Tanya Lenz
- Date
Context
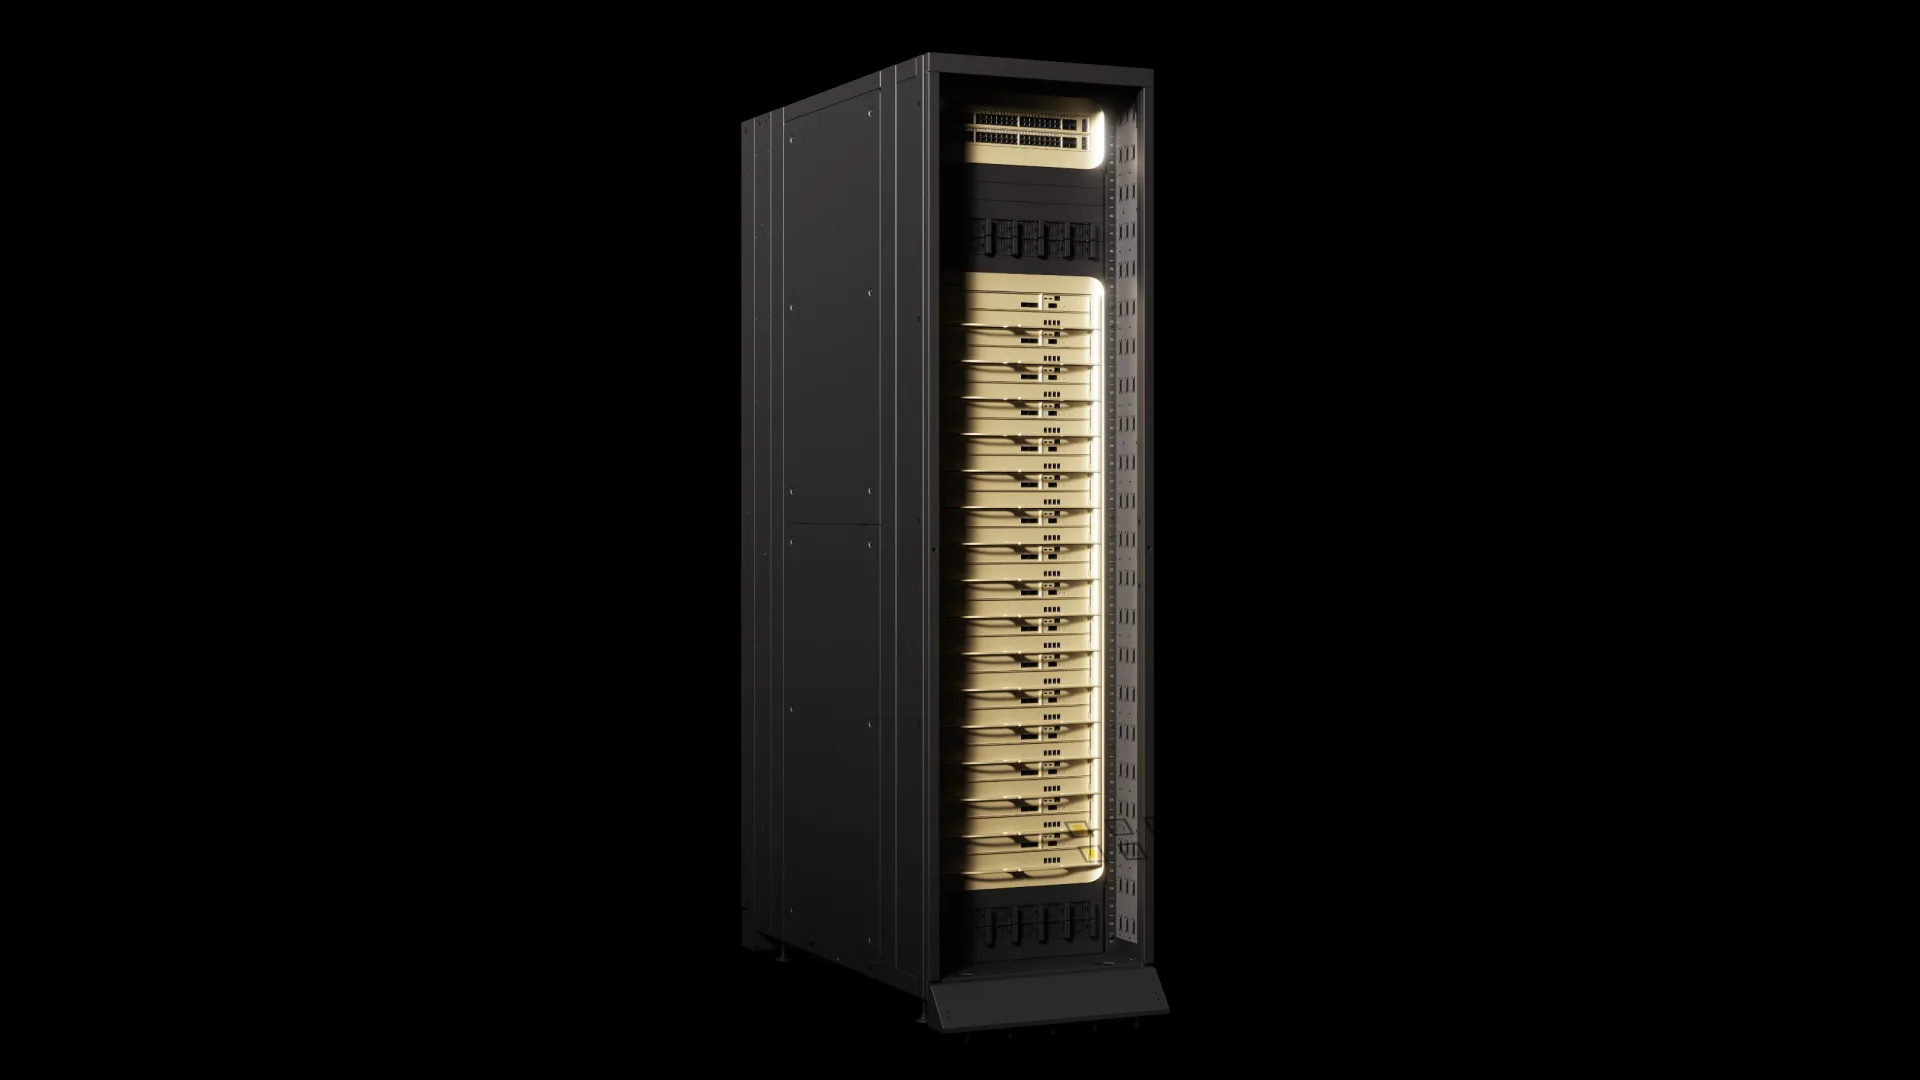
NVIDIA reports that its Groq 3 LPX system, running in its own data centers, generated text almost equally fast with 100,000 input as with 10,000. Testing by Artificial Analysis on Gemma 4 31B measured median output speeds of 3,431 and 3,382 tokens per second, respectively. That matters for agents whose working grows as they read files and accumulate results. The benchmark report describes the tested configuration.
LPX schedules computation and transfers between chips in advance, allowing small results to move while other calculations continue. NVIDIA attributes its speed to reducing coordination delays when many chips cooperate on one response. The demonstrated result concerns this model and configuration; the article's two-trillion-parameter example is a projection.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
 articleScaling NVIDIA TensorRT Performance Optimization Beyond a Single Build Route with the Global Performance Tuner, Part 2
 articleAccelerating Mamba-2 with High-Performance Forward Pass Kernels in NVIDIA CUDA Tile
 articleScale Agentic Coding Workflows with Meta’s Muse Spark Open on NVIDIA GB300 NVL72
 articleOptimizing Agent Reliability and Tool Calling Efficiency for Chip Design Using NVIDIA NeMo Gym
 articleHow NVIDIA Groq 3 LPX Deterministic Execution Drives Power-Efficient High-Interactivity Inference on NVIDIA Vera RubinTanya Lenz
 articleNVIDIA Vera Rubin and Blackwell Set a New Standard for Agentic AI Performance per WattElizabeth Goodman
- postGemma 4 31B hits 3,400 tokens/s on NVIDIA's new inference rackArtificial Analysis
Checking sign-in…
Loading comments…