DeepSeek V4.1 Flash lands on AA-AgentPerf with NVIDIA and AMD results
- Source
- x.com
- Date

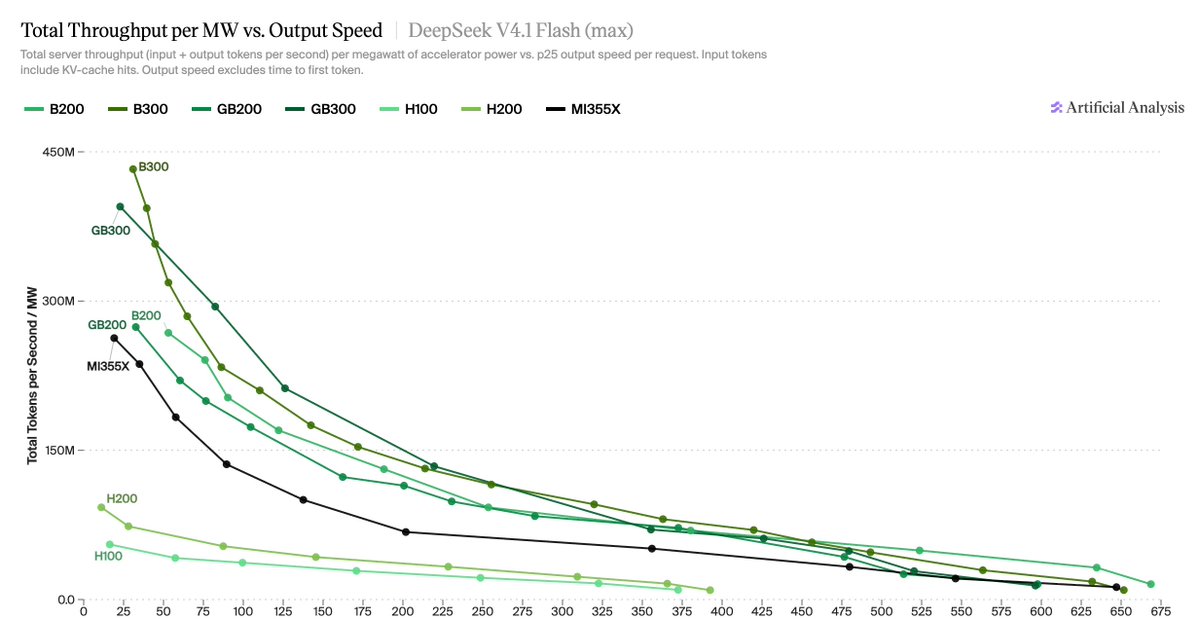
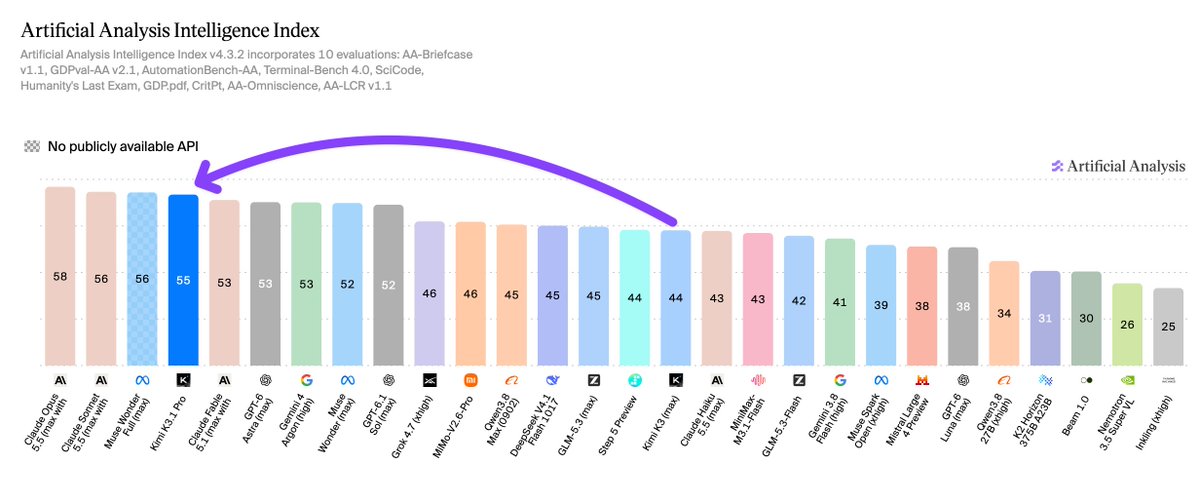
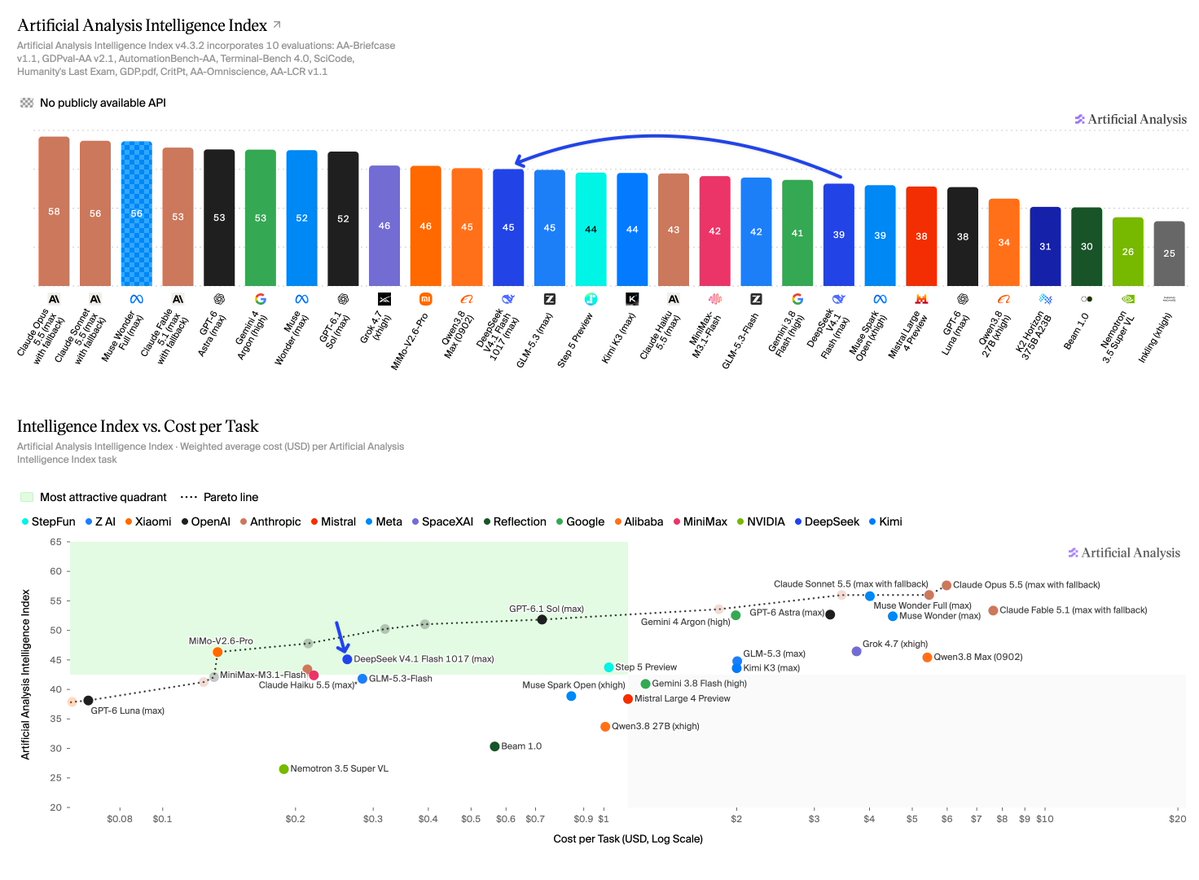
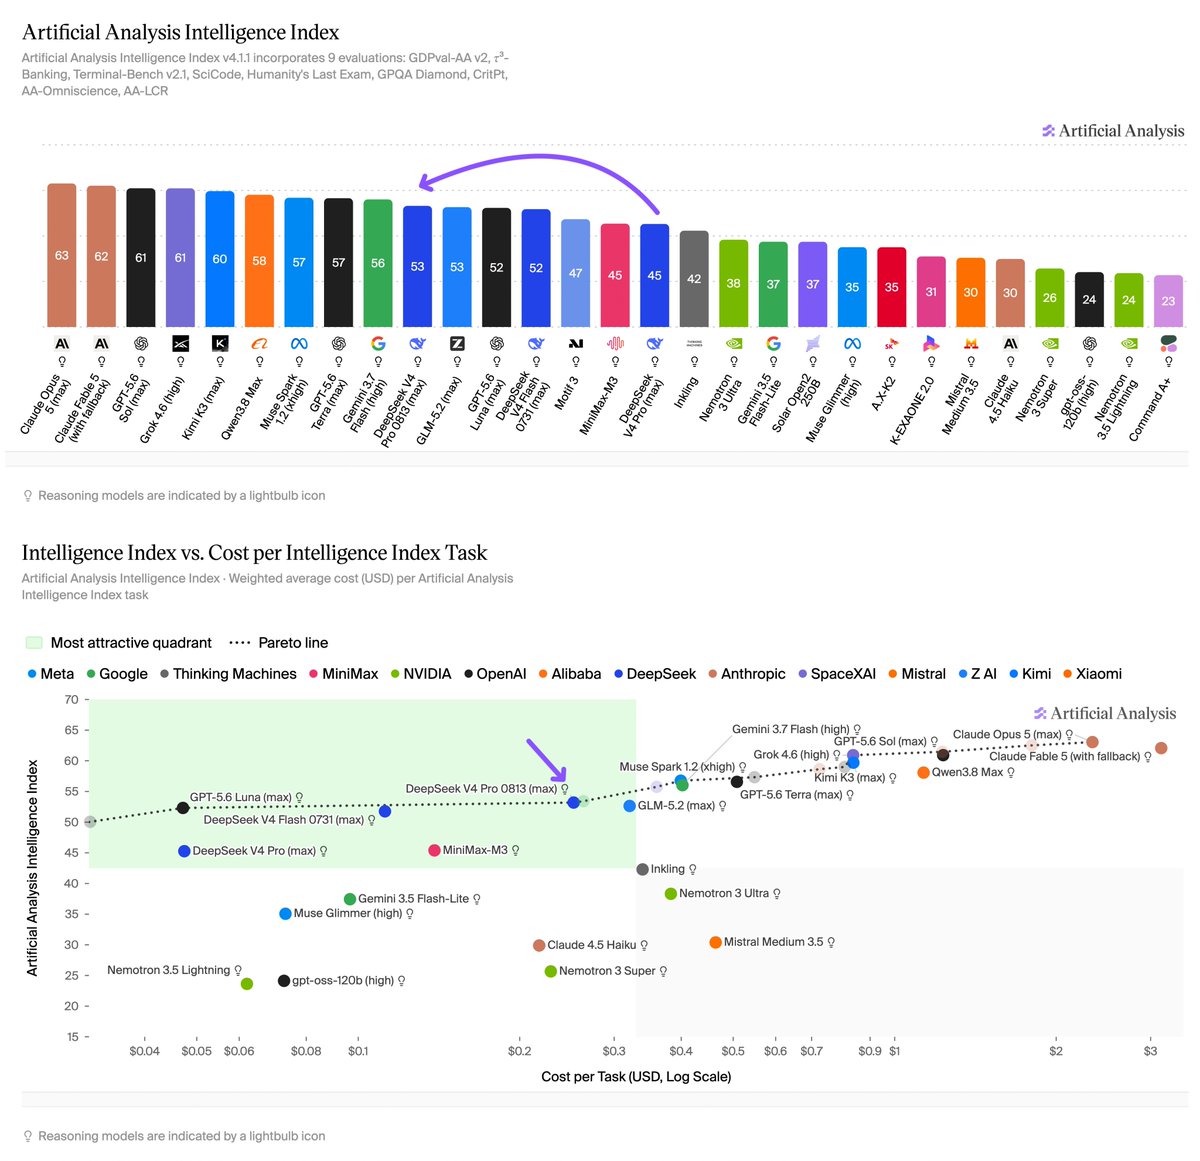
We’ve added DeepSeek V4.1 Flash to AA-AgentPerf, with results for NVIDIA and AMD hardware. At 100 tokens/s per user, NVIDIA GB300 is in first place with throughput up to 261M tokens/s per MW. AA-AgentPerf is our agentic inference performance benchmark. It replays real agentic coding sessions, including prompt caching and tool-call delays, to give a realistic measure of inference performance in day-to-day agentic workloads. We measure total system throughput per megawatt of runtime power, and per-agent output speed at varying concurrency levels, to show the trade-off between system utilization and individual user experience. DeepSeek V4.1 Flash joins the leaderboard today. It brings the leaderboard to four featured models, joining DeepSeek V4 Pro 0813, Kimi K3, and GLM-5.2/5.3. We are evolving the featured models as popular new open-weights models release, and will feature day-0 results for major future releases. Background on DeepSeek v4.1 Flash: ➤ It scores 39 on the Artificial Analysis Intelligence Index, ahead of DeepSeek’s earlier V4 Pro 0813 at 36, with about a third of the parameters (552B ‘backbone’ and 16B active, against 1.6T and 49B) ➤ It is built on a new…
Context
Artificial Analysis evaluates serving hardware by holding individual speed in view while measuring total throughput per unit of power. Its AA-AgentPerf test replays coding sessions, including reused prompt content and pauses for tool calls, to compare how systems behave as more agents run concurrently. Benchmark description.
For the V4.1 Flash model, it reports GB300 leading at a target of 100 output tokens per second per user, with approximately 261 million tokens per second per megawatt. The result concerns aggregate serving efficiency at that user-speed target. It gives operators a way to compare capacity without ignoring the speed each agent receives. Reported result.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.

Checking sign-in…
Loading comments…