Qwen3 Max Thinking Everything You Need To Know
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
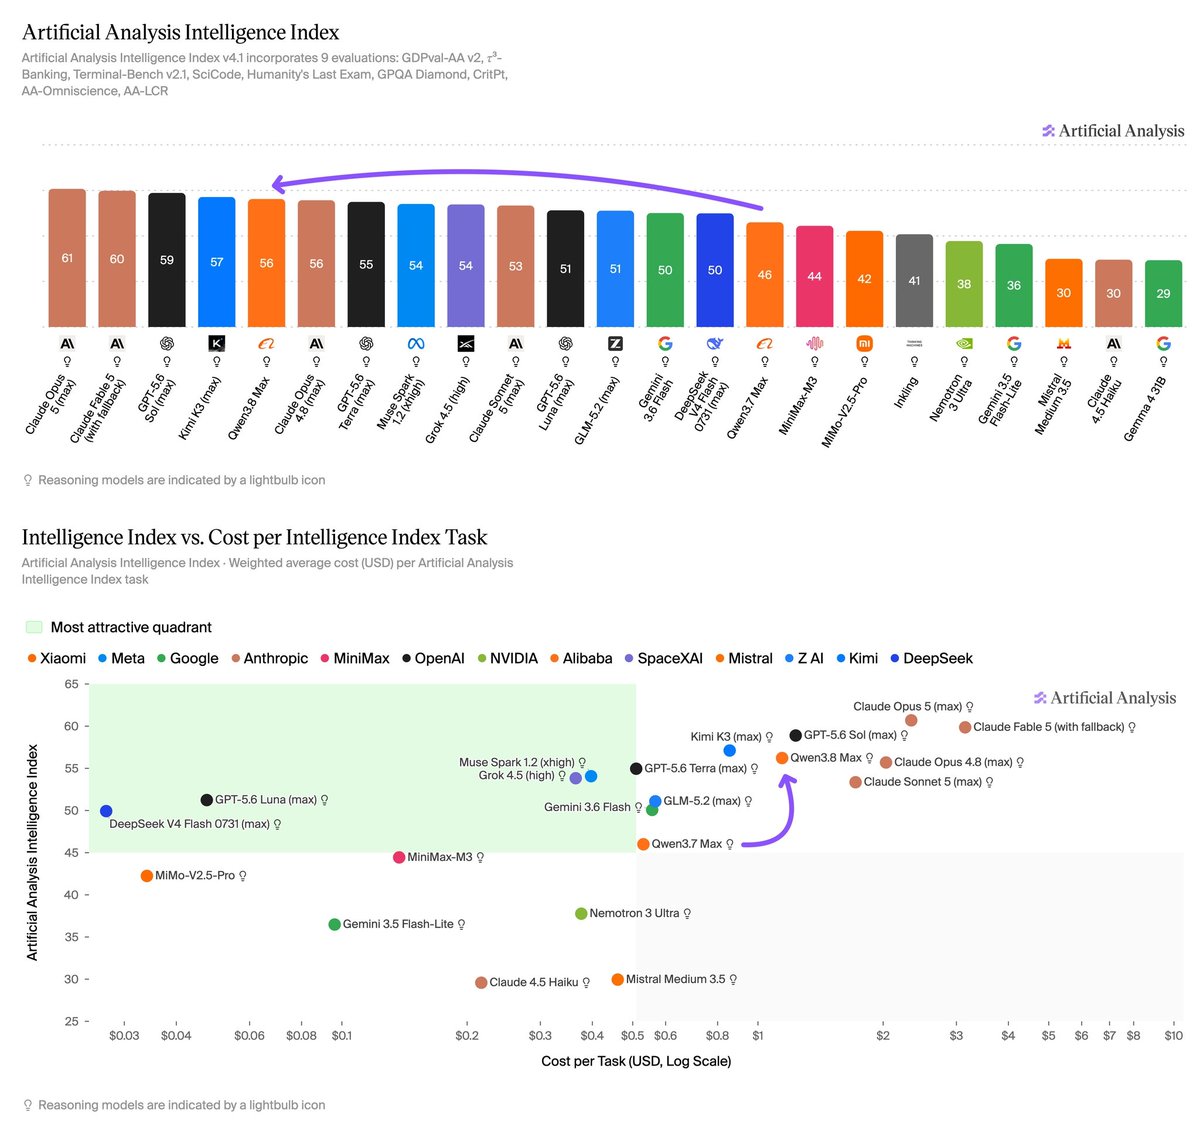
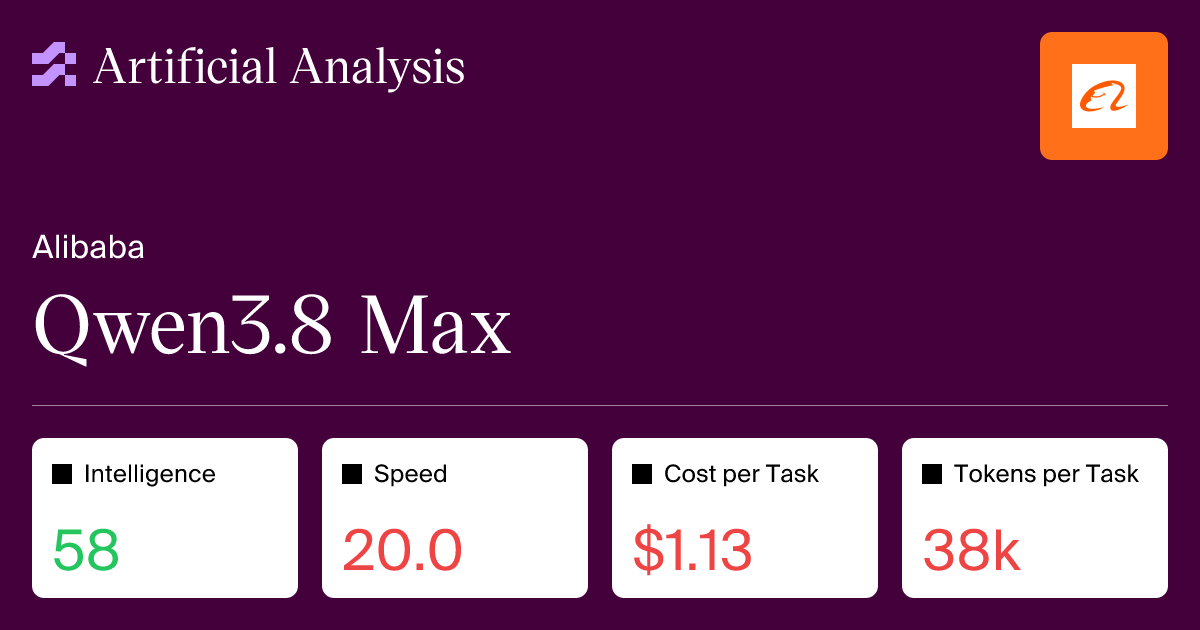
Alibaba's Qwen3-Max-Thinking is the company's flagship proprietary , and this January 29, 2026 analysis from Artificial Analysis shows a clear gain that still leaves it behind models anyone can download. It scored 40 on Artificial Analysis's Intelligence Index, 8 points above the Preview version's 32 and well above the open weights Qwen3 235B 2507 at 29. That ties MiniMax-M2.1 but sits behind DeepSeek V3.2 and GLM-4.7, both at 42, and Kimi K2.5 at 47, all open weights models, whereas Alibaba has not released Qwen3-Max-Thinking's weights (artificialanalysis.ai).
The upgrade is concentrated in general reasoning and instruction following. Its score on Humanity's Last Exam doubled from the Preview to 26%, ahead of DeepSeek V3.2 at 22%, GLM-4.7 at 25% and MiniMax-M2.1 at 22%, and its IFBench score, a test of following complex instructions, rose to 71% from 54%, narrowly ahead of Kimi K2.5 at 70% and GLM-4.7 at 68%.
Where it still trails is agentic work and knowledge reliability. On GDPval-AA, Artificial Analysis's measure of models doing realistic knowledge work such as preparing presentations and analysis, given shell access and web browsing through the firm's Stirrup , its Elo rose to 1170 from the Preview's 958. That is ahead of MiniMax-M2.1 at 1074 but behind GLM-4.7 at 1192, DeepSeek V3.2 at 1186 and Kimi K2.5 at 1316. On AA-Omniscience, which the article describes as a knowledge evaluation measuring both accuracy and rate, it scored -34, behind Kimi K2.5 at -11, DeepSeek V3.2 at -23 and MiniMax-M2.1 at -30. Its token use nearly tripled from the Preview, to 86M output tokens to complete the index from 30M, though Artificial Analysis calls that in line with peers such as Kimi K2.5 at 89M and well below GLM-4.7 at 167M.
- Most of the 8-point gain over the Preview comes from general reasoning and instruction following: Humanity's Last Exam doubles to 26%, and IFBench rises from 54% to 71%, ahead of Kimi K2.5 (70%) and GLM-4.7 (68%).
- On GDPval-AA, run with shell and web access through Artificial Analysis's open-source Stirrup harness, its Elo rises from 958 to 1170, still behind GLM-4.7 (1192), DeepSeek V3.2 (1186) and Kimi K2.5 (1316).
- Token use nearly tripled from the Preview: 86M output tokens (79M of them reasoning) to run the Intelligence Index versus 30M, in line with Kimi K2.5 (89M) and well below GLM-4.7 (167M).
- Pricing scales with input length: $1.2/$6 per 1M input/output tokens up to 32K input, $2.4/$12 for 32K-128K and $3/$15 for 128K-256K. It is text-only, with a 256K , via Qwen Chat and Alibaba Cloud.
- reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.




Checking sign-in…
Loading comments…