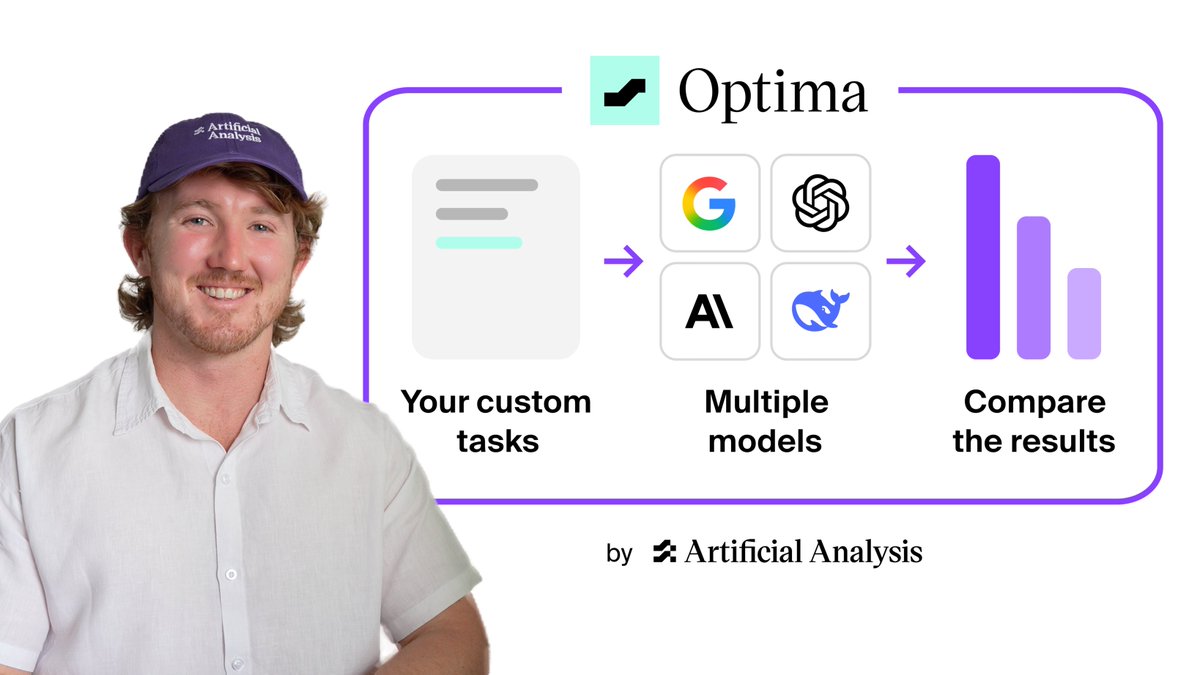
Optima lets a team compare AI models on examples of its own work. Artificial Analysis, which provides model evaluations, describes a process in which users supply context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → and examples, help develop tasks and grading criteria, then run those tasks across models. Results include quality scores, cost and completion time. The product page also supports testing a team's own AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition →.
This makes the evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → question concrete: which model performs acceptably on these tasks at an acceptable expense and delay? The usefulness of the answer depends on the examples and grading criteria representing the work the team actually needs done.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.