Sakana Fugu puts a multi-agent system behind one model API
- Source
- sakana.ai
- Author
- Sakana AI
- Date
Context
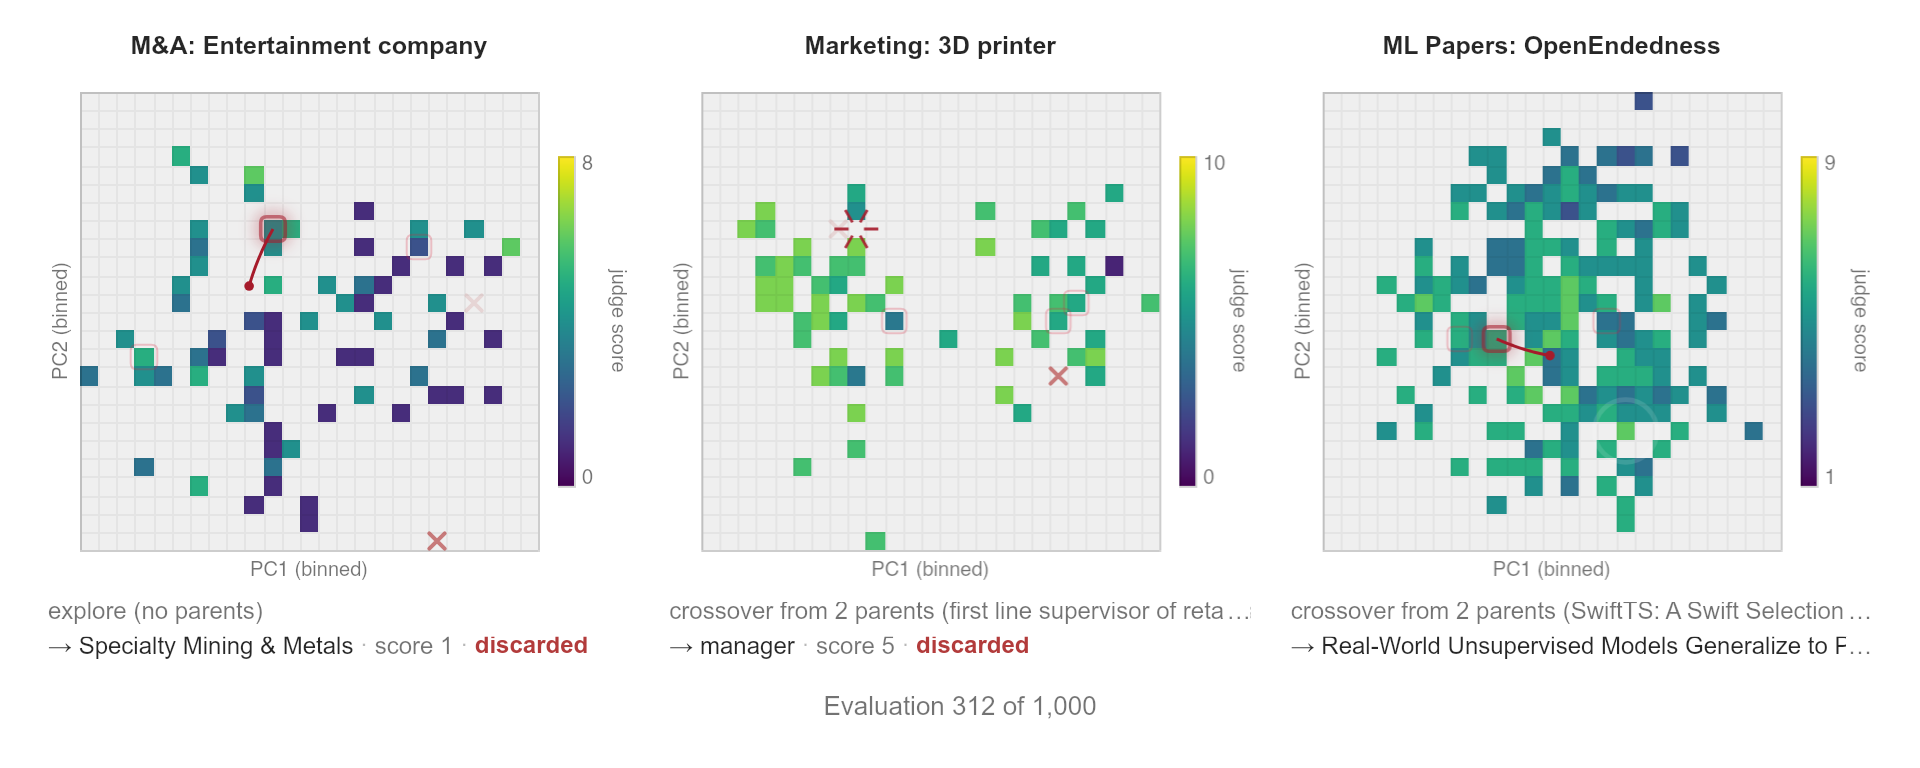
Sakana Fugu is a model API from Sakana AI whose answers come from a team of other AI models rather than one. An application sends an ordinary request; behind the endpoint, Fugu chooses which models in its pool to involve, how to split the work and how to combine the results. Sakana's product page says Fugu learns these arrangements instead of following a workflow a person designed, and grounds the approach in two ICLR 2026 papers. The page summarizes them as follows; the papers themselves were not reviewed for this explanation. In TRINITY, a small evolved coordinator directs several models over multiple turns, assigning each a Thinker, Worker or Verifier role. In the Conductor, a model trained with reinforcement learning writes the coordination plan and focused prompts for the other models in natural language.
For a developer, the service looks like one OpenAI-compatible model. Sakana says existing clients and coding tools can point at the endpoint without an SDK change. Customers cannot see which underlying models answered a given request, because Sakana treats that routing as proprietary. On the base Fugu model they can exclude specific providers or models for privacy or compliance reasons, while the pools of Fugu Ultra and Fugu Max are fixed. Pay-as-you-go billing for Fugu charges a single rate, set by the top-tier model involved in the request, rather than adding up every model consulted. The service is not offered in the EU or EEA while Sakana works toward GDPR compliance.
The lineup has grown since the June 22, 2026 launch post, which introduced Fugu Ultra and claimed it matched Fable and Mythos. The page read here now lists four models: Fugu as the balanced everyday default, Fugu Ultra (now v2.0) for maximum answer quality at the cost of speed, Fugu Max for the best cost-performance tradeoff, and Fugu Cyber for security work. Its results are Sakana's own, include an internal coding benchmark, and compare against models Sakana selected; for example, it reports Fugu Ultra best or joint-best on five of eight benchmarks while noting that Fable 5, Fable 5.1 and GPT-6-Astra are not in that model's pool. Our coverage of the Fugu Max and Ultra v2 release explains the two newer tiers.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…