Building Federated Multimodal AI Workflows with NVIDIA FLARE
Source
developer.nvidia.com
Author
Tanya Lenz
Date
Context
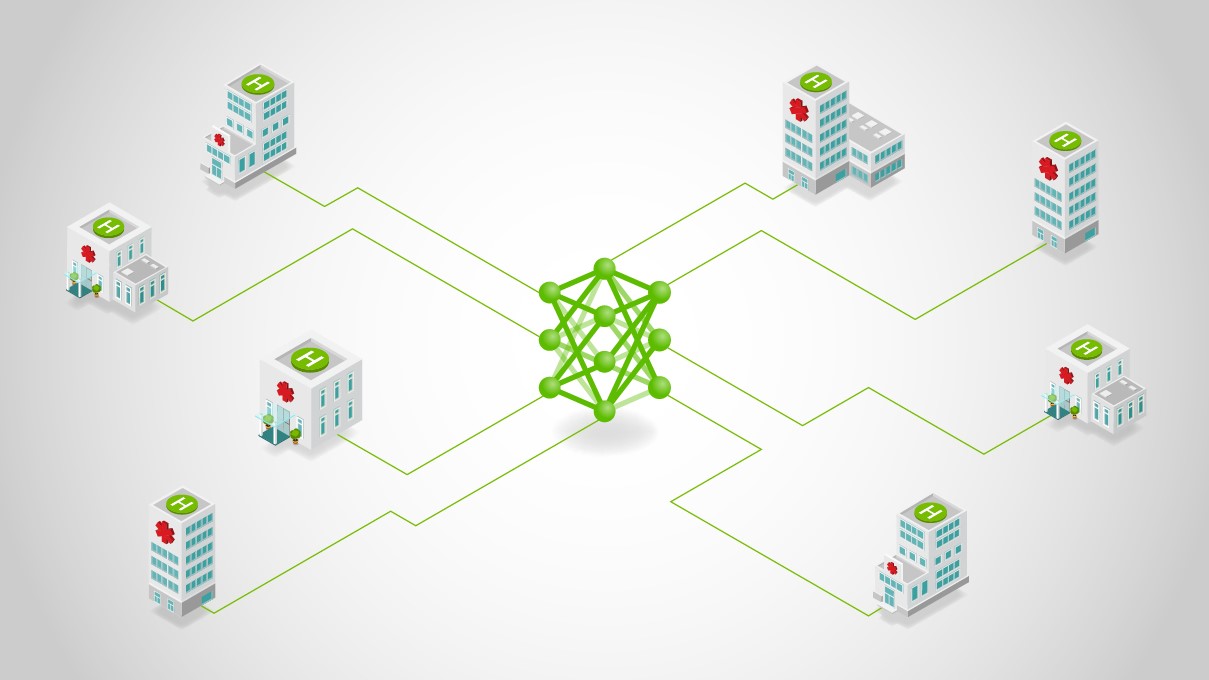
Training across separate organizations can become expensive even when their raw data stays local: the model updates still have to travel. NVIDIA describes a smaller exchange in FedUMM's FLARE workflow. Each client keeps the base model fixed and trains small adapter components; the server combines those updates.
In an eight-client simulation, this reduced communication per client per round from 28.6 GB to 0.094 GB, while the reported visual-question-answering score improved by 0.7 points against full-model averaging. The result supports reducing update size in that experimental setting, which used public benchmarks and simulated sites.
Terms in this piece · Glossary
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
 articleScaling NVIDIA TensorRT Performance Optimization Beyond a Single Build Route with the Global Performance Tuner, Part 2
 articleAccelerating Mamba-2 with High-Performance Forward Pass Kernels in NVIDIA CUDA Tile
 articleScale Agentic Coding Workflows with Meta’s Muse Spark Open on NVIDIA GB300 NVL72
 articleOptimizing Agent Reliability and Tool Calling Efficiency for Chip Design Using NVIDIA NeMo Gym
 articleScaling Federated Learning Across Docker, Kubernetes, and Slurm with NVIDIA FLAREElizabeth Goodman
 articleNVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal ReasoningMichelle Horton
 articleWhen to Use Encode-Prefill-Decode Disaggregation to Accelerate Multimodal Model ServingTanya Lenz