A 30B Apache 2.0 model that runs at full context on one H100 or at 4-bit on a high-end laptop, but its agentic knowledge work score is below its size class.
Key takeaways · AI-distilled
Muse Glimmer uses three sliding-window attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → layers per global layer. Artificial Analysis reports that this limits its minimum KV cacheThe memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.Full definition → to about 1.8 GB at 128K context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, reducing memory needs beyond weight compression.
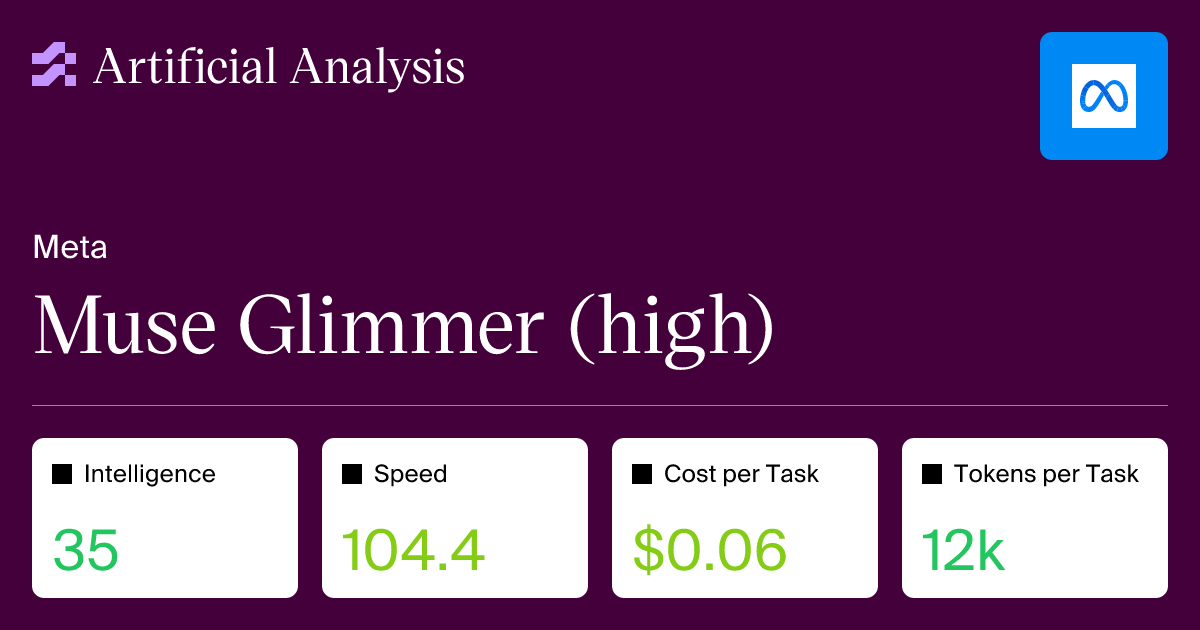
Artificial Analysis reports that Muse Glimmer's factual accuracy matches peers, but its 82% hallucinationWhen a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.Full definition → rate is higher. Similar answer accuracy can therefore conceal a different tendency to answer when uncertain.
Muse Glimmer's results vary across agent tasks. It trails similarly sized Qwen3.6 27B on GDPval-AA v2 and Terminal-Bench, while scoring higher on Tau3-Banking in the reported evaluation.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.