Ring-2.6-1T opens up with two reasoning effort levels
- Source
- Ant Ling
- Date

🚀 Ring-2.6-1T is now open source. A trillion-scale flagship thinking model built for real-world complex tasks: Agent workflows, coding & engineering, long-horizon tasks, complex reasoning, research, and enterprise automation. It is designed to move beyond “answering” toward execution: understanding context, planning steps, calling tools, and staying stable across long task chains. Highlights: - Advanced agentic workflow support. - Reasoning effort levels: high for agentic tasks, xhigh for complex reasoning. - Scalable asynchronous RL via the IcePop algorithm, enabling stable, trillion-scale training for long-horizon agentic RL.
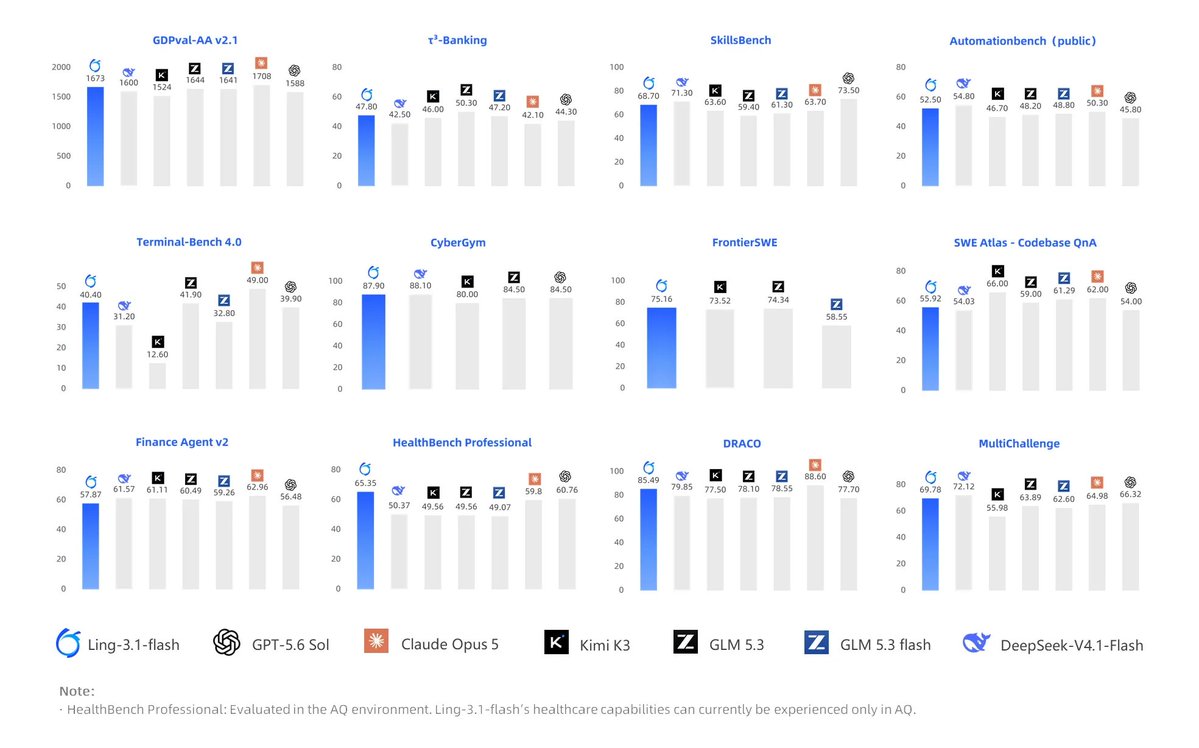
1/ Ring-2.6-1T shows strong performance across both Agent execution and hard reasoning. Agent / workflow benchmarks with high: • PinchBench: 87.60 • ClawEval: 63.82 • Tau2-Bench Telecom: 95.32 • Gaia2-search: 75.40 • SWE-Bench Verified: 74.00 Hard reasoning benchmarks with xhigh: • AIME 26: 95.83 • GPQA Diamond: 88.27 • ARC-AGI-V2 Pass@2: 66.18 high is built for efficient production Agent workflows. xhigh is built for deeper reasoning when the task needs more thinking. Fast when needed. Deep when necessary.

2/ Demo: Code Generation In Pi Coding Agent, we asked Ring-2.6-1T to search the web for different web design aesthetics and generate a large set of interactive guides in those styles. This demo tests its tool use, task planning, visual translation, and front-end code generation capabilities.

3/ Demo: Bug Fixing in Productive Code Repo In OpenCode, we used Ring-2.6-1T inside a real project repository to locate and fix a series of style-adaptation bugs, then generate the related documentation. This demo tests its ability to explore a codebase, analyze issues, and solve problems in real engineering projects.

Context
A week after launching Ring-2.6-1T as a free trial on OpenRouter, Ant Ling released the weights for the same trillion-parameter model on Hugging Face and ModelScope. The company again describes two reasoning-effort levels, high for workflows and xhigh for harder reasoning, trained with what it calls the IcePop algorithm for stable asynchronous reinforcement learning at trillion-parameter scale, and repeats agent- scores including 87.60 on PinchBench and hard-reasoning scores including 95.83 on AIME 26 that mirror the launch post's numbers.
The thread also includes seven demonstrations Ant Ling says show the model researching and generating 3D scenes, fixing bugs in a real code repository, and building a personalized learning assistant, each run inside a named coding agent or workflow tool. The specific outputs of those demos were shown as video and are not independently assessed here beyond the company's written description of the task each one performed.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.


Checking sign-in…
Loading comments…