Gemini 4 Carbon takes #1 on Intelligence Index, second on coding agents
- Source
- x.com
- Date
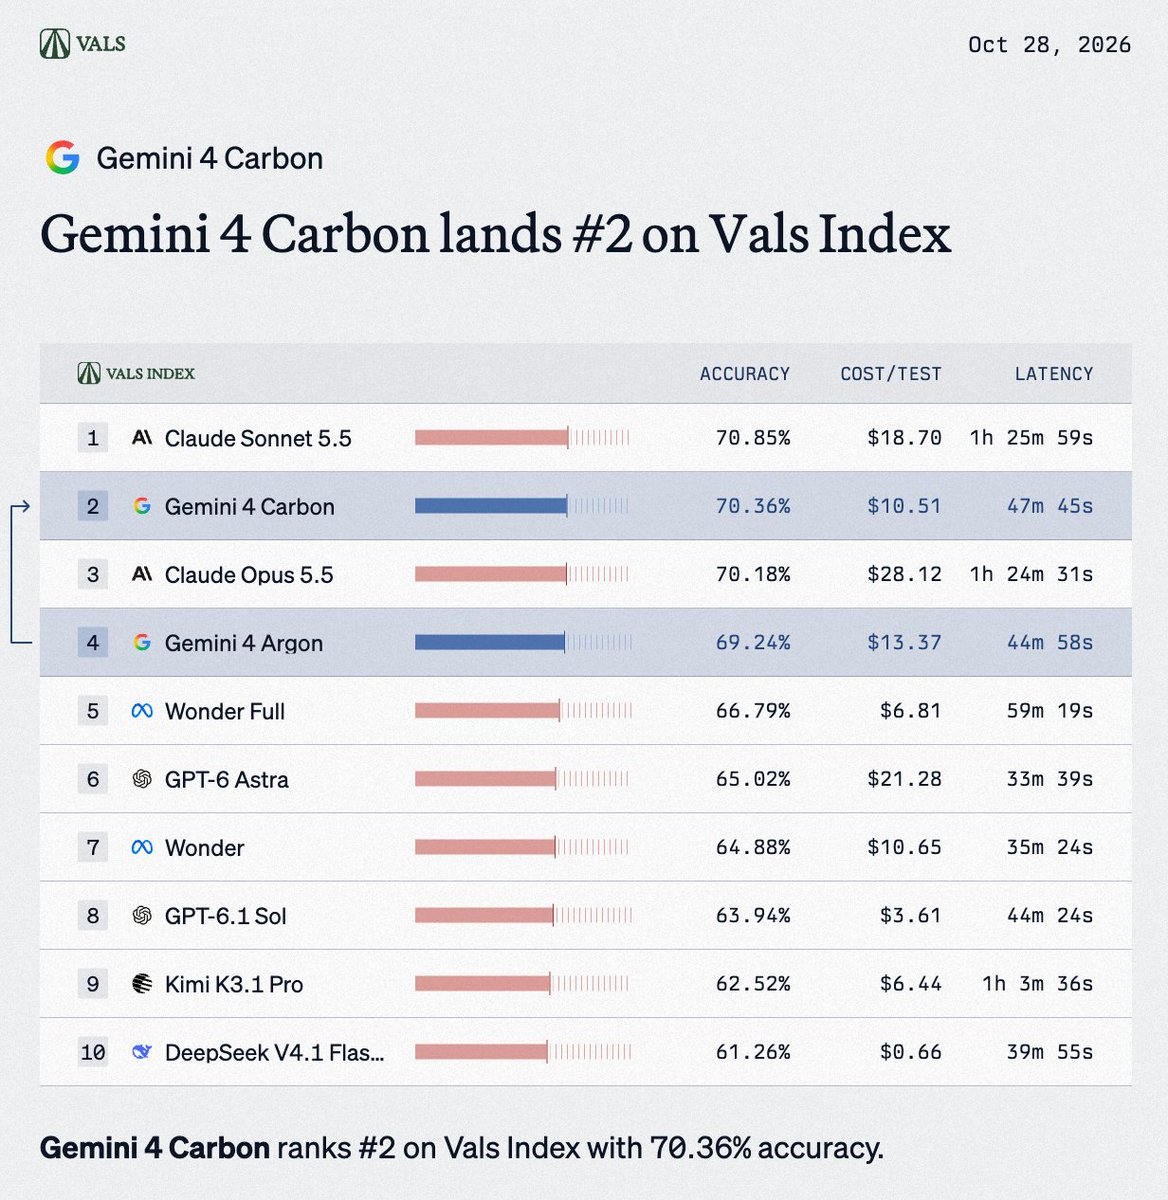
Artificial Analysis ranks Google's Gemini 4 Carbon first on its Intelligence Index v5 and second on its Coding Agent Index, behind Claude Opus 5.5. It lists pricing at $4/$20 per million tokens with a 1M context window, and reports that Carbon uses 29% fewer output tokens per task than Opus 5.5 on coding agent work. The same evaluation measures an 11% hallucination rate, up from 4% for Gemini 4 Argon. Vals AI places Carbon second on its Vals Index v2.2 and first on its Finance Index and Legal Research benchmark, but finds it spends 2.3x Argon's reasoning tokens and runs slower on agentic tasks, with legal tasks taking over 50 minutes each. Google's own announcement gives no benchmark figures and sends access first to vetted defenders in its Fairwind cyber program, with wider availability promised but undated. Benchmark researcher Jasper Dekoninck notes that Carbon trails Opus 5.5 by one point on the previous index version, 57 to 58, and leads by one on v5, so the top spot rests on a one-point gap and the timing of an index revision.

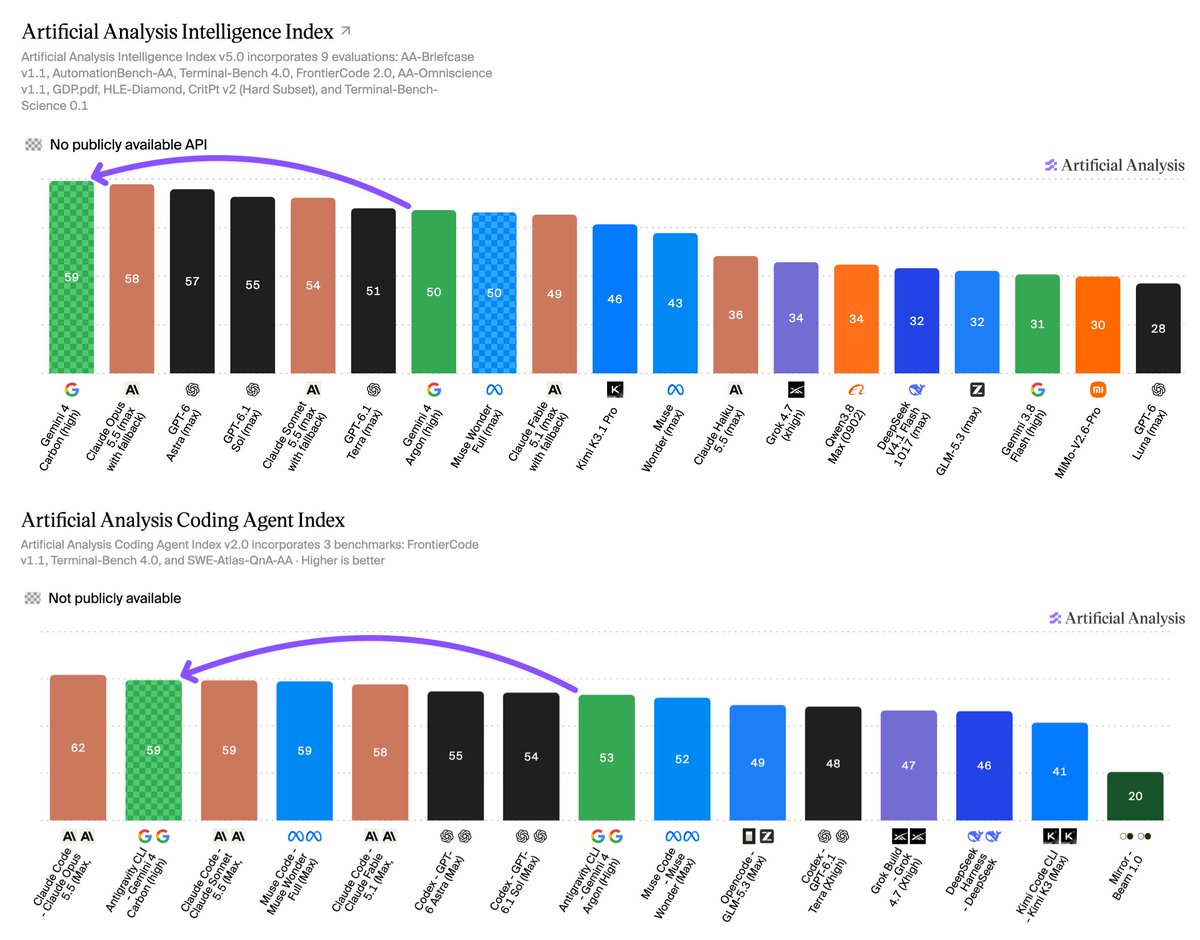
Google’s Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5, and second only to Claude Opus 5.5 on the Artificial Analysis Coding Agent Index Gemini 4 Carbon scores 59 on Intelligence Index v5, driven by leading performance in complex reasoning, knowledge, and scientific tasks. It also has large gains in coding and knowledge work, particularly when compared to other Gemini models, but it is not leading in all these areas. As with launch of Gemini 4 Argon, Gemini 4 Carbon is being rolled out to selected users and is not yet publicly available. Google is offering a 50% launch discount, with no confirmed end date. All our charts and figures use standard pricing for both Gemini 4 Carbon and Argon. Key results for Gemini 4 Carbon with high reasoning: ➤ Gemini 4 Carbon leads the Intelligence Index v5, with the #1 score in 4 of the 9 Index evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, AutomationBench-AA. Carbon makes substantial gains elsewhere but is not leading in coding and knowledge work ➤ Behind only Claude Opus 5.5 on coding agents: With Antigravity CLI, Gemini 4 Carbon (high) scores 59 only 3 points behind Claude Code with Claude…
Context
Google DeepMind's Gemini 4 Carbon now has the top score on Artificial Analysis's Intelligence Index v5, a composite of nine evaluations, but the lead rests on reasoning, knowledge and science tests rather than on every category. According to Artificial Analysis's results post, Carbon scored 59 with high reasoning and took first place on four of the nine evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience and AutomationBench-AA. It made large gains in coding and knowledge work, especially over earlier Gemini models, without leading either. Like Gemini 4 Argon before it, Carbon is being rolled out to selected users and is not yet publicly available.
Coding agents are the area where the improvement is most notable, because Artificial Analysis says Google has historically underperformed there. Running in Antigravity CLI, Carbon scored 59 on the Coding Index, 3 points behind Claude Code running Claude Opus 5.5 at max effort (62), and ranked second on both Terminal-Bench 4.0 and FrontierCode v1.1. On AA-Briefcase, which tests agentic knowledge work, it reached 1,609 Elo, 126 points above Gemini 4 Argon, but still trailed Grok 4.7 (1,638), Muse Wonder (1,659) and Kimi K3.1 Pro (1,678).
The cost comparison favors Carbon against Opus 5.5 but not against every rival. At standard pricing of $4 per million input and $20 per million output tokens, Carbon cost $7.76 per Intelligence Index task, about 23% less than Claude Opus 5.5 at max ($10.04) and about 1.2 times GPT-6 Astra at max ($6.25). Carbon also produced less output, using 123,000 output tokens per task against 173,000 for Opus 5.5. Google is offering a 50% launch discount with no confirmed end date, which Artificial Analysis left out of its figures.
Carbon's factual accuracy came with a trade-off. On AA-Omniscience v1.1 it scored 54, ahead of Opus 5.5 (48) and Argon (46), and answered 58% of questions correctly, 10 points more than Argon. Its rate also rose, from Argon's 4% to 11%. That is still the second lowest of any model Artificial Analysis lists, against 50% for both Opus 5.5 and GPT-6 Astra at max. The ranking is specific to the new index version: Artificial Analysis's explanation of v5 describes what the update changed, and a separate post examines how the order of Carbon and Opus 5.5 depends on which version is used.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.




Checking sign-in…
Loading comments…