Ox Alpha unmasked after 20 trillion tokens in six days
- Source
- x.com
- Date

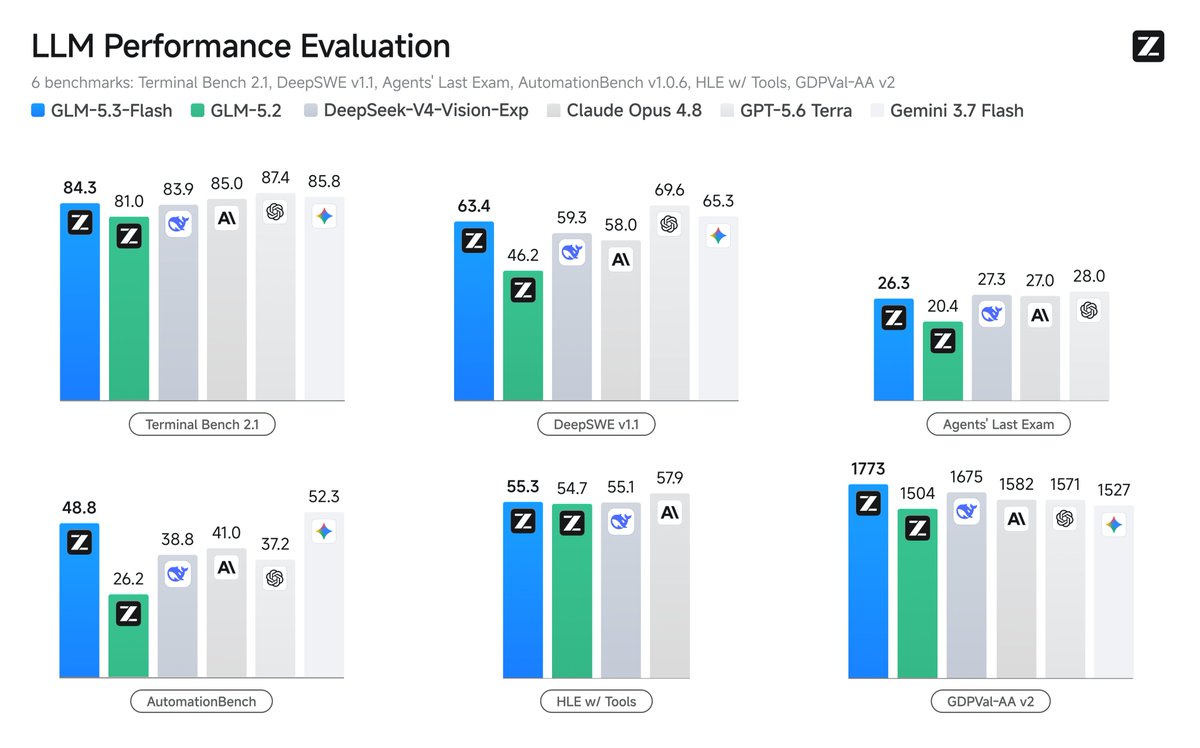
Ox Alpha revealed: @Zai_org’s GLM-5.3-Flash, the first native multimodal model in the GLM-5 series. Ox Alpha was the biggest model ever on OpenRouter, processing over 20 trillion tokens in 6 days. Continue to use the model now: https://t.co/avBrUW8BfZ

GLM-5.3-Flash is built for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture preserves accurate long-context capabilities while reducing compute overhead. We expect many providers to onboard this model throughout the week.

1M-token context. 131K max output. `max` reasoning by default. Launch pricing via @Zai_org is 50% off through Sep 9 at 16:00 UTC: $0.075/M input $0.25/M output $0.015/M cached input Then $0.15/M, $0.50/M, and $0.03/M.
Context
In an August 26, 2026 reveal, OpenRouter identified Ox Alpha as Z.ai's GLM-5.3-Flash, which it calls the first native model in the GLM-5 series. That ties the name to the model offered in Nous Research's earlier free-access announcement. OpenRouter's attached traffic chart for August 20-25, 2026 (UTC) shows 23.2 trillion tokens processed by Ox Alpha since launch, the most of any model on the chart. That figure counts text units handled on one platform, so it measures usage, not model size or answer quality.
The same thread describes GLM-5.3-Flash as built for efficient coding and long-horizon tasks, and says its hybrid sparse and linear design preserves long- accuracy while reducing compute. Those are OpenRouter's descriptions in the thread, not independent test results.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.




Checking sign-in…
Loading comments…