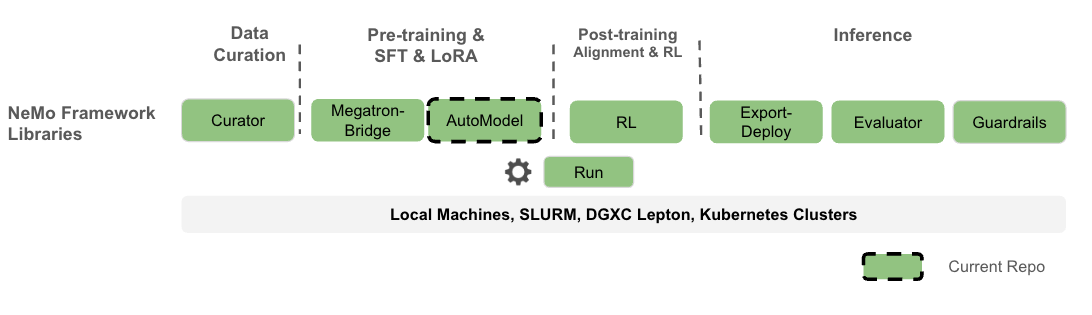
NeMo AutoModel ships day-0 fine-tuning for Qwen3.8-Flash-Next
Source
github.com
Author
Qwen
Date
Why it matters
If you fine-tune open weightsA model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.Full definition →mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → models, this documents a working SFT path for Qwen3.8-Flash-Next with FSDP2, EP64/128 and context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → parallelism, including the Engram table sharding. It also lists what is unsupported: TP, PP, MTP and vision.
Terms in this piece · Glossary
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.