Claude Sonnet 5 5
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
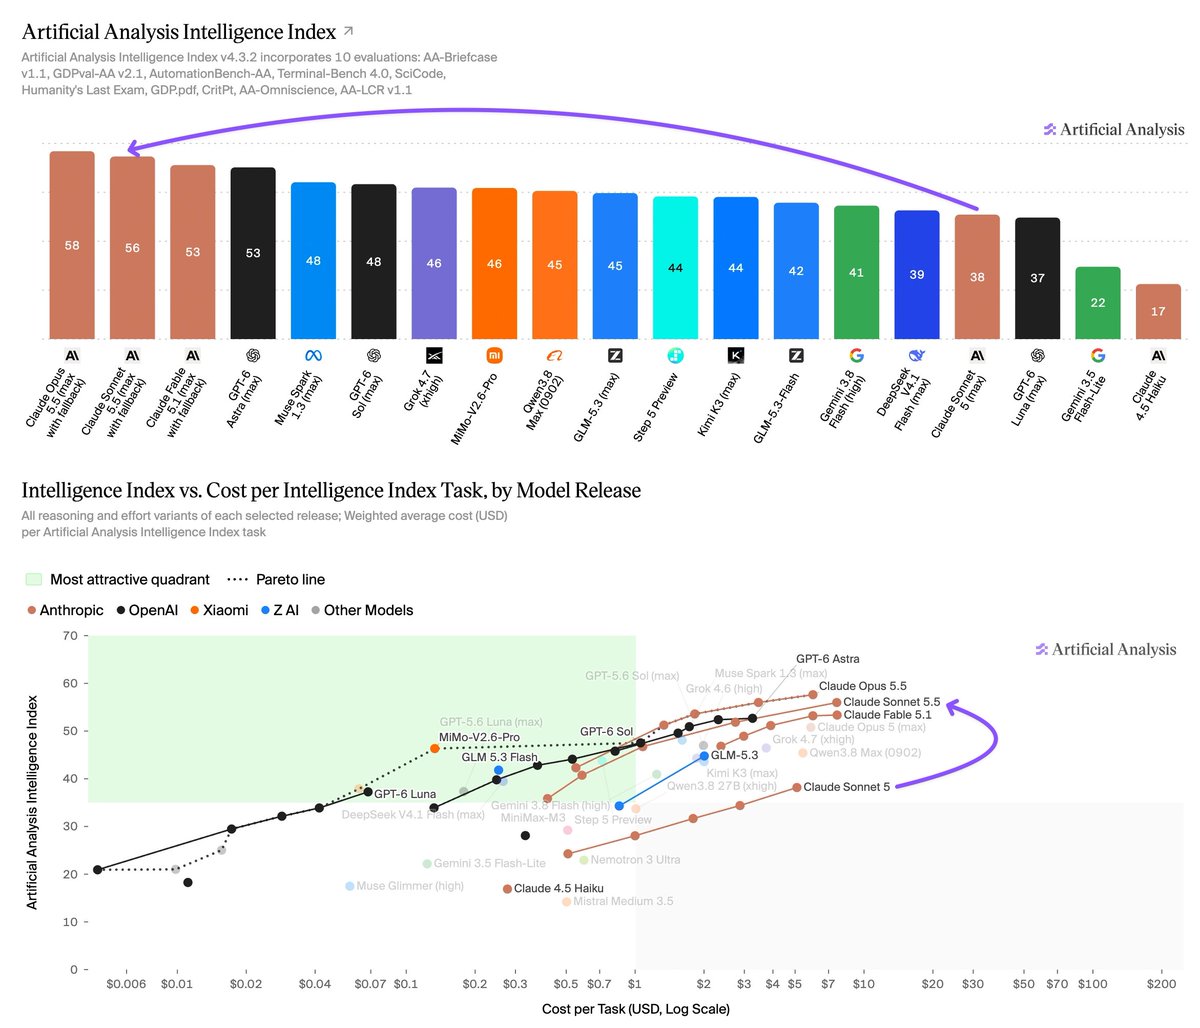
A lower-tier model can approach a larger model's score by spending substantially more effort on each task. Artificial Analysis' Sonnet 5.5 launch evaluation reports strong agentic results at maximum effort alongside unusually heavy output- use. That makes Anthropic's per-token price an incomplete guide to what a finished task costs.
The reported results also came from a pre-release deployment with a structured-output bug and default fallback enabled. The article says the bug was fixed for public release and planned relevant retests. Those conditions belong with the numbers: the launch describes that tested configuration, while different effort settings or the corrected release can produce a different balance.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.




Checking sign-in…
Loading comments…