STEP3-VL-10B claims 200B-class multimodal results at 10B parameters
- Source
- x.com
- Date

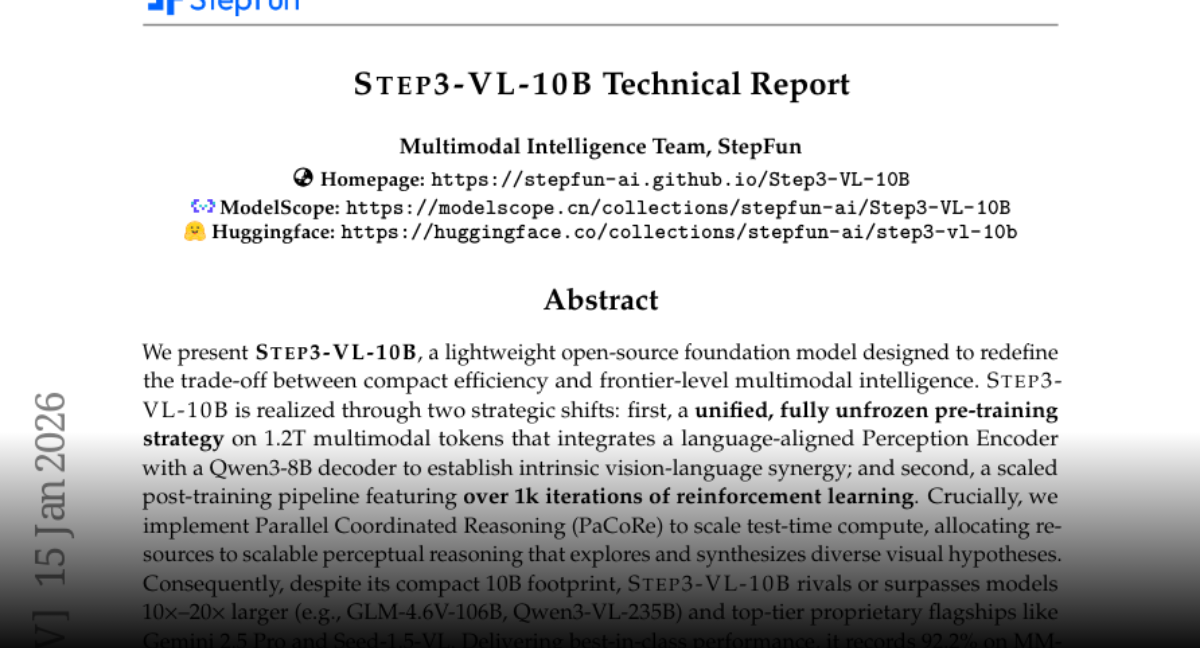
🚀10B parameters, 200B+ performance! Introducing STEP3-VL-10B : our open-source SOTA vision language model. 🥊 At just 10B, it redefines efficiency by matching or exceeding the capabilities of 100B/200B-scale models. SOTA Performance : ✅STEM/Multimodal: Outperforms GLM-4.6V (106B-A12B) and Qwen3-VL (235B-A22B) on MMMU, MathVision, MathVerse,etc. ✅Math: Near-perfect scores on AIME 24/25, achieving elite-level reasoning. ✅2D/3D Spatial Understanding: Beating same-scale models on BLINK/CVBench/OmniSpatial. ✅Coding:Dominates LiveCodeBench in real-world dynamic programming. Key Breakthroughs: 🔹 1.2T token full-parameter pre-training. 🔹 1,400+ RL iterations for superior reasoning. 🔹 Innovative PaCoRe tech for dynamic compute allocation. 💡We prove that scale isn't everything. With high-quality targeted data and systematic post-training, a 10B model can go toe-to-toe with the industry's largest giants." 📱Complex AI reasoning is now accessible for every device. Check out the Base & Thinking versions on HuggingFace now! Homepage:https://t.co/xn82bwwTzD Paper:https://t.co/flxKXRbCBW HuggingFace:https://t.co/6YV5wF6iai ModelScope:

ModelScope playground: https://t.co/MCI2UBWEAT
Context
StepFun released STEP3-VL-10B, a 10-billion-parameter open vision-language model, reporting scores that beat GLM-4.6V, a 106-billion-parameter model, and Qwen3-VL, a 235-billion-parameter model, on reasoning benchmarks such as MMMU and MathVision. StepFun attributes this to 1.2 trillion tokens of full-parameter , over 1,400 reinforcement-learning iterations refining its reasoning, and a technique it calls PaCoRe that allocates compute dynamically during rather than using a fixed amount for every query.
These benchmark comparisons are StepFun's own reported results rather than an independent leaderboard placement, and the announcement does not specify how GLM-4.6V or Qwen3-VL were run for the comparison. StepFun published a paper, weights for both a base and a thinking variant, and hosted playgrounds on Hugging Face and ModelScope, letting outside groups reproduce the comparison on their own hardware.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
 postStepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE
Checking sign-in…
Loading comments…