See Artificial Analysis for further details and benchmarks:
Source
artificialanalysis.ai
Author
ArtificialAnlys
Date
Context
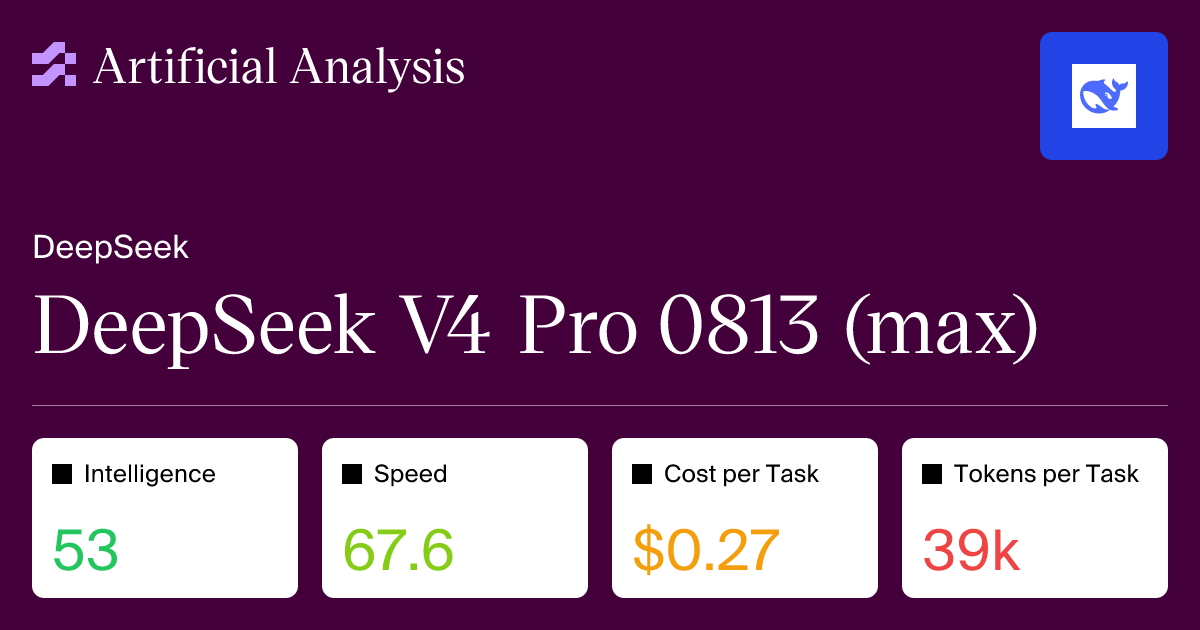
Artificial Analysis's evaluation page, checked on October 12, 2026, identifies the tested model as DeepSeek V4 Pro 0813 at its maximum reasoning setting. It reports an Intelligence Index score of 36 and an average benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition →-task cost of $0.67. These describe different trade-offs: the score summarizes performance, while task cost accounts for the text consumed and generated, including reasoning. The index methodology combines ten evaluations. Its task-cost figure is useful for interpreting that benchmark workload, rather than estimating the price of an arbitrary production request.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
 articleDeepseek V4 Flash 0731 Scores 50 On The Artificial Analysis Intelligence Index 10 Points Above Previous Deepseek V4 FlashArtificial Analysis articles
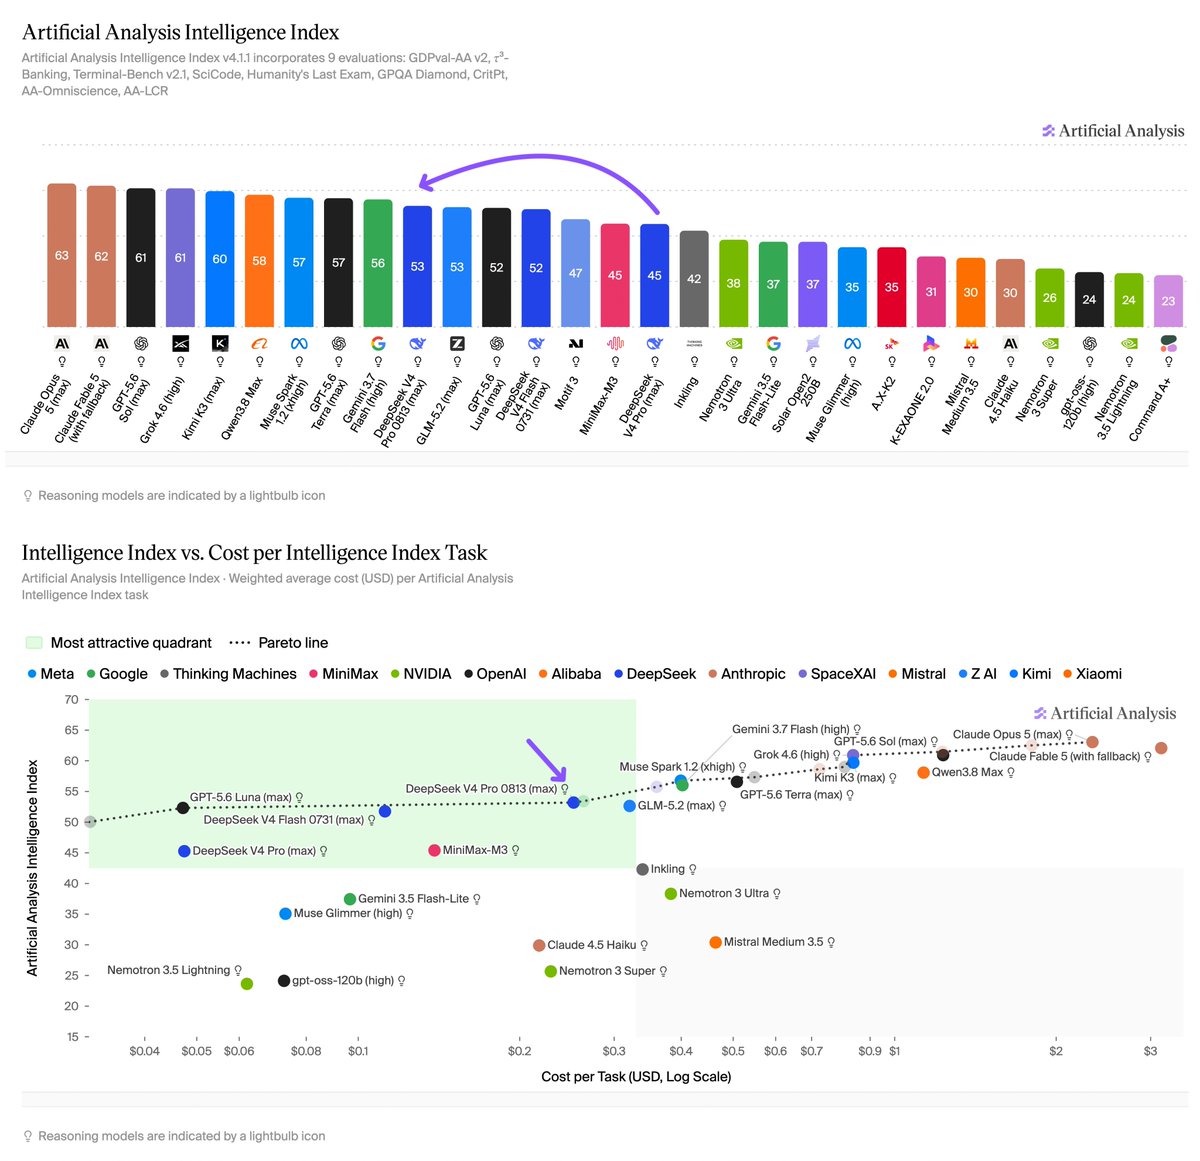 postDeepSeek V4 Pro 0813 scores 53 on the Artificial Analysis Intelligence Index, 8…Artificial Analysis
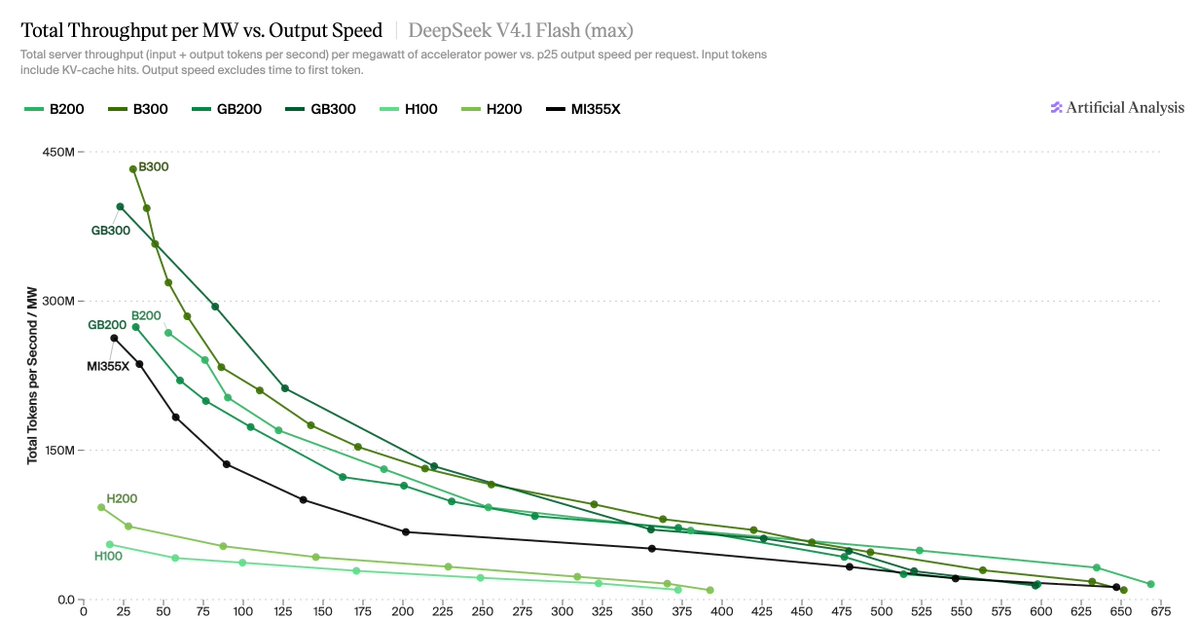
 postDeepSeek V4.1 Flash Beats Its Own Flagship on Price and PerformanceArtificialAnlys