Gemini 4 Carbon New Number 1
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
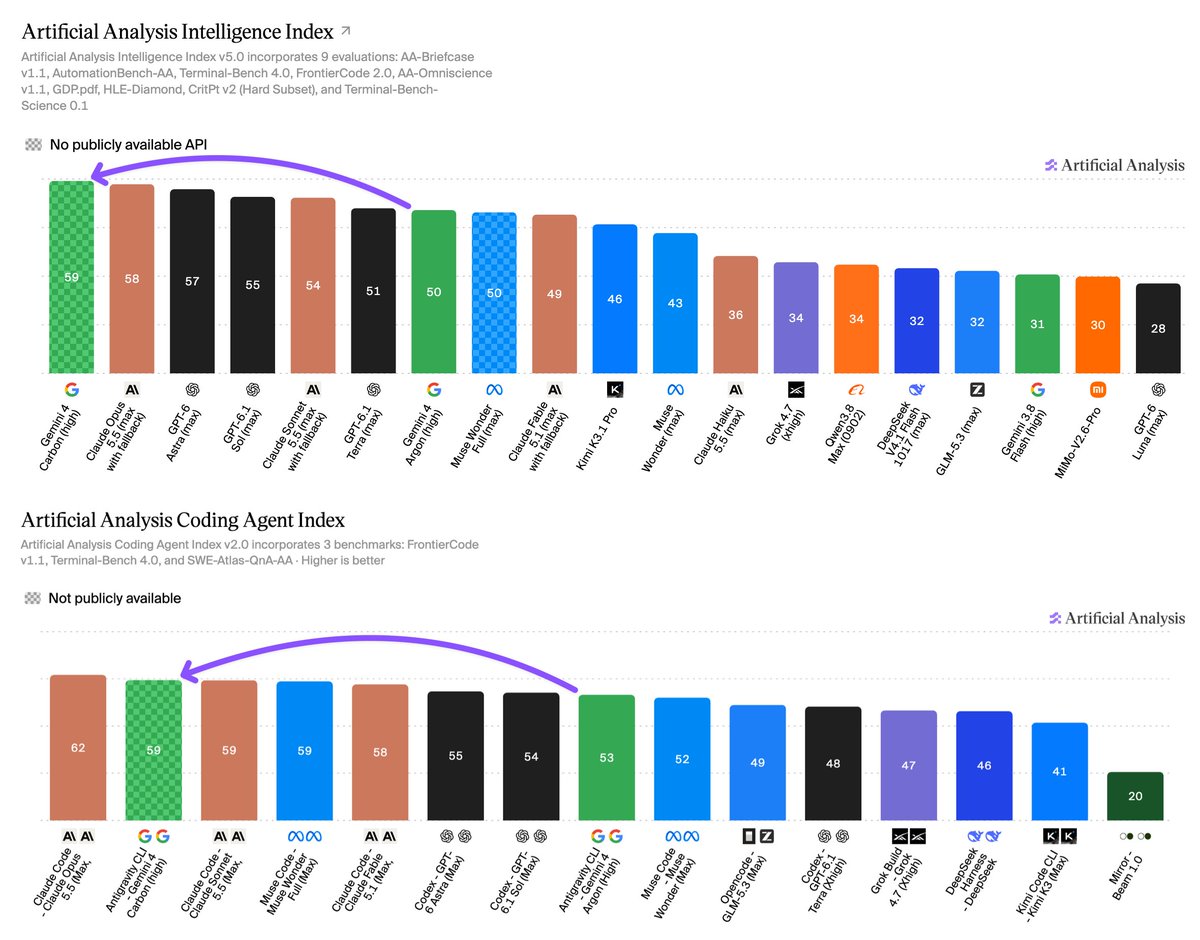
Artificial Analysis, an independent firm that runs the same tests on every major AI model, ranks Google's Gemini 4 Carbon first on its new Intelligence Index v5 with a score of 59. The lead is one point: the v5 announcement, published the day before, had Claude Opus 5.5 on top at 58. The lead also depends on the new version. Jasper Dekoninck pointed out that on the previous v4.3.2, by his figures, Carbon scores 57 against Opus 5.5's 58. Version 5 gives knowledge work, coding, science and general questions 25% each across nine evaluations, and Artificial Analysis says 60% of it now rests on private test sets or held-out answers.
Carbon has the top score on four of those nine evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience and AutomationBench-AA. It does not lead everywhere. On AA-Briefcase, a test of agentic office work, it scores 1609 Elo, 126 points above Gemini 4 Argon but behind Grok 4.7, Muse Wonder and Kimi K3.1 Pro. On the firm's separate Coding Index, which scores a model running inside its coding tool, Carbon in Google's Antigravity CLI reaches 59, three points behind Claude Code with Opus 5.5 at 62. Artificial Analysis calls that the standout result because Google has historically trailed on coding agents.
The factual-knowledge result comes with a trade-off. AA-Omniscience carries 15% of the index, split between 10% for accuracy and 5% for not hallucinating. Carbon's accuracy rose 10 points over Argon to 58%, while its rate rose from 4% to 11%. Artificial Analysis notes that 11% is still the second lowest of any model it tests, behind only Argon, against 50% for both Opus 5.5 and GPT-6 Astra at their maximum settings.
Most people cannot use Carbon yet. Google is rolling it out first to a subset of cyber defenders and trusted partners, with developers, businesses and consumers to follow later. Google is also running a 50% launch discount, so Artificial Analysis priced its comparisons at the standard $4 per million input and $20 per million output tokens. On that basis Carbon costs $7.76 per index task, about 23% less than Opus 5.5 at $10.04 and about 1.2 times GPT-6 Astra at $6.25, and it uses 29% fewer output tokens than Opus 5.5.
- Artificial Analysis ranks Gemini 4 Carbon (high reasoning) #1 on its Intelligence Index v5 at 59, leading 4 of 9 evaluations: HLE-Diamond, Terminal-Bench-Science, AA-Omniscience and AutomationBench-AA. It is rolling out to selected users, not yet public.
- On AA's Coding Agent Index, Gemini 4 Carbon in Antigravity CLI scores 59, 3 points behind Claude Code with Opus 5.5 (max, 62). AA notes Google has historically underperformed on coding agents, which is why the gain stands out.
- At standard $4/$20 pricing, Carbon costs $7.76 per Index task, about 23% less than Claude Opus 5.5 (max, $10.04) but about 1.2x GPT-6 Astra (max, $6.25). It uses 123k output tokens per task, 29% fewer than Opus 5.5.
- Carbon leads AA-Omniscience v1.1 at 54, with accuracy up 10 points over Argon to 58%. Its hallucination rate also rises, from 4% to 11%, which AA says is still the second lowest of any model, versus 50% for Opus 5.5 (max) and GPT-6 Astra (max).
- On agentic knowledge work (AA-Briefcase) Carbon reaches 1609 Elo, up 126 over Argon, but trails Grok 4.7 (1638), Muse Wonder (1659) and Kimi K3.1 Pro (1678). Its largest gain is in Presentation, up 293 Elo to 1598.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
 articleVials Aa
 articleThinking Machines Releases Inkling 2 Small Highest Scoring Open Weights Model Outside Of Chinia Upon Weights Release It
 articleNanbeige Has Released Nanbeige4 3 33b Scoring 20 On The Intelligence Index
 articleGithub Copilot Fusion Orchestrates Anthropic And Openai Models To Balance Performance And Cost
Checking sign-in…
Loading comments…