For more details and full results, see:
- Source
- artificialanalysis.ai
- Author
- ArtificialAnlys
- Date
Context
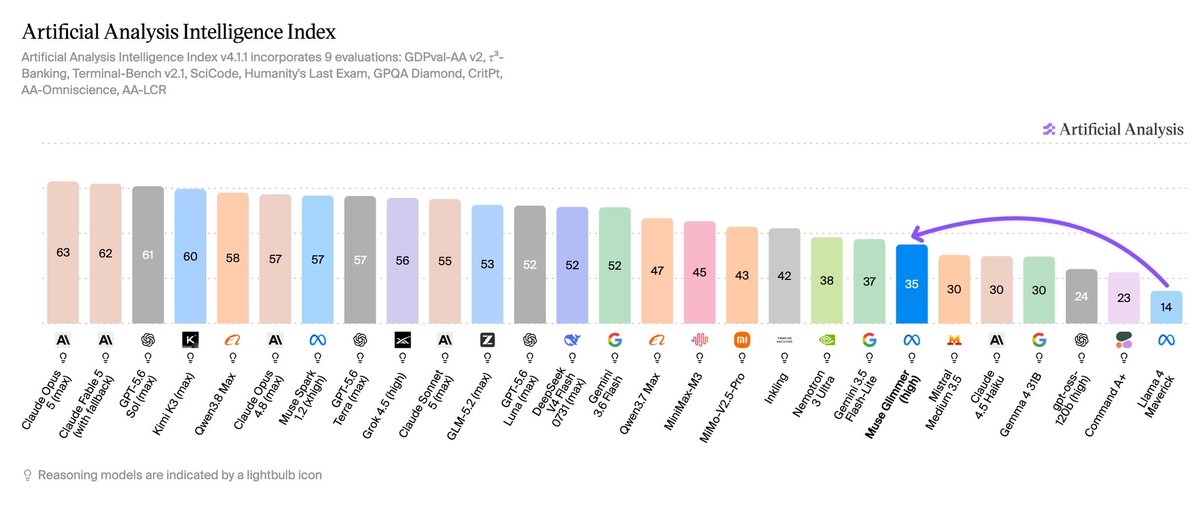
Meta's Muse Glimmer was scored on two different tests in Artificial Analysis's August 10 . It reached 953 Elo on GDPval-AA v2, which evaluates realistic knowledge-work deliverables through an agent workflow, below that test's 1,000 human baseline. It completed 24% of tasks on the separate banking tool-use . The launch analysis reports both results.
These tests ask different things of the model, and an Elo rating and a task-completion percentage are not on the same scale, so the two numbers cannot be ranked against each other. Producing a useful professional deliverable involves more than using tools in a banking workflow. The results support evaluating Glimmer against the particular job it will perform, rather than treating agent capability as one uniform strength.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
Checking sign-in…
Loading comments…