Ant Ling Clarifies Ling-3.0-Flash-Fin's True Size: 124B Total, 5.1B Active
- Source
- Ant Ling
- Date

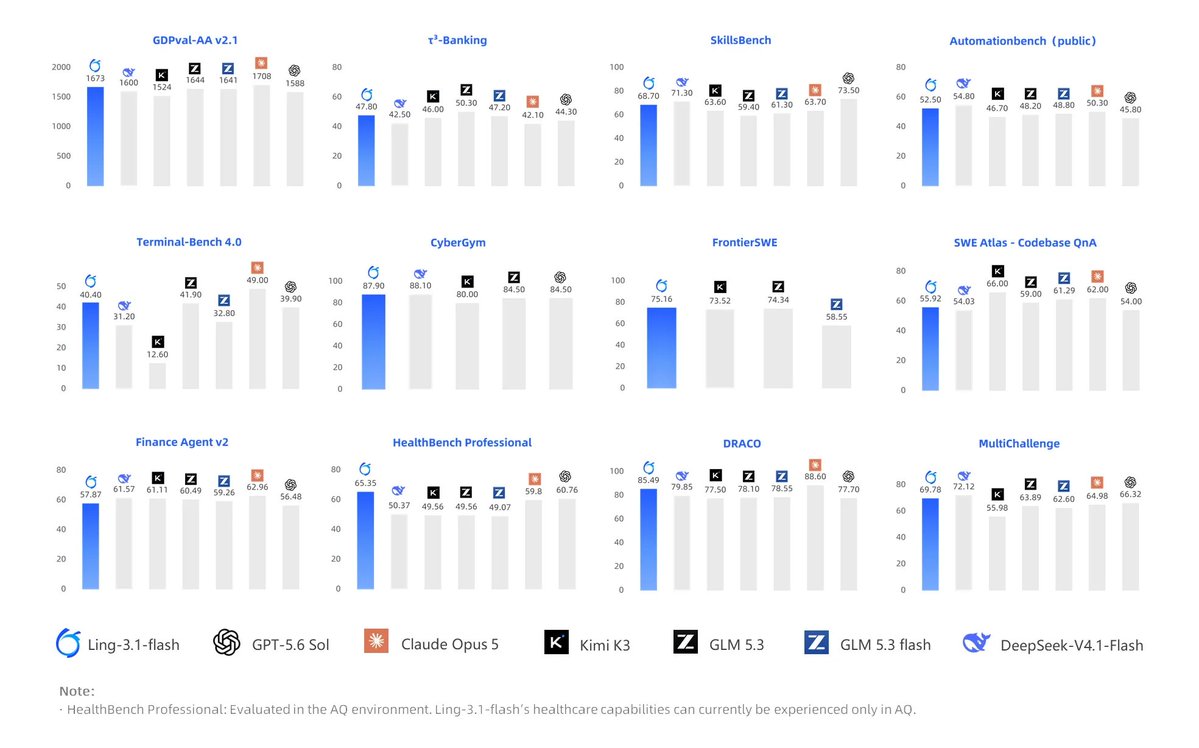
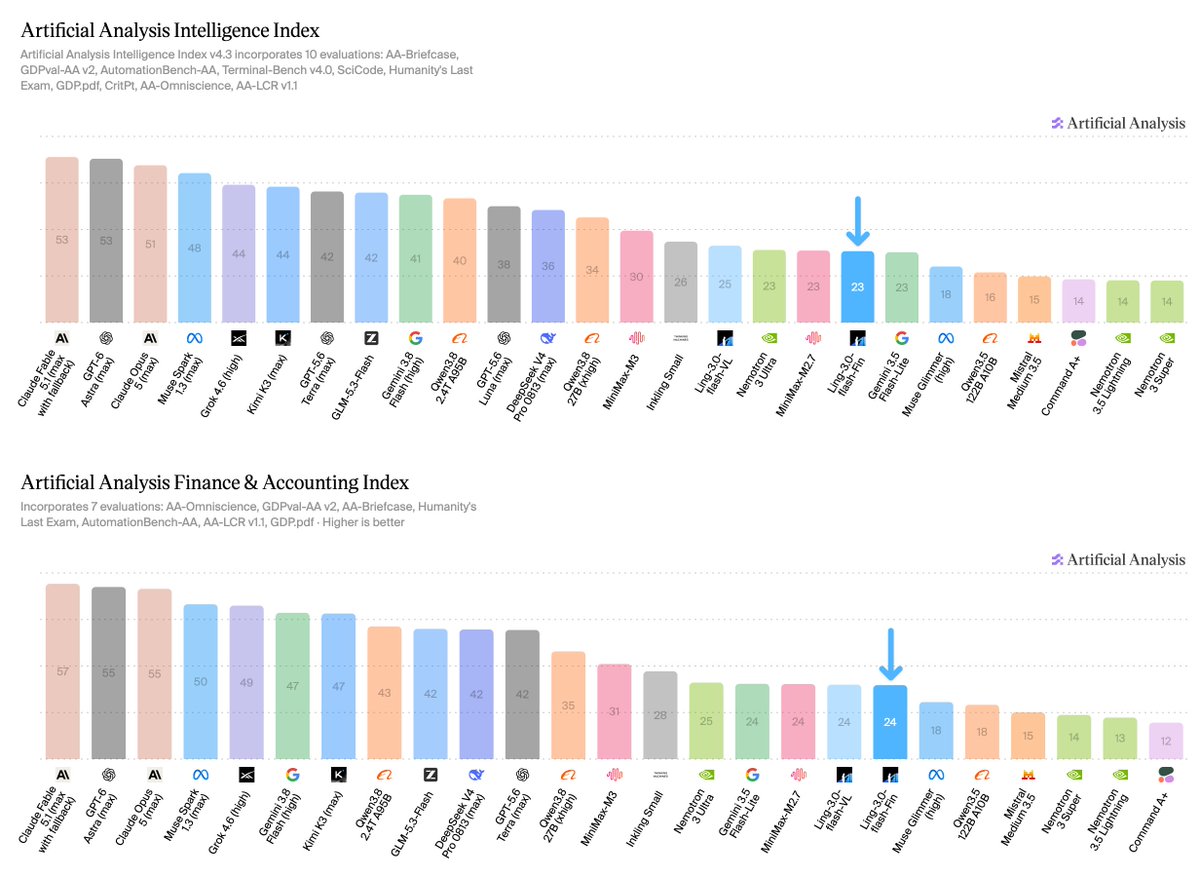
Thanks @ValsAI for the high-caliber eval! The term "flash" is a bit "misleading" now. With 124B total size and 5.1B activation, Ling-3.0-flash-fin is a "flash lite" with high intelligence density. Enjoy the free API while it last. We also have fp4 quant to be used on local AI 😛 https://t.co/SO2wIBC7jN
Context
InclusionAI's Ling-3.0-flash-Fin is not as small as its name suggests, according to the Ant Ling account, which called the term flash a bit misleading. The model has 124 billion total parameters and 5.1 billion active ones, meaning the portion used to process each . Ant Ling describes it as a flash lite model with high intelligence density.
Ant Ling also says an fp4 version exists for running on local AI hardware, which stores weights at lower precision, and invites readers to enjoy the free API while it lasts. The post thanks Vals AI for an but gives no results, so it supports the size and availability details, not any performance comparison.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.




Checking sign-in…
Loading comments…