Epoch: GPT-6.1 Sol long-context speedup hints at architecture change
- Source
- x.com
- Date

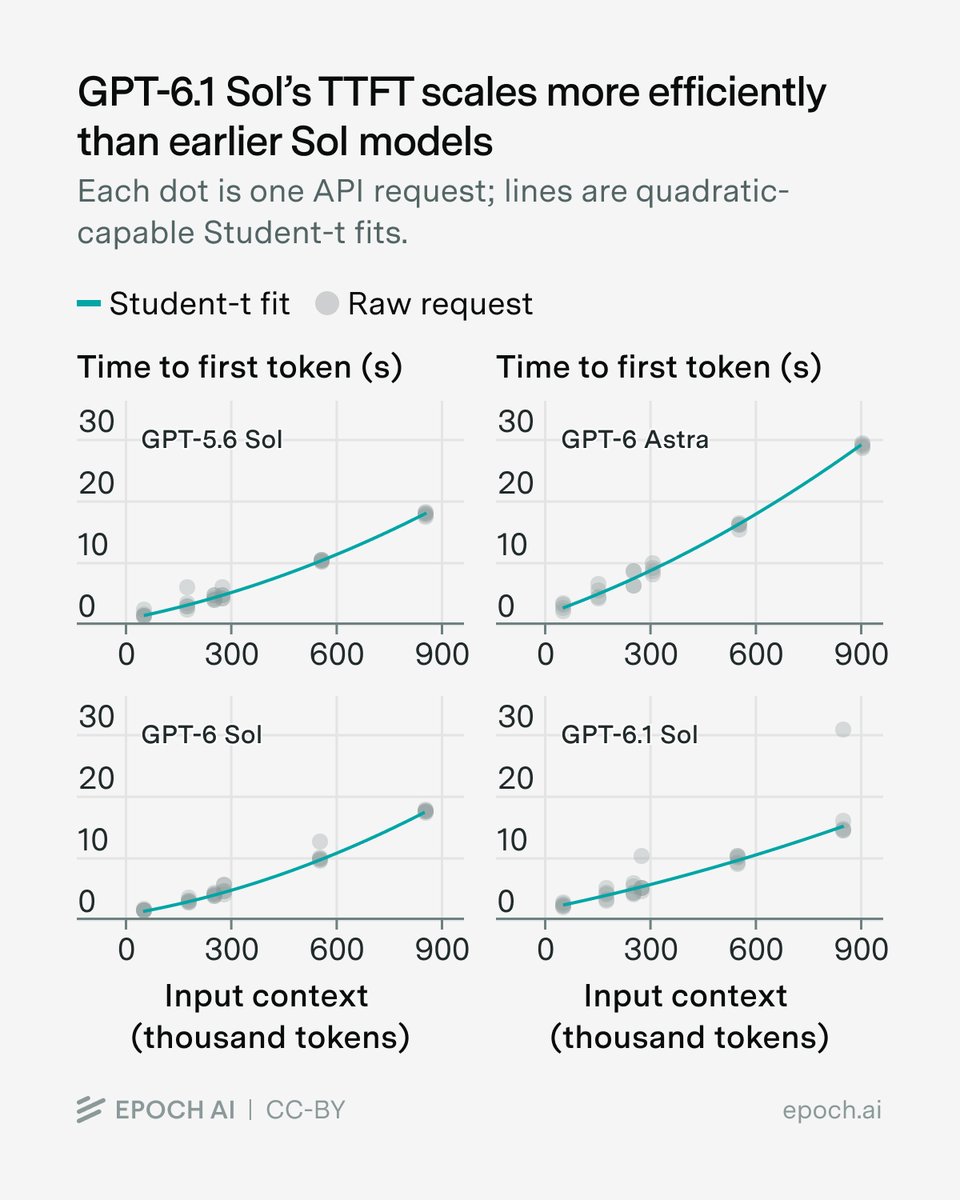
A new architecture for GPT-6.1 Sol? OpenAI halved its cached-input price compared with GPT-6 Sol. Our measurements show it also handles long prompts faster.
Context
Epoch AI measured that GPT-6.1 Sol, an OpenAI model, slows down less than GPT-5.6 Sol and GPT-6 Sol as prompts get very long, and floated a possible architecture change as the reason. In its post, Epoch notes that OpenAI halved the cached-input price relative to GPT-6 Sol (cached input is a prompt prefix the provider has already processed and re-bills at a discount).
The measured part is time to first , the wait before the first output appears, as the input grows to 900,000 tokens. According to the chart's alt text, GPT-6.1 Sol starts higher on short inputs but rises more slowly, reaching about 15 seconds at the longest versus about 17 seconds for GPT-5.6 Sol and GPT-6 Sol. The chart also includes GPT-6 Astra, whose result the alt text does not give.
The architecture idea is Epoch's , posed as a question in the post. A price cut and a flatter latency curve are both consistent with a change in how long inputs are handled, but nothing here shows what changed.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…