How Full-Stack NIM Optimizations Deliver 2.5x More Users on Nemotron 3 Ultra
- Source
- developer.nvidia.com
- Author
- Elizabeth Goodman
- Date
Context
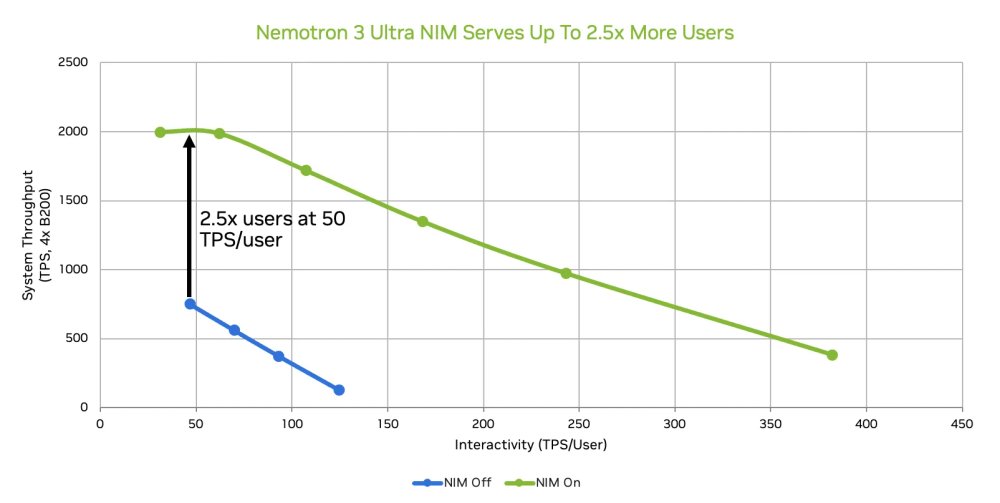
NVIDIA's Nemotron 3 Ultra serving study shows how software configuration can increase output from the same four B200 GPUs. Its benchmark table reports 1,997 output per second with NIM 2.0.12 versus 718 for the baseline, using a workload targeting 50 tokens per second per user and substantial reuse of previously processed .
The optimizations work together: cached context avoids repeated computation, while scheduling and memory settings allow more requests to proceed concurrently. NVIDIA also uses to propose output for verification. The study makes workload reuse and the required response rate central to interpreting the capacity gain.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
“Inference performance is a system property.”
“The published curves are a starting point, not a promise that every application will see the same result.”
“NIM turns this optimization work into a tested starting point.”
 articleHow NVIDIA OpenShell Reference Architecture Secures and Governs AI Agent Workloads at Scale
 articleCode, Test, and Deploy on One Machine with NVIDIA RTX Spark
 articleHow to Rewrite Apache Spark UDFs for GPU Acceleration with AI Agents
 articleLower the Cost of Building and Running Visual AI Agents with NVIDIA VSS Blueprint 3.3
 postNVIDIA Details Nemotron 3 Ultra NIM Serving Optimizations for 2.5x ConcurrencyNVIDIAAI
 articleFrom Wafer-Out to First Token: Codifying Supply Chain Expertise with Nemotron and Palantir FoundryElizabeth Goodman
 articleNVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal ReasoningMichelle Horton
Checking sign-in…
Loading comments…