Ling-3.0-flash weights released in BF16 and FP8
- Source
- Ant Ling
- Date

Today, we’re releasing the open weights for Ling-3.0-flash. 🎉 Official BF16 and FP8-quantized versions are now available, so you can choose the option that best fits your hardware, performance requirements, and deployment needs.

Get the Ling-3.0-flash weights here: 🤗 Hugging Face Official https://t.co/rCkfU23Li6 FP8 https://t.co/I6mZ1WhNQN 🤖 ModelScope Official https://t.co/hN7GJygYtG FP8 https://t.co/h7e4OGeWo6
With the weights in your hands, you’re free to take Ling-3.0-flash further. Run your own evaluations. Deploy it in your own environment. Adapt it to your use cases. Build it into your products, development toolchains, and agentic workflows. Download it, make it yours, and show us what you build. 🚀
A huge thank-you to the @sgl_project and @vllm_project communities for their continued, high-quality support! Your contributions have helped make Ling-3.0-flash easier and more efficient to deploy across diverse hardware and production environments. 🚀
Context
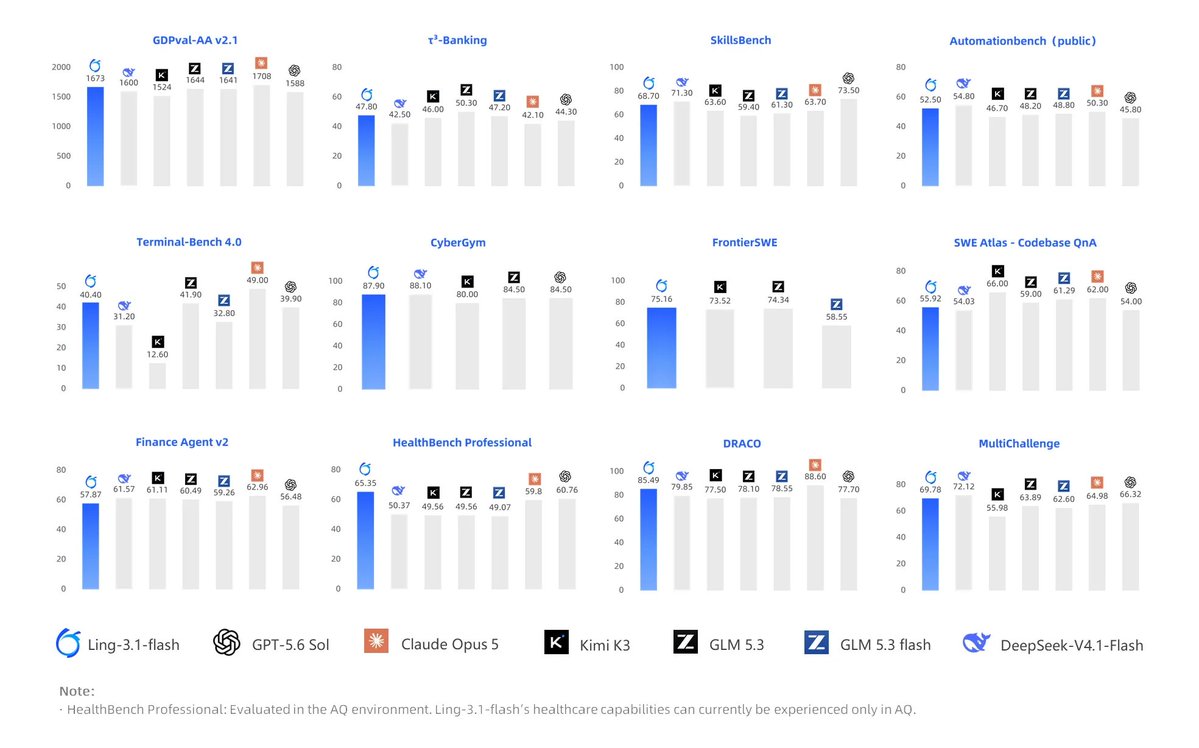
Two weeks after launching Ling-3.0-flash as a hosted model on OpenRouter, Ant Ling released its open weights in two forms: an official BF16 build and an FP8- version, published on Hugging Face and ModelScope. The company frames this as letting developers run their own evaluations, deploy the model in their own environment, and adapt it into their own products rather than depending on a hosted endpoint, and it credits the SGLang and vLLM open-source projects for helping make the model easier to deploy across different hardware.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.


Checking sign-in…
Loading comments…