Frontiercode
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
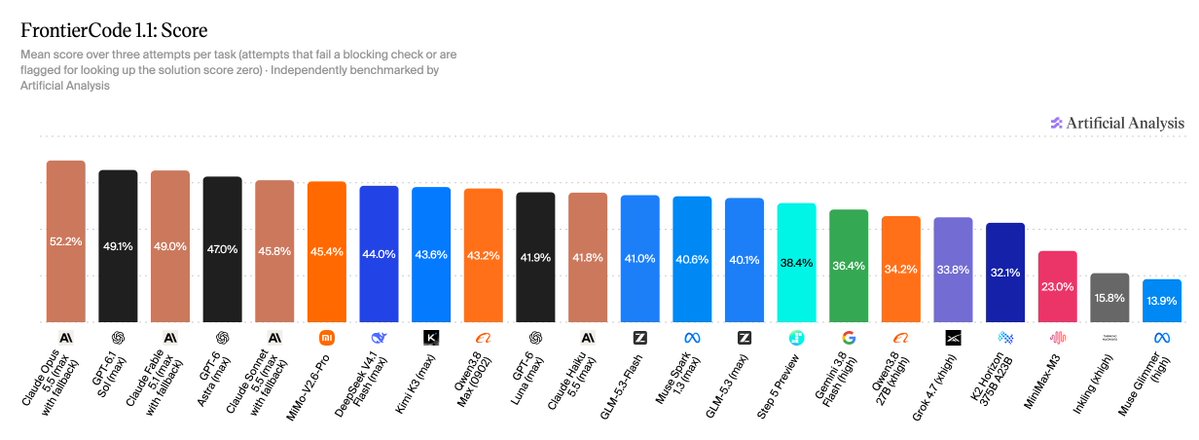
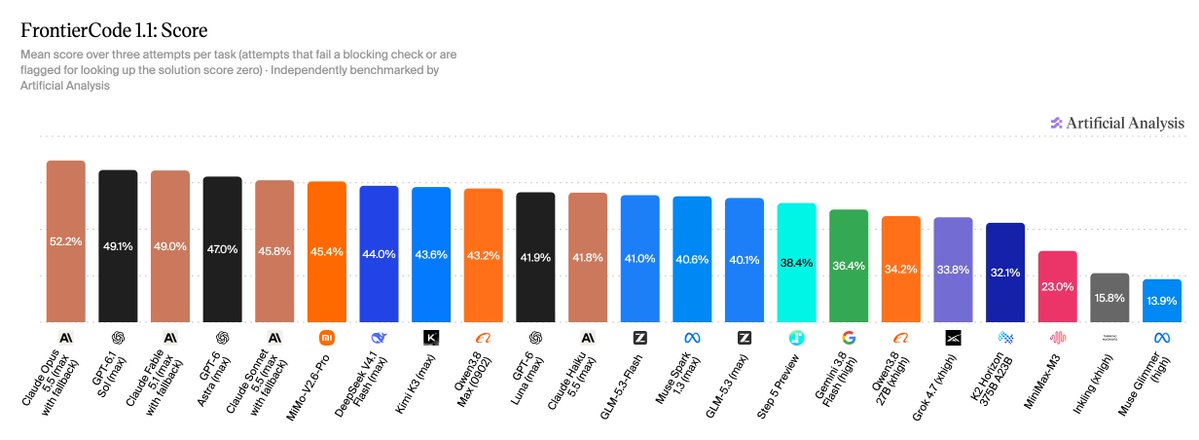
Passing tests is only part of producing a change that someone can maintain. Artificial Analysis' FrontierCode evaluation runs Cognition's , whose tasks were built with repository maintainers, and checks scope, unnecessary changes and other review criteria alongside functional behavior.
Its average score and pass rate mean different things: failing a blocking check yields zero, while successful attempts can still lose credit for desirable qualities. The combines programmatic checks with an applying maintainer criteria; it does not mean a maintainer personally accepted every generated patch. That makes the benchmark useful for examining the cleanup burden hidden by a simple tests-pass result, under its particular and grading rules.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- LLM-as-judge — Using one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.




Checking sign-in…
Loading comments…