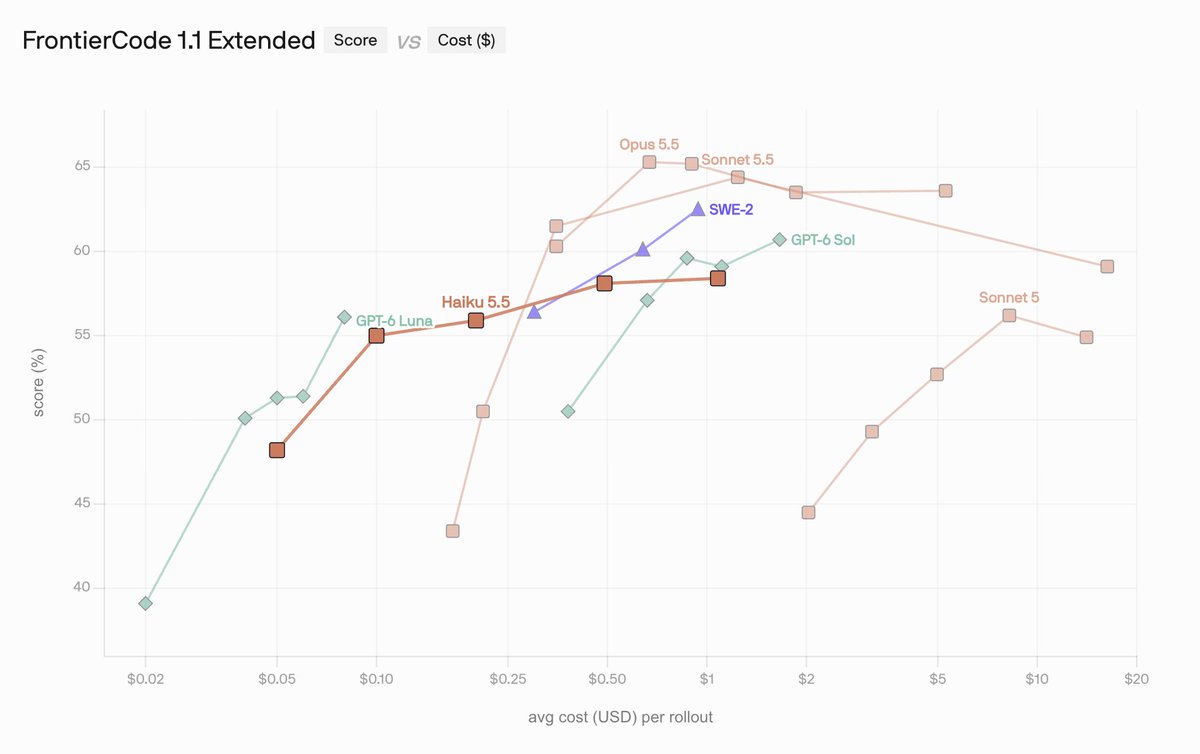
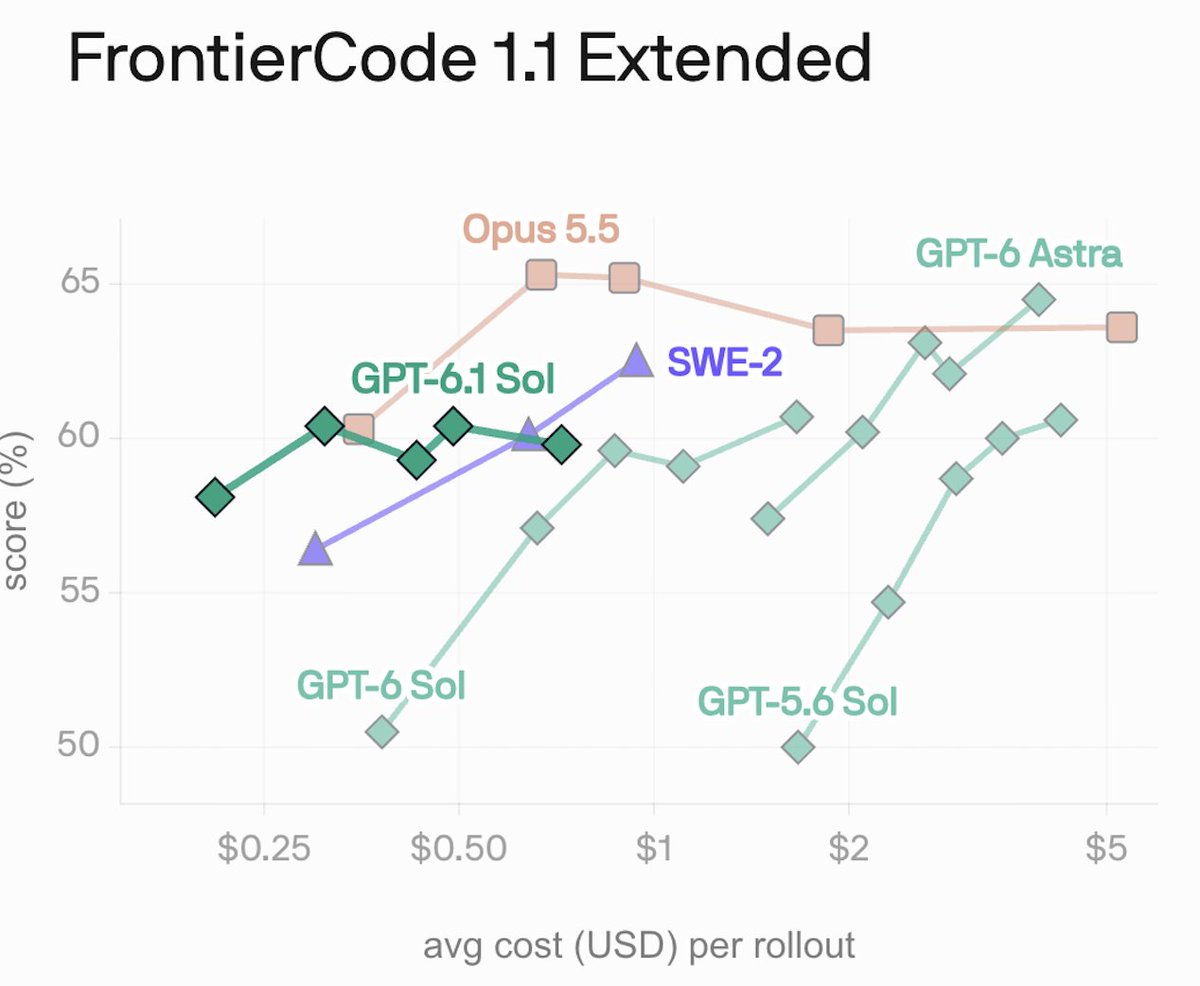
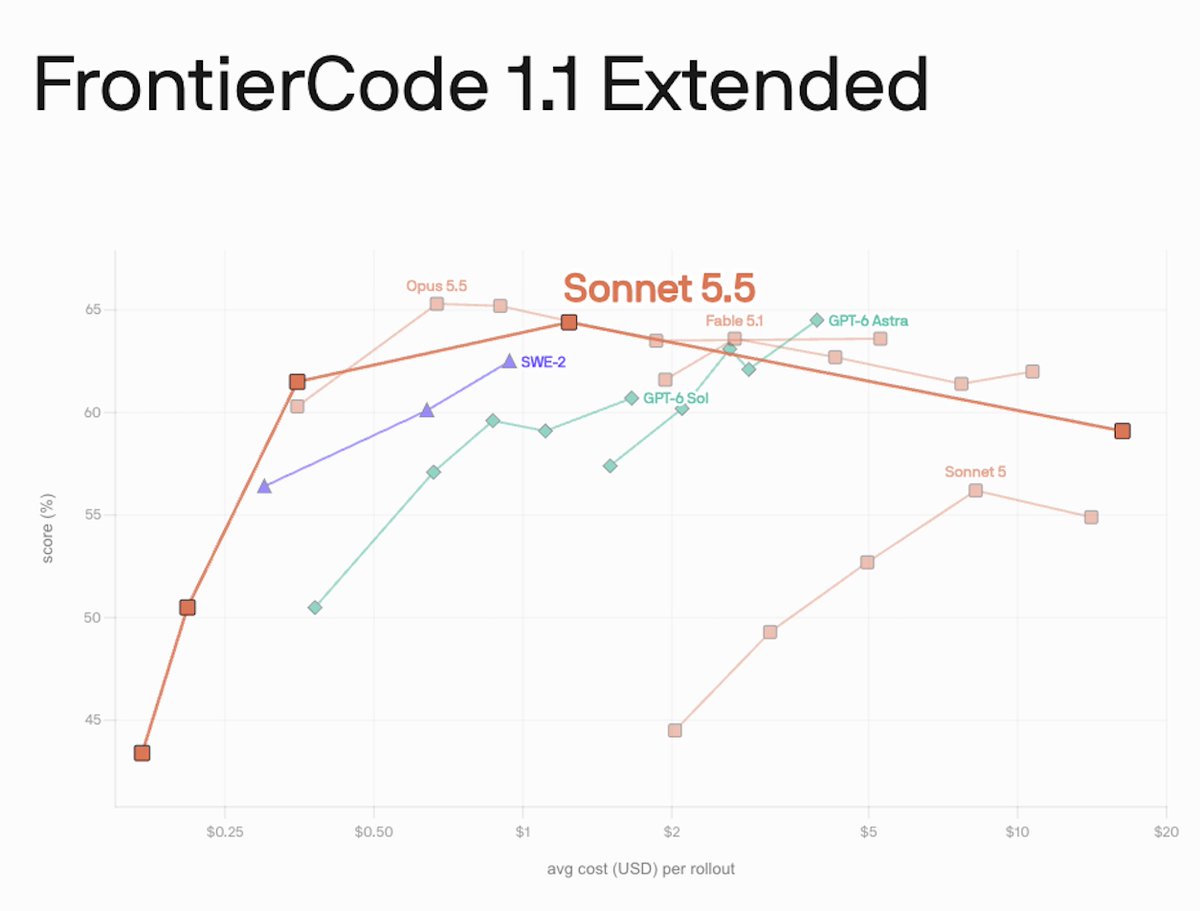
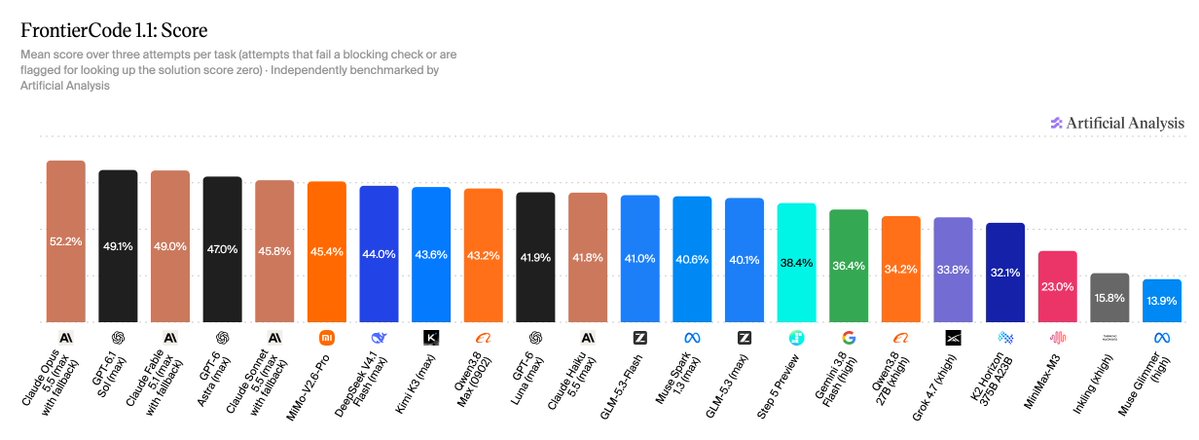
FrontierCode 1.1 is now on @ArtificialAnlys!
Built with open-source maintainers, FrontierCode is the first benchmark to measure end-to-end code quality and mergeability: would the maintainer actually merge this PR? https://t.co/HUayr2T1A2
It measures whether a PR a maintainer would actually merge, not just whether tests pass, and independent leaderboard hosting makes model comparisons on code quality easier to trust.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.