Meta previews WildArtifactBench, scoring agents by preference Elo
- Source
- x.com
- Date

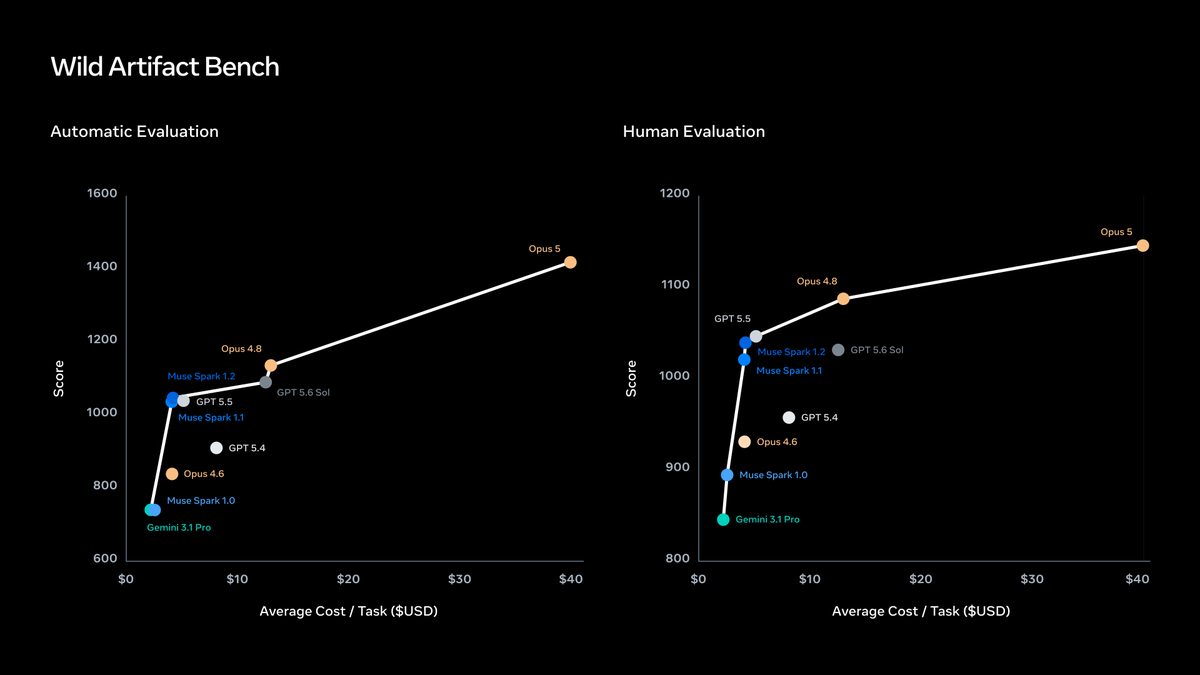
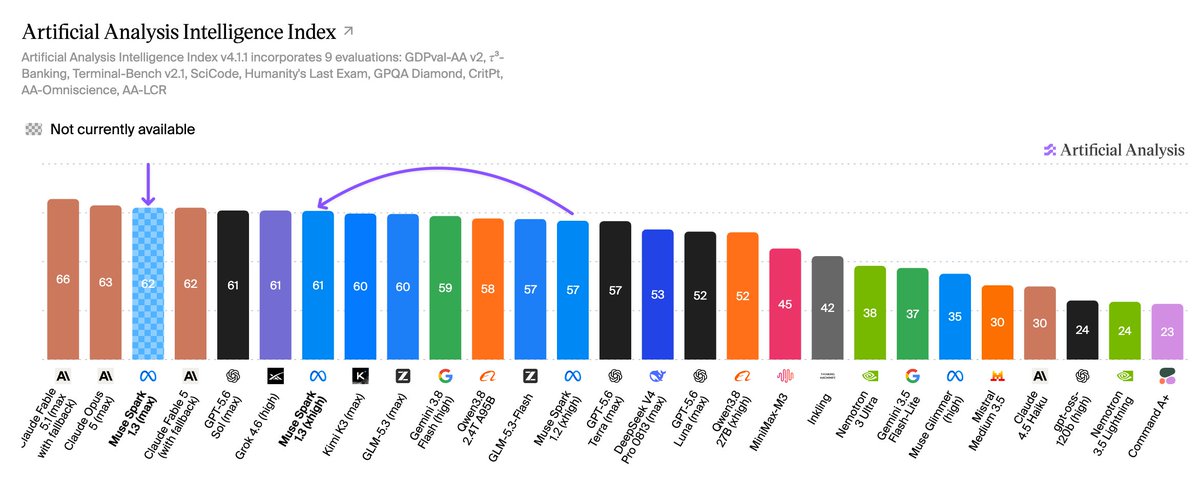
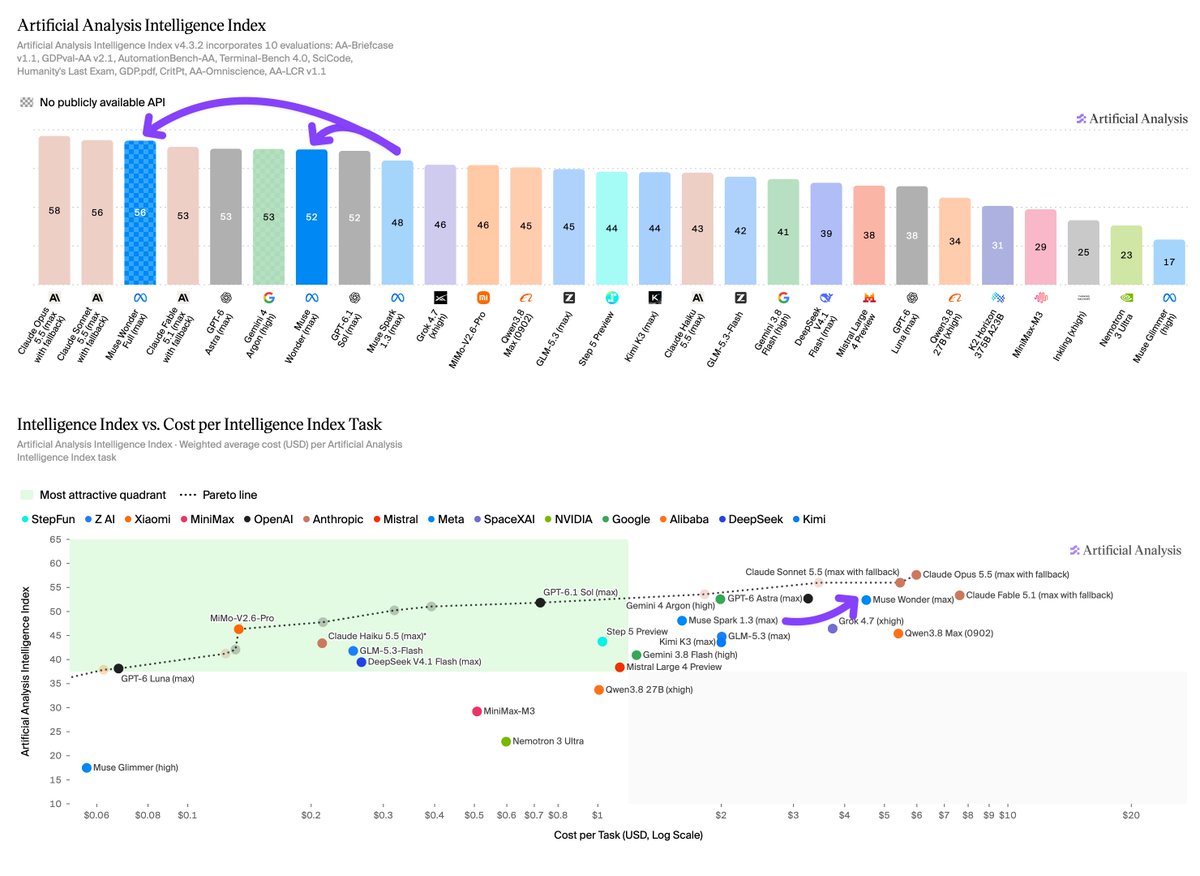
Today we’re also previewing WildArtifactBench, an internal evaluation framework designed to assess agents on complex, real-world tasks across diverse deliverable formats. By using win rates and Elo scores from human and agentic preference judges rather than strict ground-truth rubrics, it expands task coverage across practical multimodal workflows. We’re releasing 10 tasks from WildArtifactBench as a step forward in our ability to measure the real practical utility delivered by multimodal agents:
Context
WildArtifactBench, which Meta describes as an internal framework, is built for work that has no single correct answer. Instead of grading each output against a fixed answer key or a strict rubric, it has human and AI-agent judges compare deliverables and say which they prefer. Those preferences are summarized as win rates and Elo scores. Elo is the rating system from chess: each head-to-head comparison raises the winner's rating and lowers the loser's, so after many comparisons the ratings put entries in order. According to Meta's post, the point of this design is coverage: dropping the answer key broadens the range of practical workflows the can include.
So far the release is a preview. Meta published ten tasks rather than the full benchmark. The preview page lists them by name and category: bird-sound audio analysis, cardiac ultrasound, coronary angiography video analysis, a DQN driving task filed under machine learning engineering, materials metrology from images, 3D modeling of a microchip, video editing, and digital design tasks such as a kitchen layout and a cat mesh. The page's task viewer lists instruction, data and rubric files for each task, but neither the post nor the preview page, as read here, gives any scores, says which agents were compared, or explains how human and agent judgments are combined. Readers can see the kinds of tasks involved but not how any system performs on them. The post's "also" points to a companion announcement, likely Meta's Muse Spark 1.2 evaluation thread, but it doesn't say whether WildArtifactBench was used on that model.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.

Checking sign-in…
Loading comments…