Harvey Lab Aa V1 1
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
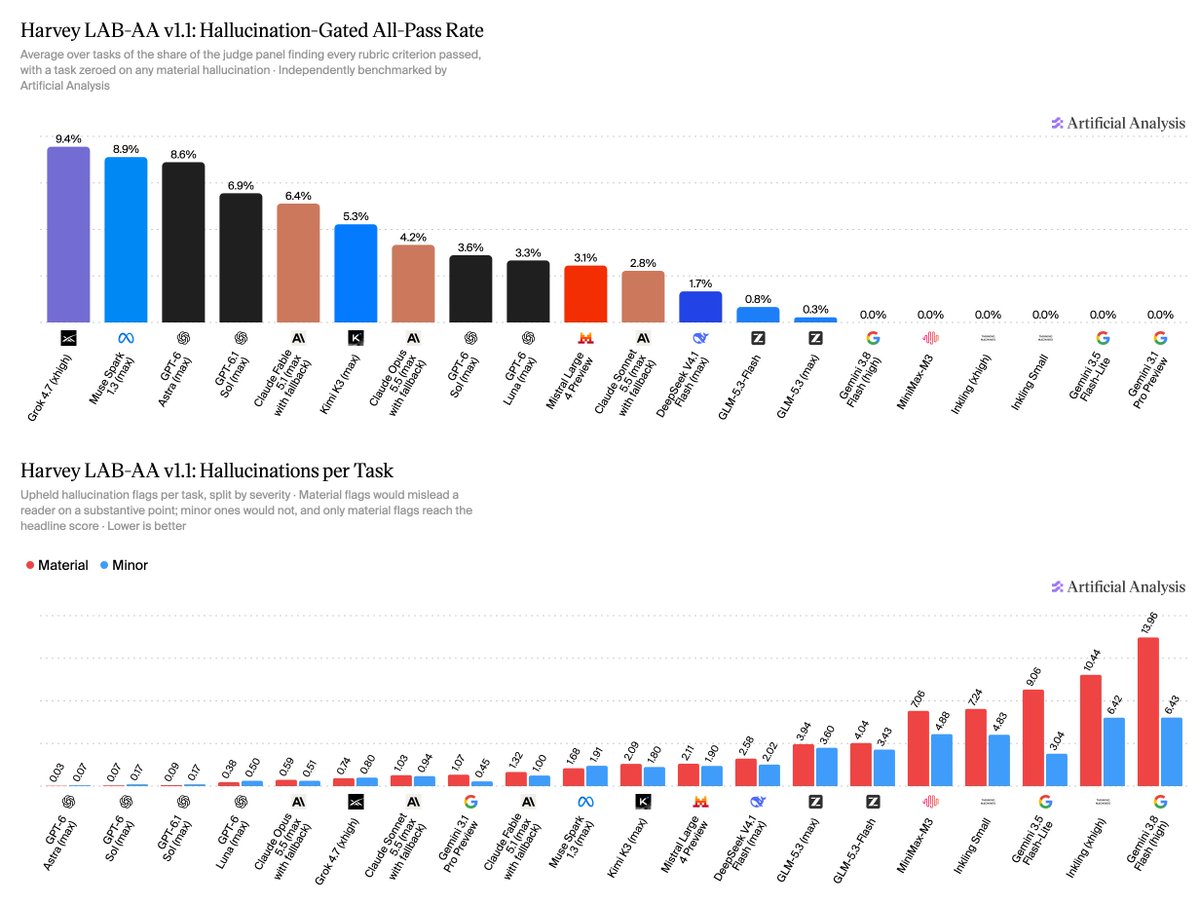
An answer can cover nearly every requested section and still contain a consequential invention. Artificial Analysis' Harvey LAB-AA v1.1 update separates rubric coverage from in the supplied documents. A material unsupported claim makes the task's headline score zero even when its other requirements pass.
That distinction changes the ranking because completeness and factual grounding are different strengths. The check concerns task-specific claims, while general legal knowledge is outside its audit; AI judges still perform the grading. The result is a more explicit test of whether a deliverable is supported by its record, not a certification of legal correctness or readiness for unsupervised use. Scores from the previous grading version are not directly comparable.
- grounding — Tying a model's answers to checkable sources — retrieved documents, live data, tool results — instead of letting it answer from memory alone.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.




Checking sign-in…
Loading comments…