Can AI tell if you've built your IKEA furniture wrong?
- Source
- x.com
- Date
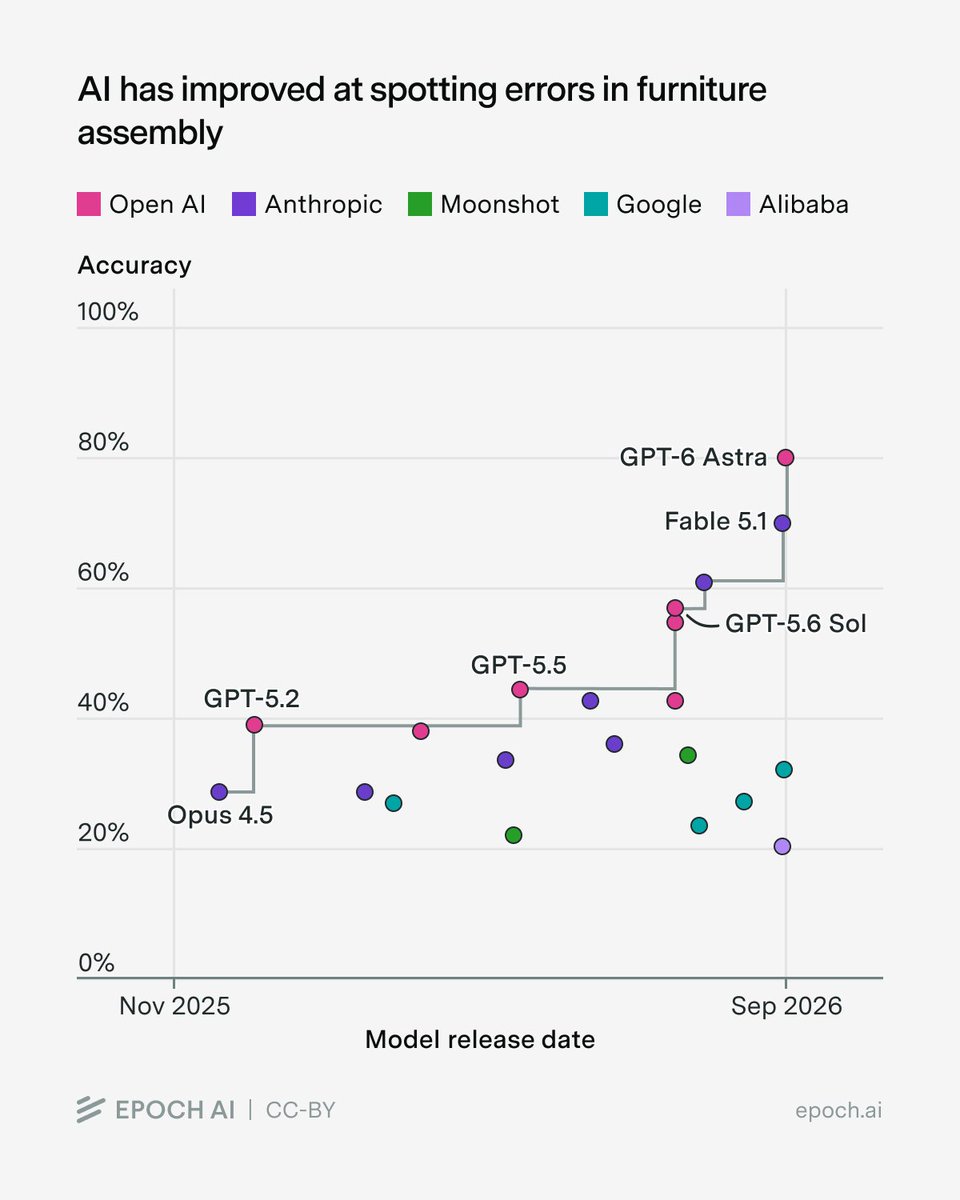
Epoch AI released the Furniture Assembly Benchmark, or FAB, which gives a model the assembly manual and a photo of a partly built piece of furniture and asks it to spot the error. The set is small, 60 photos across three builds, but the trend is steep: the best score went from 28% to 80% in ten months. Epoch notes two ways to fail, missing a real mistake or flagging a correct build, and says frontier models tend to lean one way. Gemini 3.1 Pro passes almost no correct builds, while GPT-5.4 catches almost no mistakes. GPT-6 Astra was both the most accurate and the fastest model tested. Epoch argues the task stands in for economically useful visual reasoning such as car or appliance repair, so the split in failure modes is worth checking before trusting any model as an inspector.

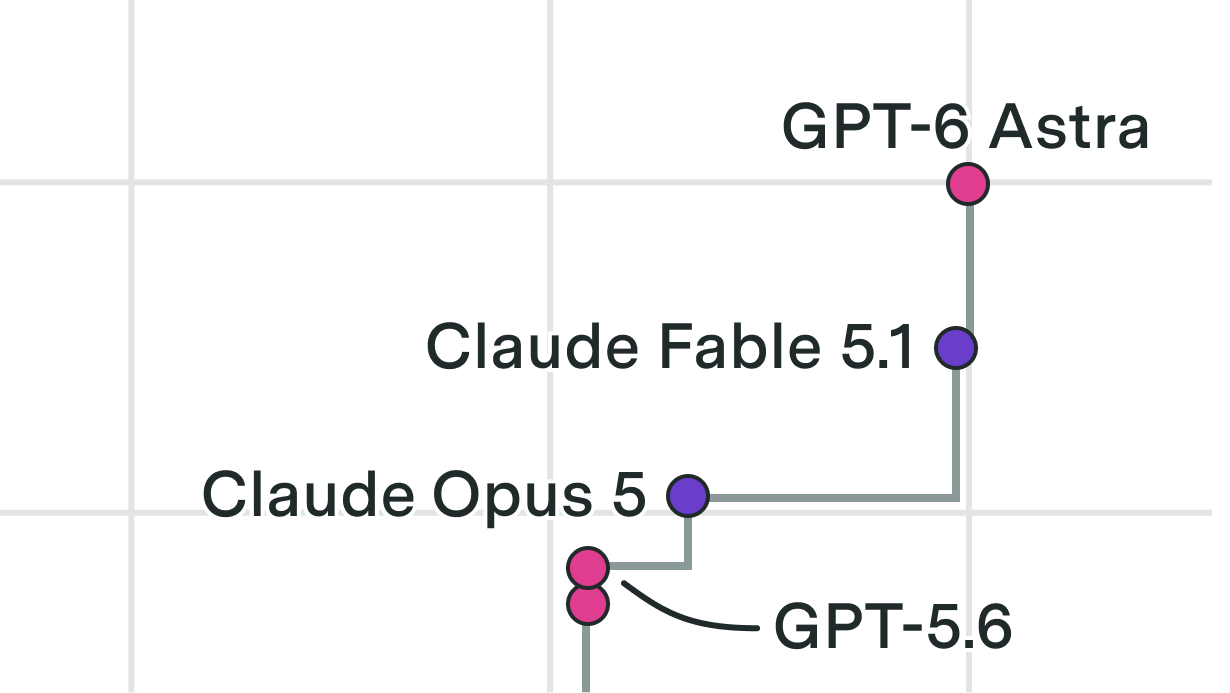
Can AI tell if you've built your IKEA furniture wrong? Our new benchmark, the Furniture Assembly Benchmark (FAB), gives models the manual and a photo of a half-completed piece of furniture and asks them to spot the mistake. The top score has gone from 28% to 80% in just 10 months.
On FAB, AI must assess builds based on photos like the one shown below. The benchmark consists of 60 photos from 3 different furniture builds.

There are two ways to get a question wrong: miss a real mistake, or flag a build that's fine. Many recent frontier models favor one failure mode over another. Gemini 3.1 Pro, for example, passes almost no correct builds, whereas GPT-5.4 catches almost no mistakes.

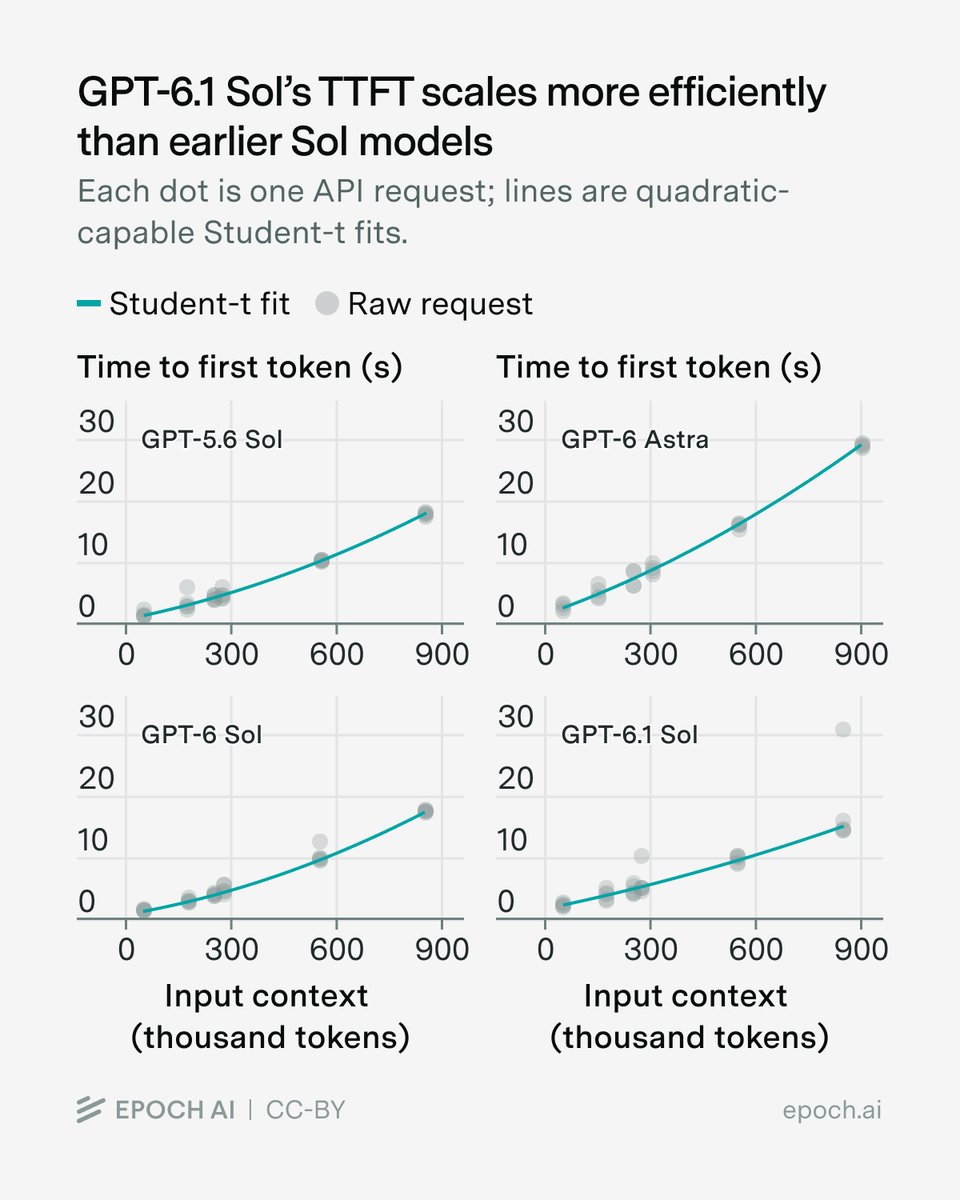
For practical utility, speed matters as well as accuracy. Here GPT-6 Astra is a clear outlier. Not only is it the most accurate, but, of all the models we tested, it is also the fastest.

Context
Epoch AI built a that hands a model an IKEA-style manual and a photo of a half-finished furniture build, then asks it to spot whether something was assembled wrong. On this Furniture Assembly Benchmark, the top reported score rose from 28% to 80% over ten months, a fast jump for a task Epoch frames as a stand-in for visual troubleshooting jobs like diagnosing a car problem or a broken appliance from a photo.
That headline number hides a split in how current models fail. There are two ways to get a question wrong: miss a real mistake, or wrongly flag a build that is actually fine. Epoch reports that Gemini 3.1 Pro almost never passes a correct build, meaning it over-flags, while GPT-5.4 catches almost no real mistakes, meaning it under-flags. Among the models tested, GPT-6 Astra came out both the most accurate and the fastest, which matters for a benchmark meant to model real-time troubleshooting rather than an untimed quiz.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…