AA-PersonalityBench: recent Grok releases get less sycophantic and sloppy
- Source
- x.com
- Date

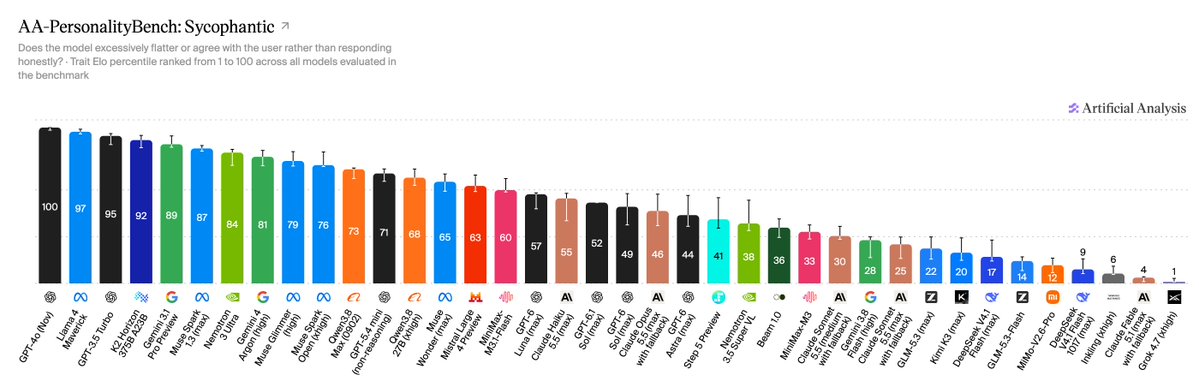
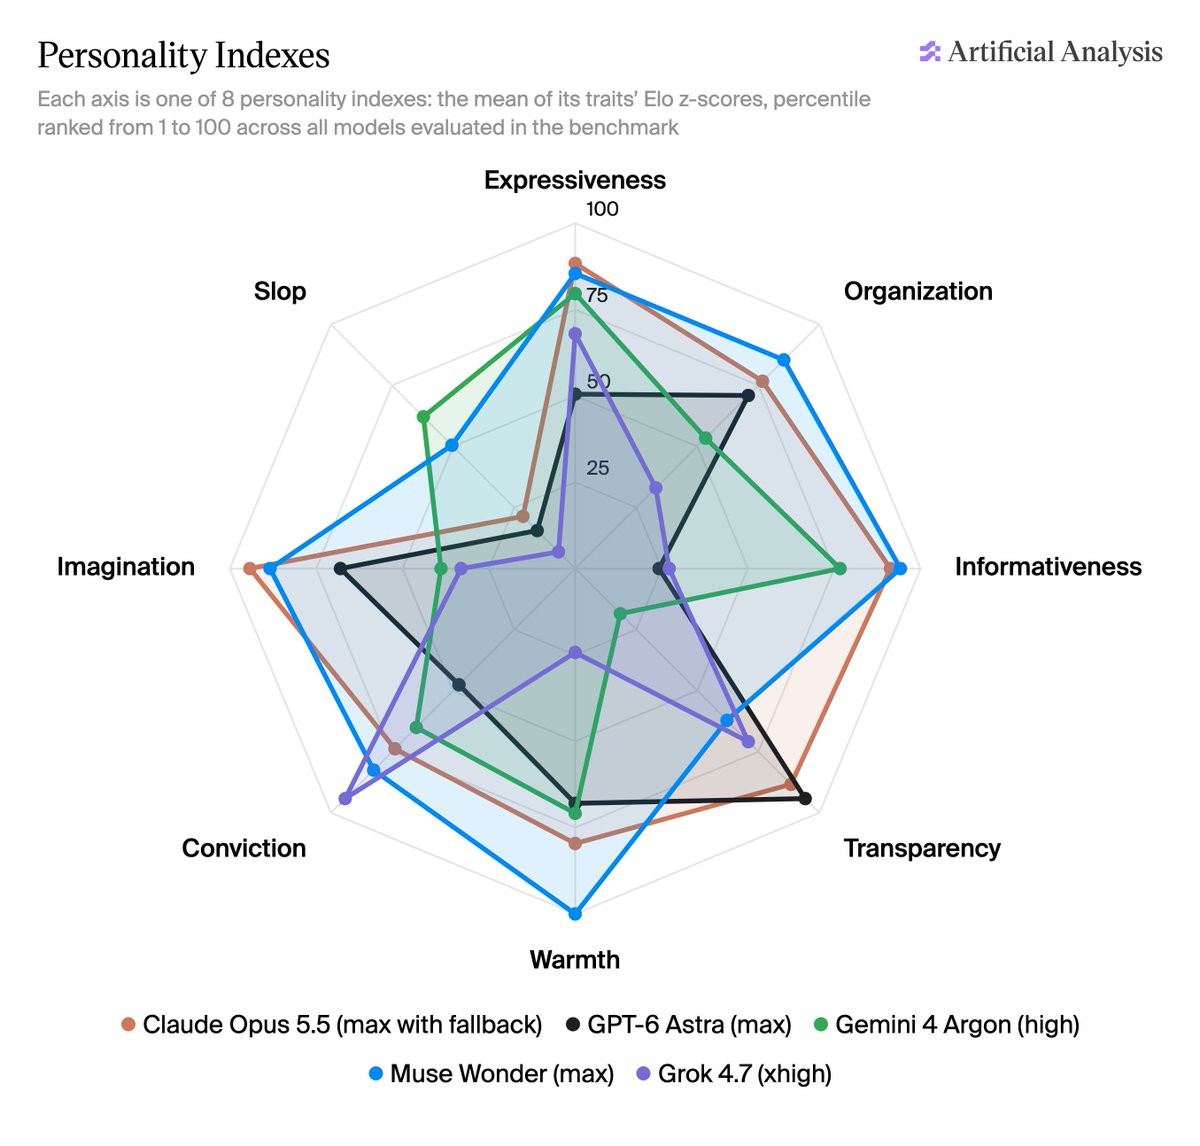
In AA-PersonalityBench, each recent Grok release from has become less sycophantic, more sincere, and produces less slop The Slop trait assesses how much generic filler or AI-flavored padding models use; Sycophantic measures whether models excessively flatter or agree with the user rather than responding honestly; Sincere measures a model’s tonal authenticity, as opposed to forced enthusiasm or templated responses. Across the last three Grok releases from @elonmusk’s @spacexai, Slop fell 62 percentile points, Sycophantic fell 17, and Sincere rose 64: ➤ Slop: Grok 4.5 (68), Grok 4.6 (38) and Grok 4.7 (6) ➤ Sycophantic: Grok 4.5 (18), Grok 4.6 (3) and Grok 4.7 (1) ➤ Sincere: Grok 4.5 (26), Grok 4.6 (63) and Grok 4.7 (90)

Context
By Artificial Analysis's measure, Grok has steadily lost its chatbot mannerisms. On AA-PersonalityBench, a the firm uses to score models' personality and style, across the last three Grok releases from xAI, from Grok 4.5 to Grok 4.7, each new version used less generic padding, flattered the user less and sounded more sincere than the one before. The post reports the results as percentile scores for three traits.
Each trait targets a familiar complaint about AI writing. Slop measures how much generic filler or AI-flavored padding a model produces. Sycophantic measures whether it excessively flatters or agrees with the user instead of answering honestly. Sincere measures tonal authenticity, as opposed to forced enthusiasm or templated replies. On Slop, Grok 4.5 scored 68, Grok 4.6 scored 38 and Grok 4.7 scored 6, a fall of 62 percentile points. On Sycophantic, the scores went from 18 to 3 to 1. On Sincere, they rose from 26 to 63 to 90.
The trend is consistent: every trait moved in the same direction at every release, and Grok 4.7 sits close to the bottom of the scale on both negative traits. These numbers describe tone, though. A model can avoid flattering the user and still be wrong, and nothing in the post speaks to accuracy. The post also does not explain how the traits are scored or which set of models the percentiles are ranked against, so the results are best read as one evaluator's consistent measure of style rather than an independently checked finding.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.




Checking sign-in…
Loading comments…