HLE-Diamond leaderboard: reasoning outpaces knowledge, effort costs add up
- Source
- x.com
- Date

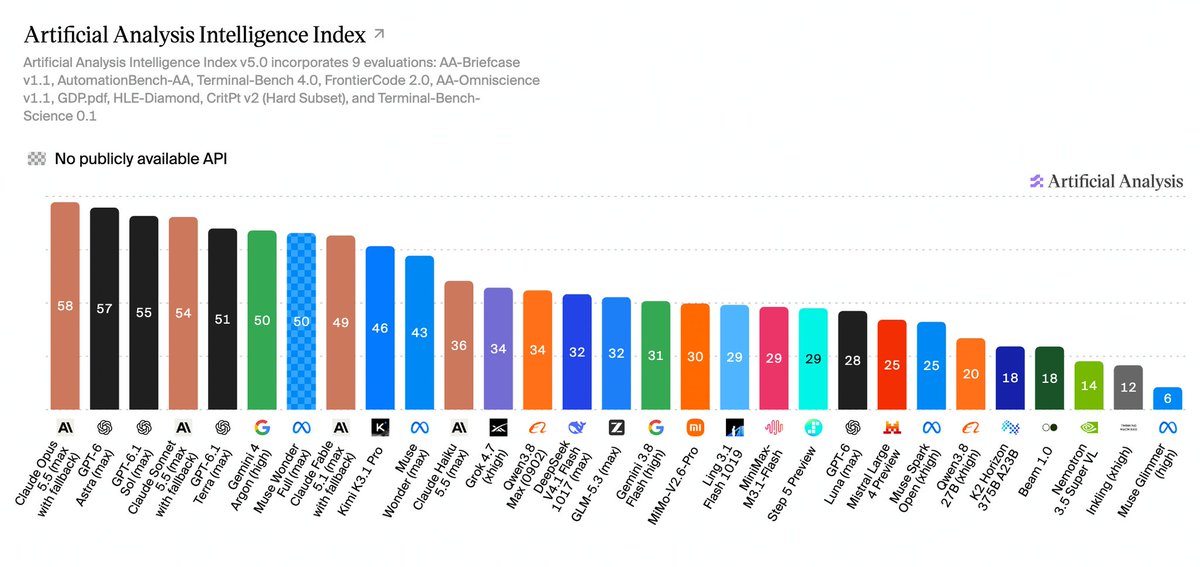
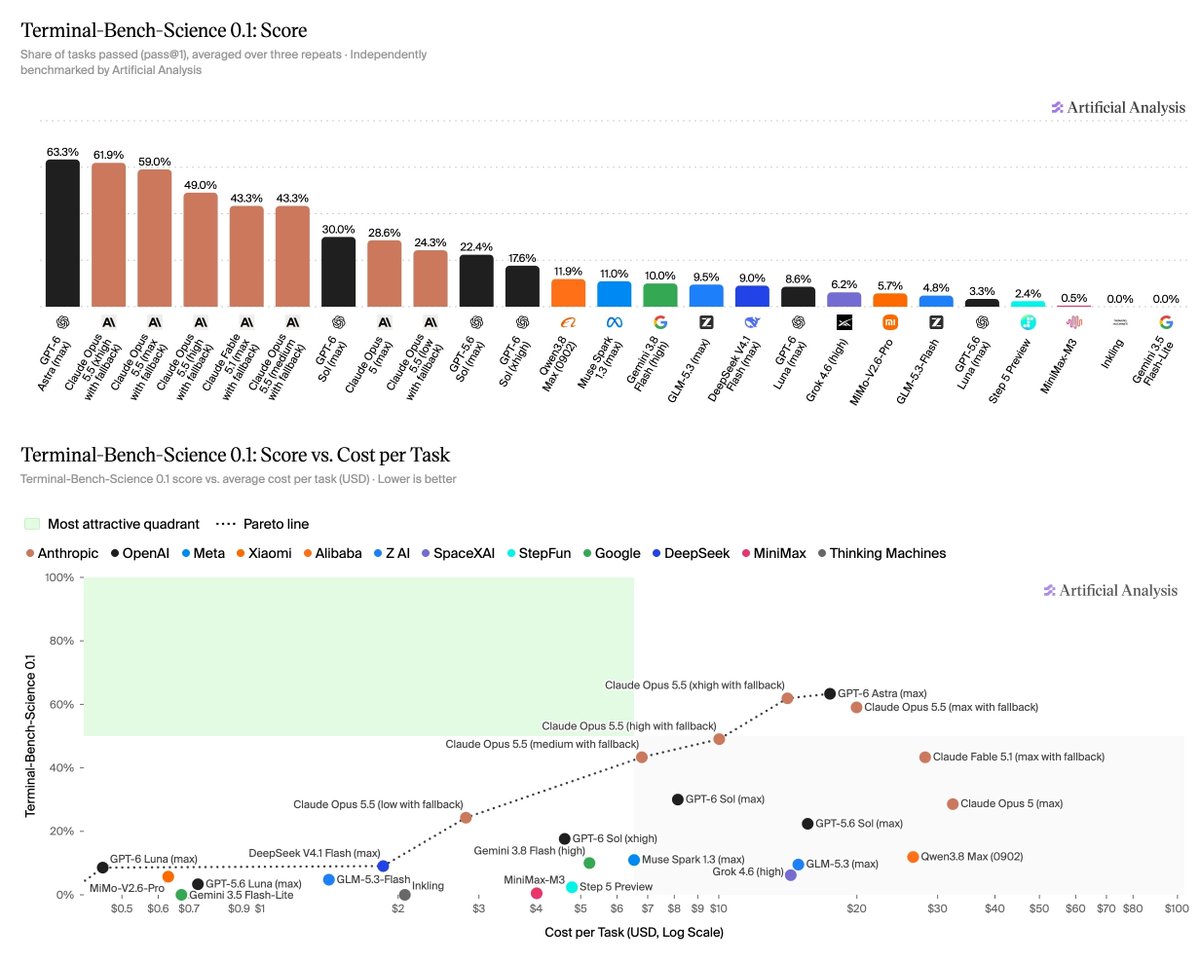
We've launched our HLE-Diamond leaderboard, our independent evaluation of the refined 1,000-question version of Humanity's Last Exam, as part of v5 of the Artificial Analysis Intelligence Index HLE-Diamond was released by @CAIS and @scale_AI after a year of cleaning and refining the original Humanity's Last Exam dataset with input from the research community. It has 1,000 closed-ended questions, split evenly between reasoning and knowledge, and 272 of them include an image. We run every question once without tools, using the official HLE system prompt. GPT-5.6 Luna (medium) grades each answer against the reference answer with the official HLE judge prompt, and we report the share of questions judged correct (pass@1). Key takeaways: ➤ Only 17 model variants (~13%) score above 50% today: Gemini 4 Carbon (high) leads at 69%, followed by Claude Opus 5.5 (max) at 68% ➤ Models score higher on reasoning than on knowledge: Over 90% of the models we measured do better on the reasoning portion of the benchmark. Gemini 4 Carbon (high) leads both, at 80% on reasoning and 59% on knowledge. Claude Opus 5.5 (max) and GPT-6 Astra (max) both score 78% on reasoning, and Opus 5.5 is ahead on…

Context
HLE-Diamond is a cleaned-up version of Humanity's Last Exam, a of closed-ended questions, and Artificial Analysis now runs it as part of its Intelligence Index v5, where it carries 10% of the weight. According to the Artificial Analysis thread, the Center for AI Safety and Scale AI released it after a year of refining the original dataset with input from researchers. It has 1,000 questions, half testing reasoning and half testing knowledge, and 272 of them include an image.
The scoring method shapes what the numbers mean. Artificial Analysis asks each question once, with no tools, using the official HLE . A separate model, GPT-5.6 Luna at medium effort, compares each answer with the reference answer using the official HLE judge prompt, and the score is the share judged correct on that single attempt. A model therefore gets no retries and cannot look anything up, so the knowledge half tests what the model already holds.
Under those conditions, only 17 model variants, about 13% of those tested, score above 50%. Gemini 4 Carbon at high effort leads with 69%, one point ahead of Claude Opus 5.5 at max effort, which led this benchmark when Index v5 launched a few days earlier. More than 90% of the models measured do better on reasoning than on knowledge. Claude Opus 5.5 and GPT-6 Astra both score 78% on reasoning, but Opus 5.5 scores 58% on knowledge against GPT-6 Astra's 50%. Gemini 4 Carbon leads both halves, with 80% on reasoning and 59% on knowledge.
Open-weights models are far behind. The best is Kimi K3.1 Pro at 37%, and its weights have not been released yet. MiniMax-M3.1-Flash follows at 28% and Kimi K3 at 27%. The Index v5 announcement found the same pattern: HLE-Diamond is one of the two benchmarks where the gap between open-weights and proprietary models is widest.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- system prompt — The standing instructions a model receives before any user input — defining its role, rules, tools, and tone for the whole conversation.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.




Checking sign-in…
Loading comments…