Reflection Beam
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
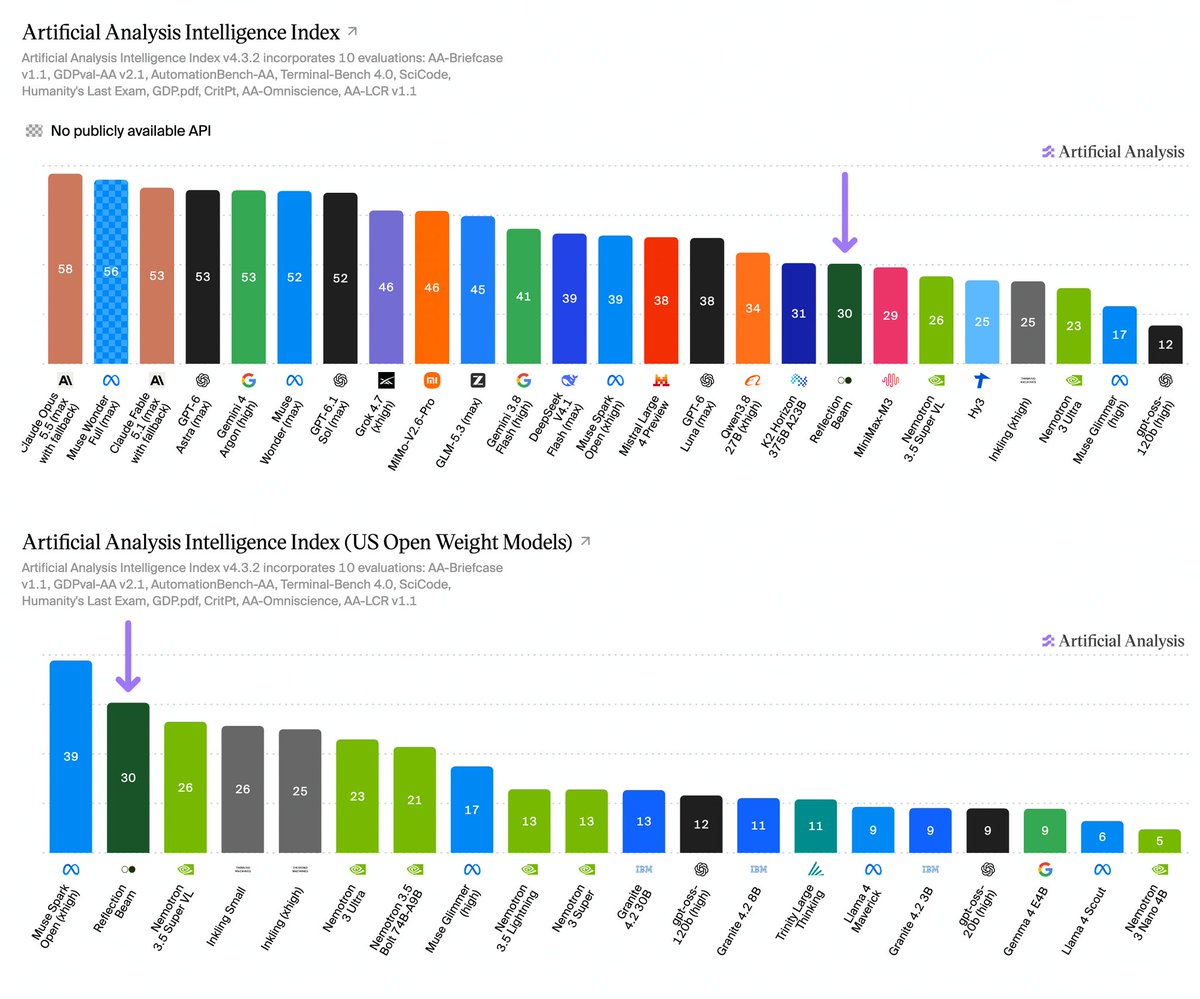
When we covered Beam on Oct. 6 it was an announcement with weights promised for later in the month. The weights are now out under Apache 2.0, and Hugging Face lists BF16, FP8 and NVFP4 checkpoints with day-zero transformers, vLLM and SGLang support plus SFT and RL recipes. Artificial Analysis has also run its full suite. Beam scores 30 on the Intelligence Index, behind Meta's Muse Spark Open at 39 and ahead of NVIDIA's Nemotron 3.5 Super VL at 26, which makes it second among US open-weight models and tenth among all open models. It spends about 26k output tokens per task, half of what K2 Horizon uses one point higher. The profile is uneven. Beam scores 48.5% on AutomationBench-AA, 11 points ahead of K2 Horizon, and 34% on the Cyber Index, the best US open-weight result Artificial Analysis has measured. It scores 3.0% on Terminal-Bench 4.0 and 28 on the Coding Agent Index in Reflection's Mirror harness, 40 points behind the leaders. It answers 33% of knowledge questions correctly but hallucinates at 47%. Vercel's AI Gateway serves it free during launch, with a standard slug that moves to paid pricing when the offer ends.
Context
Beam is the first model from Reflection, and this October 16, 2026 article is the benchmarking firm Artificial Analysis reporting how it scored in its own testing (artificialanalysis.ai). The headline number is 30 on the Artificial Analysis Intelligence Index, a composite of ten evaluations. That places Beam second among US open-weights models (models whose weights anyone can download and run), behind Meta's Muse Spark Open at 39 and ahead of NVIDIA's Nemotron 3.5 Super VL at 26, released the day before. Among all open-weights models it ranks tenth, one point behind the UAE's K2 Horizon. Proprietary models remain well ahead: GPT-6 Astra (max) scores 53.
The single score hides an uneven profile, and that is the useful reading of the article. Beam is economical: it spends about 26k output tokens per index task (roughly 19k on reasoning and 7k on the answer), while K2 Horizon, one point higher, uses about twice that. It does well on workflow automation, scoring 48.5% on AutomationBench-AA against 37.2% for K2 Horizon and level with Qwen3.8 27B, and on CritPt, where its 13.1% more than doubles both of those peers. It completes 34% of tasks on the firm's Cyber Index, the best result among US open-weights models Artificial Analysis has tested. Its weak spots are working in a terminal, where it scores 3.0% on Terminal-Bench 4.0, and agentic coding: run in Mirror, Reflection's open-source command-line , it scores 28 on the Coding Agent Index, 15 points behind the next setup and 40 behind the leaders.
The knowledge results cut both ways. On AA-Omniscience Beam answers 33% of questions correctly, far above K2 Horizon (18%) and Qwen3.8 27B (16%), but its rate is 47%, against 26% and 30% for those two. The benchmark's net score still puts Beam ahead of both, at 1.5 versus −3.0 and −10.0, so it knows more but also guesses wrong more often.
Beam is described as having 501B total parameters with 23B active, meaning only a fraction of the model is used for each token, plus a 1M-token and text-only input. Hugging Face's launch post, written by its staff after working with the Reflection team on inference and fine-tuning support, presents the same model as an Apache 2.0 release that teams can run on their own hardware and change (Welcome Beam); this article is the outside measurement of how that model performs.
- Per Artificial Analysis, Reflection's Beam scores 30, second among US models behind Meta's Muse Spark Open (39). Outside China, only Muse Spark Open and the UAE's K2 Horizon (31) score higher. It activates 23B of its 501B parameters.
- Beam uses about 26k output tokens per Intelligence Index task, half of K2 Horizon's ~52k for one point less. GPT-6 Astra (max) scores 53 on a similar ~27k budget, so proprietary models still lead at equal token spend.
- Beam scores 48.5% on AutomationBench-AA, 11 points ahead of K2 Horizon and level with Qwen3.8 27B, but only 3.0% on Terminal-Bench 4.0, behind Qwen3.8 27B (5.6%) and Muse Spark Open (8.1%).
- On AA-Omniscience Beam answers 33% of questions correctly, versus 18% for K2 Horizon and 16% for Qwen3.8 27B, so despite its 47% hallucination rate its net index of 1.5 beats both peers (-3.0 and -10.0).
- Running in Reflection's open-source Mirror CLI harness, Beam scores 28 on the Coding Agent Index, 15 points behind Claude Code with Qwen3.8 Max (43) and 40 behind the leaders, though only two Codex setups use fewer tokens.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.





Checking sign-in…
Loading comments…