SemiAnalysis on OpenAI's Jalapeno silicon and how much the CUDA moat holds
- Source
- x.com
- Date

Ep. 027 - OpenAI Jalapeño: Better Than Nvidia Blackwell (Accelerators) This week Bryan, Myron and Jordan (@JordanNanos) discuss our recent article on OpenAI Jalapeño. They cover the performance, architecture, programming model, implications for NVIDIA and more. 0:00 Cold Open 1:05 Jalapeno Overview 4:22 Tokens Per Megawatt 9:15 Benchmark Caveats 13:48 The CUDA Moat 21:12 How OpenAI Did It 32:13 Samsung HBM4 42:10 AI-Designed Silicon 49:24 Architecture Deep Dive 56:58 Doom and Wrap

Full Article: https://t.co/dbuAUrSqiz
Context
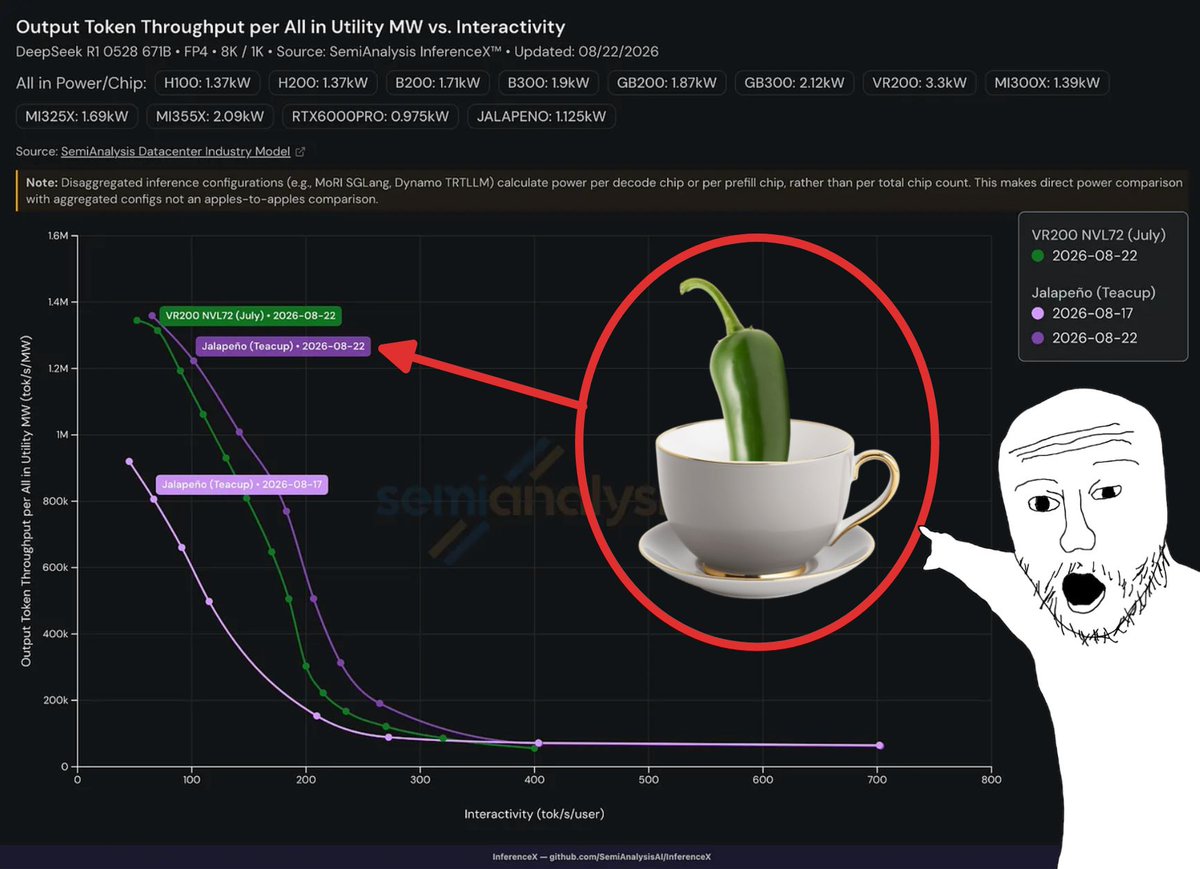
SemiAnalysis reports promising efficiency results for OpenAI's Jalapeño chip, but the test coverage determines what those results establish. In the article behind the episode, the publication says OpenAI supplied the numbers and that it witnessed selected runs in the lab.
The article reports an advantage over NVIDIA's Blackwell in output throughput per unit of power across most tested scenarios. However, it had not seen Jalapeño results on AgentX, which exercises longer, multi-step workloads. The evidence supports an early efficiency result, with performance on those more demanding serving patterns still unresolved.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Checking sign-in…
Loading comments…