Paradigma releases Limite 1B, a small open math model for agent pipelines
- Source
- x.com
- Date

Context
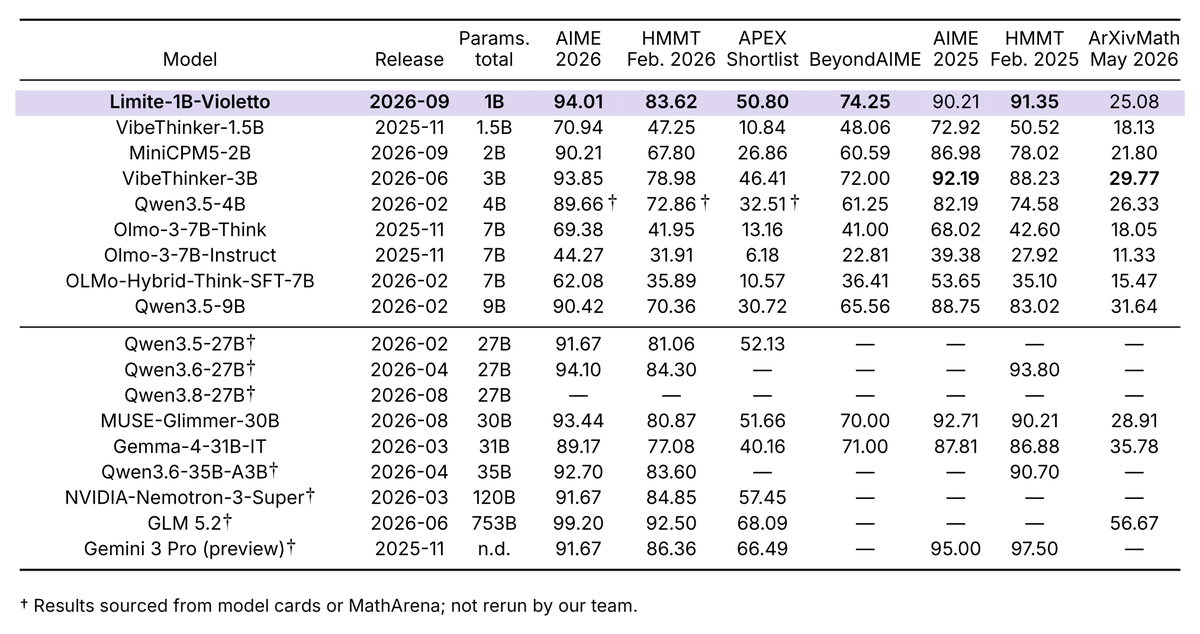
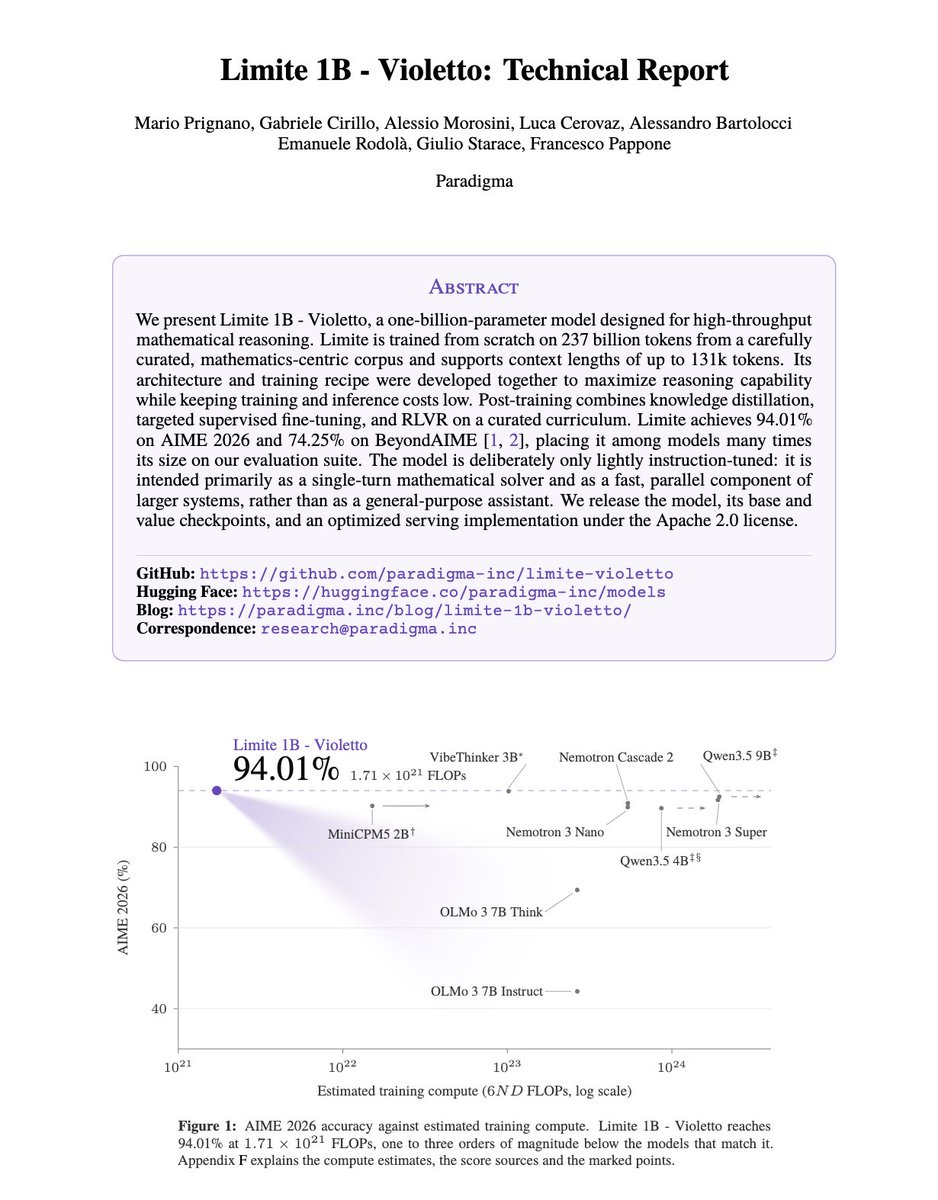
Paradigma's first model, Limite 1B - Violetto, is a small model designed for high-throughput solutions to difficult math problems, answered in single turns. Its announcement calls it a model for high-frequency mathematical intelligence. Paradigma's release post describes a 1-billion-parameter trained from scratch on fewer than 300 billion carefully selected tokens, able to handle sequences up to 131k tokens long. Paradigma credits its sample efficiency to data curation and to an architecture borrowed from speedrun competitions. Four of the release's authors also wrote the fellows' retrospective on speedrun records.
Paradigma says post-training with synthetic data, supervised examples and reinforcement learning gave Limite competition-level math results that rival recent models tens of times larger. Its one example is an average of 74.25% on BeyondAIME, a competition-math test, against 70% for Meta's 30-billion-parameter Muse Glimmer. That is Paradigma's own figure, and the release text read for this explanation does not describe the evaluation setup. The model is deliberately given as little assistant-style instruction tuning as possible, and Paradigma warns that it can lose track of what a prompt asks and treat it as a different, often mathematical, task. It is meant to answer one question at a time, not to hold a conversation.
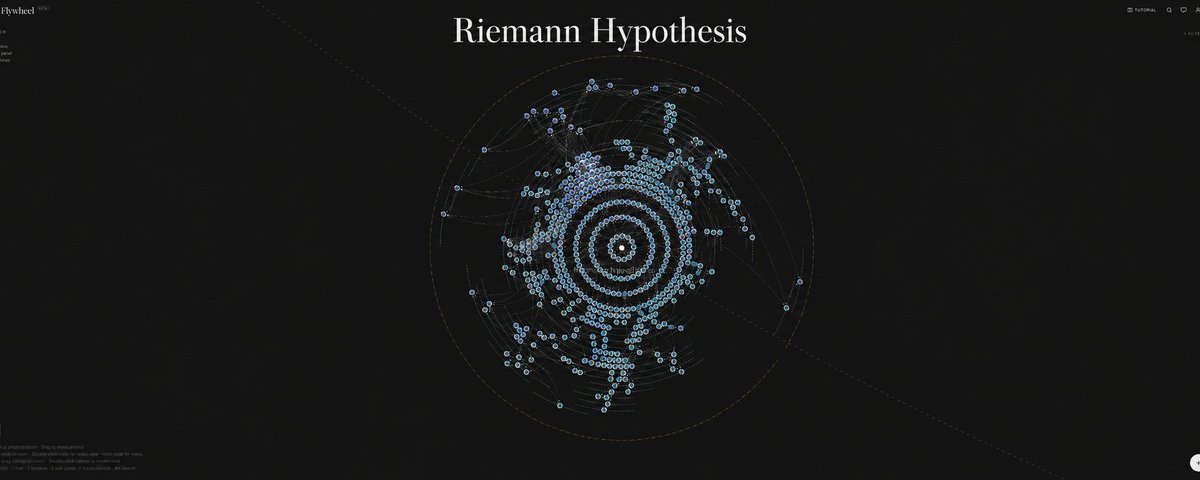
The release gives others what they need to test those claims: the weights under the Apache 2.0 license on Hugging Face, Paradigma's evaluations, a value model used during training and a plugin for serving it efficiently with the vLLM software. A technical report was promised and later announced on October 6, but it was not read for this explanation. Paradigma has already described one use for a fast math model. In its Flywheel proposal four days earlier, an OpenAI Codex session called an internal checkpoint of a math model Paradigma was training as a tool for quick calculations and proof fragments. Paradigma did not say whether that checkpoint became Limite.
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
- pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- multi-agent — Using several AI agents on one problem — splitting work in parallel, checking each other, or filling different roles like planner and reviewer.
Checking sign-in…
Loading comments…