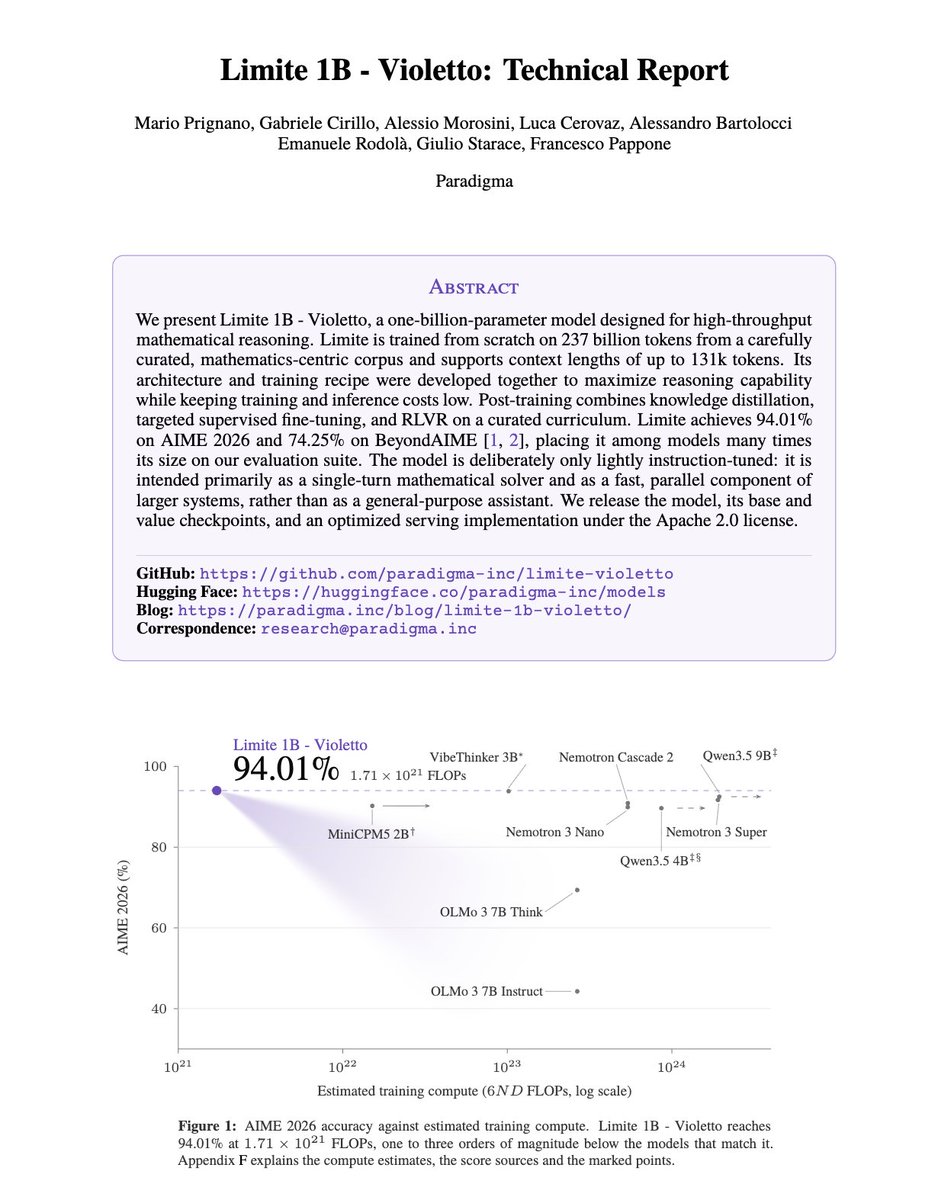
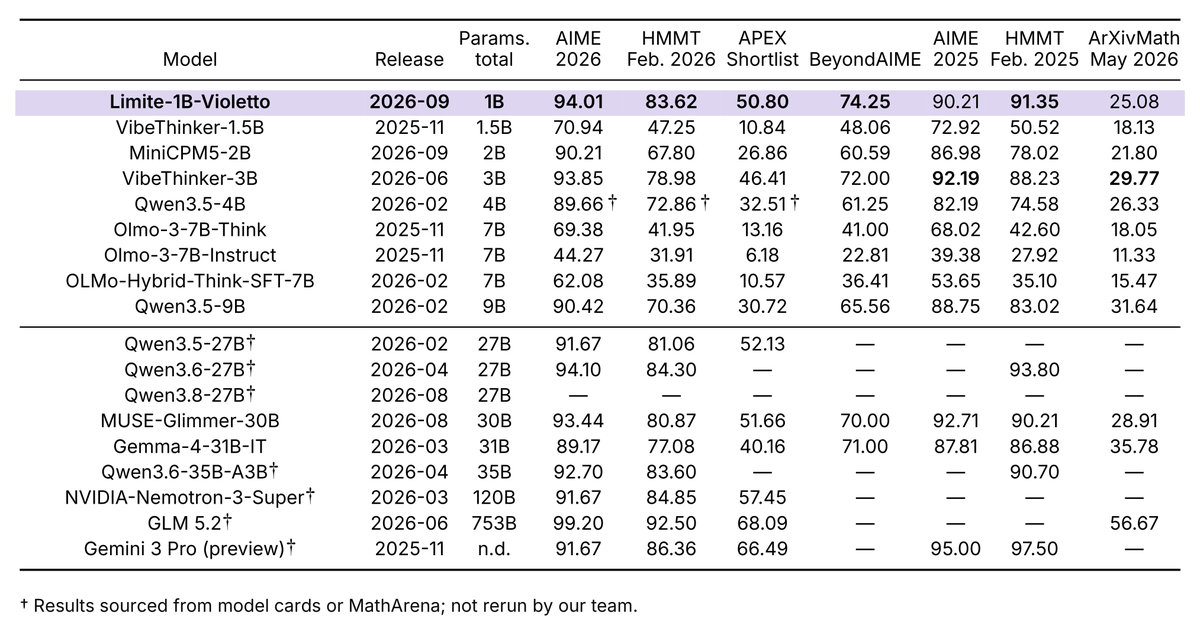
We are releasing the technical report for Limite 1B -Violetto.
Violetto is our first model, designed to push mathematical capabilities per parameter to its limits, trained from scratch.
A 1B model trained from scratch in 6 weeks on under 300B tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → claims competitive math results. The thread names the architecture and RL recipe and releases the evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → suite, so others can check the claims.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.