Vera Rubin NVL72 Agentic Inference: 67x better Performance per Dollar
Source
newsletter.semianalysis.com
Author
Bryan Shan
Date
Context
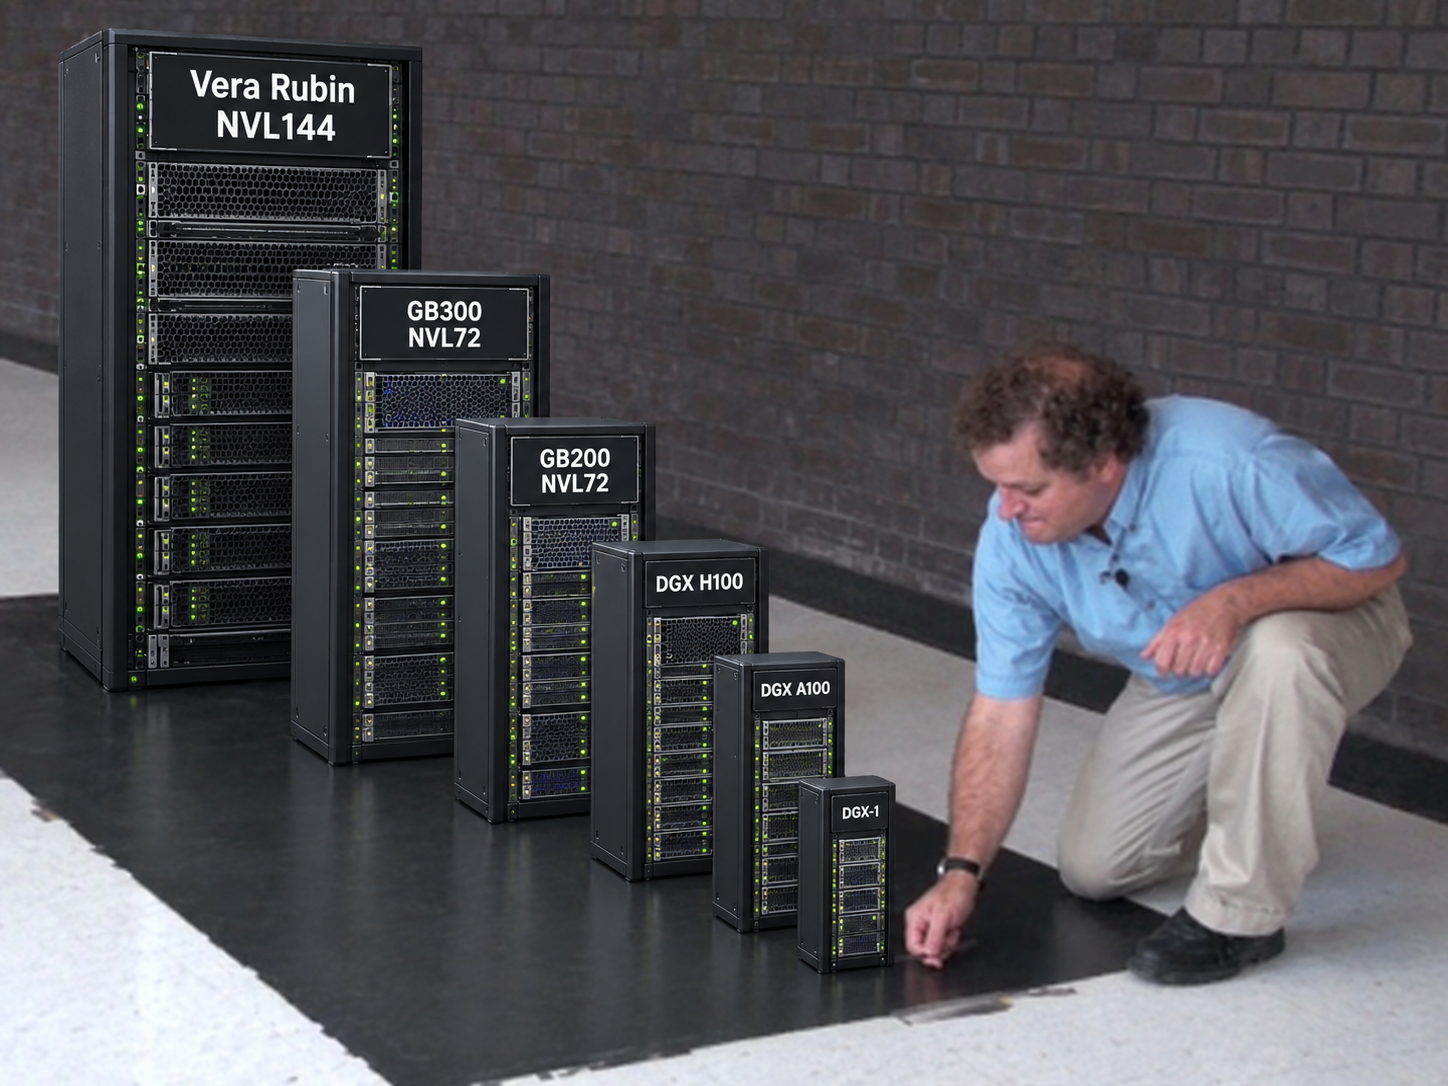
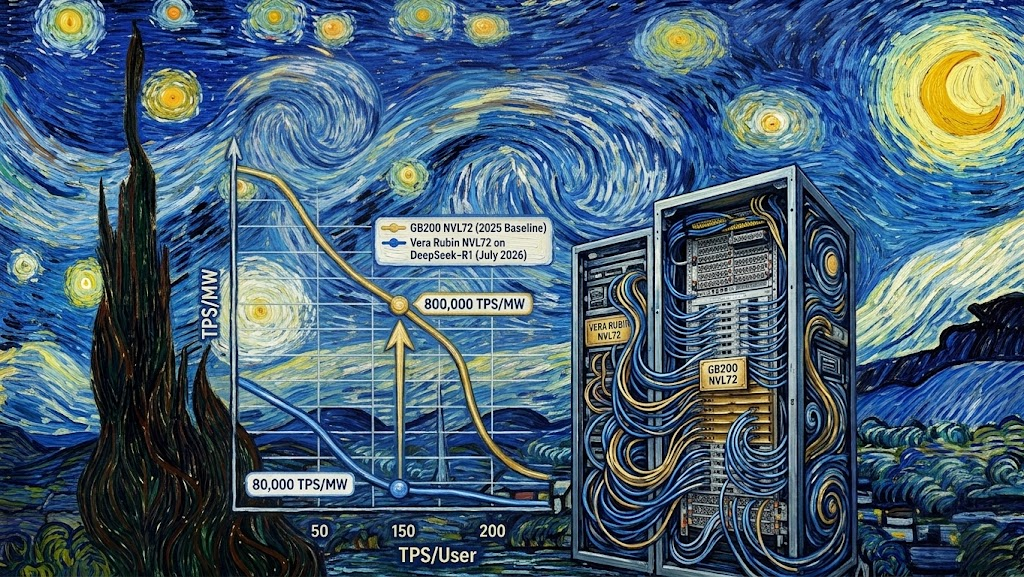
The reported 67-fold efficiency gain for NVIDIA's Vera Rubin describes a particular operating point. SemiAnalysis's benchmark account compares Rubin with GB300 using specified TensorRT-LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → configurations at a response-streamingSending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.Full definition → target of 170 tokens per second, under modeled ownership costs.
At 60–100 tokens per second, the same account reports a smaller 1.4–3-fold advantage in throughput per ownership dollar. The comparison combines measured serving performance with cost assumptions, and its size changes with the required response speed and software configuration. Infrastructure buyers therefore need the operating conditions alongside the headline multiplier.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.