DeepSeek V4 Pro 0813 posts large agent benchmark jumps over its preview
- Source
- x.com
- Date

DeepSeek V4 Pro 0813 is live on OpenRouter. @deepseek_ai reports large agent gains over V4 Pro Preview: DeepSWE 62.7 (+49.9), CyberGym 83.3 (+30.6), NL2Repo 61.5 (+23.0), and Terminal Bench 2.1 87.9 (+15.8) More providers coming online soon Use it now: https://t.co/1PYoEFbvyK
Context
DeepSeek's V4 Pro 0813 release reported a substantial improvement in completing computer tasks through an . OpenRouter's announcement gives a Terminal-Bench 2.1 score of 87.9, up 15.8 points from V4 Pro Preview, and DeepSeek's release log lists the same score. Terminal-Bench tests agents on tasks performed in a terminal, each with test cases that check the agent's solution. The comparison therefore concerns executing tasks through software tools, rather than simply producing convincing written answers. It remains a developer-reported result.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- sandbox — An isolated environment where AI-generated code or agent actions run without being able to touch anything real.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.




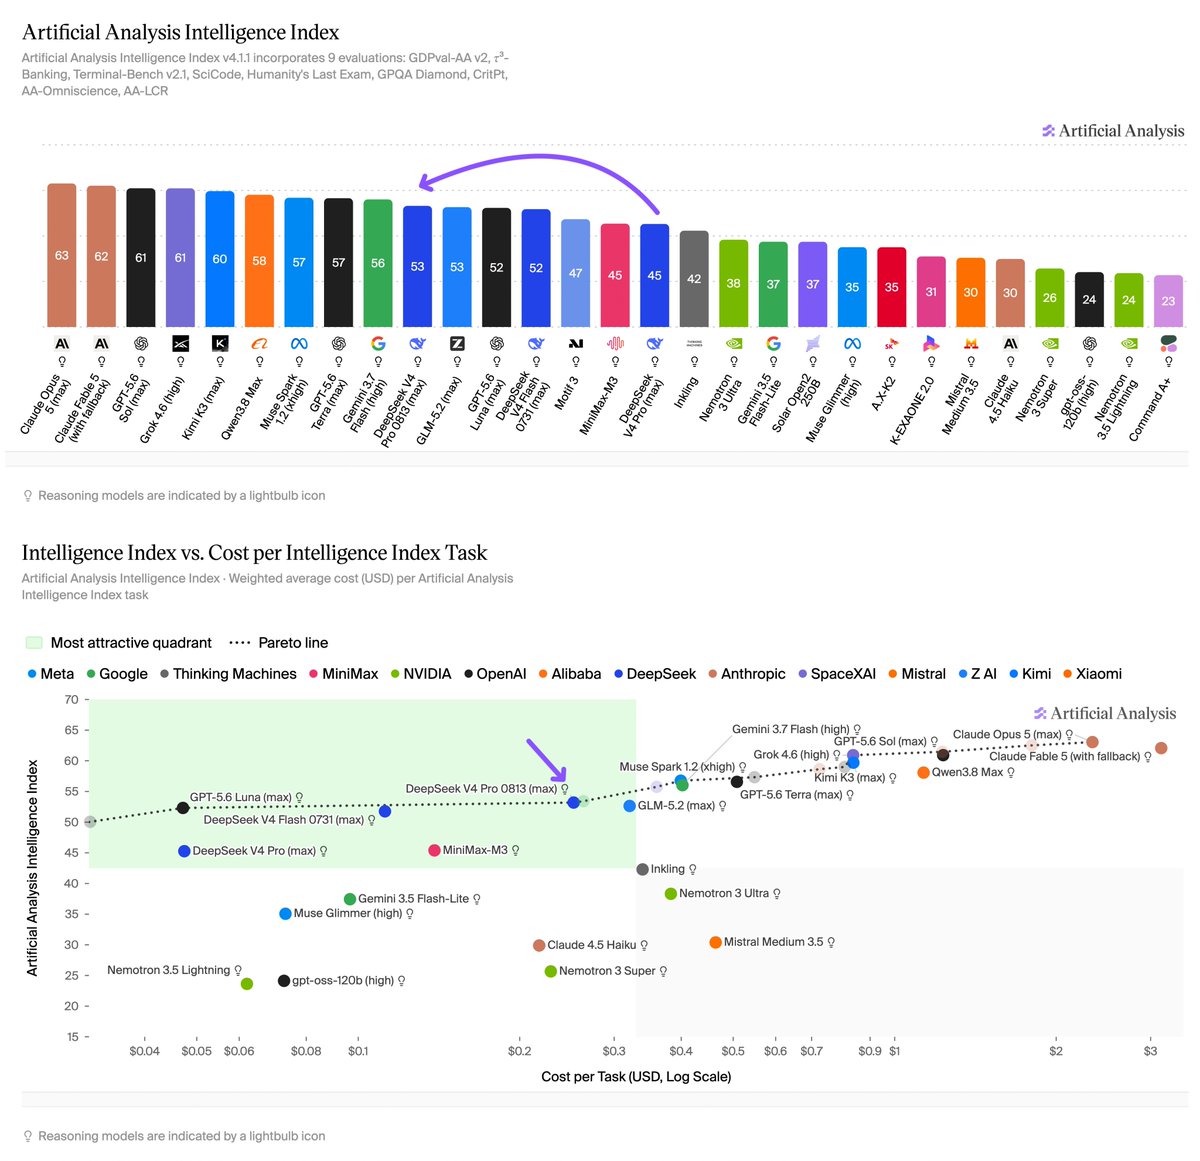 postDeepSeek V4 Pro 0813 scores 53 on the Artificial Analysis Intelligence Index, 8…Artificial Analysis
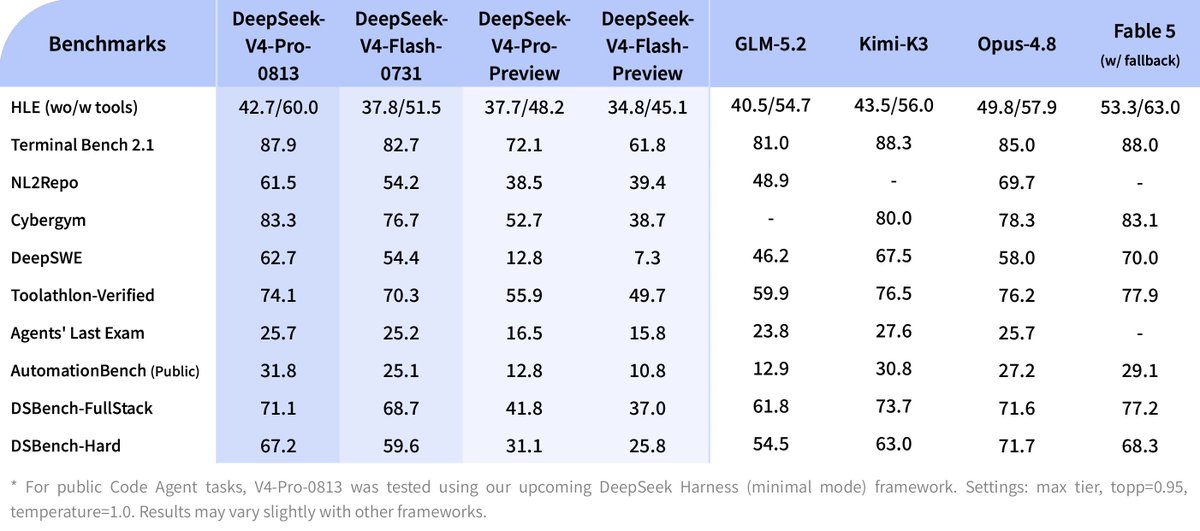 postDeepSeek V4 Pro ships tunable reasoning effortDeepSeek
 articleDeepseek V4 Flash 0731 Scores 50 On The Artificial Analysis Intelligence Index 10 Points Above Previous Deepseek V4 FlashArtificial Analysis articles
Checking sign-in…
Loading comments…