We’re launching DeepSeek-V4-Pro today! 🚀 🔷 Major Agent upgrades with strong pr
- Source
- x.com
- Date

We’re launching DeepSeek-V4-Pro today! 🚀 🔷 Major Agent upgrades with strong production gains! 🔷 Flexible reasoning effort for V4-Pro & V4-Flash: low for simple tasks, high for daily Agent workflows, max for complex tasks. 🔷 Native OpenAI Responses API support, optimized for Codex with one-click setup. V4 Pro is now available on app/web. Try it via “Expert Mode”. V4 Pro is also available via API. Model names remain unchanged—please refer to the API docs for setup details.

Context
DeepSeek's V4-Pro announcement is mostly about how developers call the model. It adds a selectable reasoning effort for both V4-Pro and V4-Flash, with DeepSeek's own guidance on when to use each level: low for simple tasks, high for everyday workflows and max for complex tasks. The setting lets a caller match reasoning effort to the task instead of using the same level for every request.
The second change is native support for OpenAI's Responses API, the interface used by Codex, OpenAI's coding agent. DeepSeek says the support is optimized for Codex with one-click setup, so a developer working in Codex can run it on DeepSeek's model. V4-Pro is also available in DeepSeek's app and website through "Expert Mode" and through the API, where DeepSeek says model names remain unchanged and refers developers to its documentation.
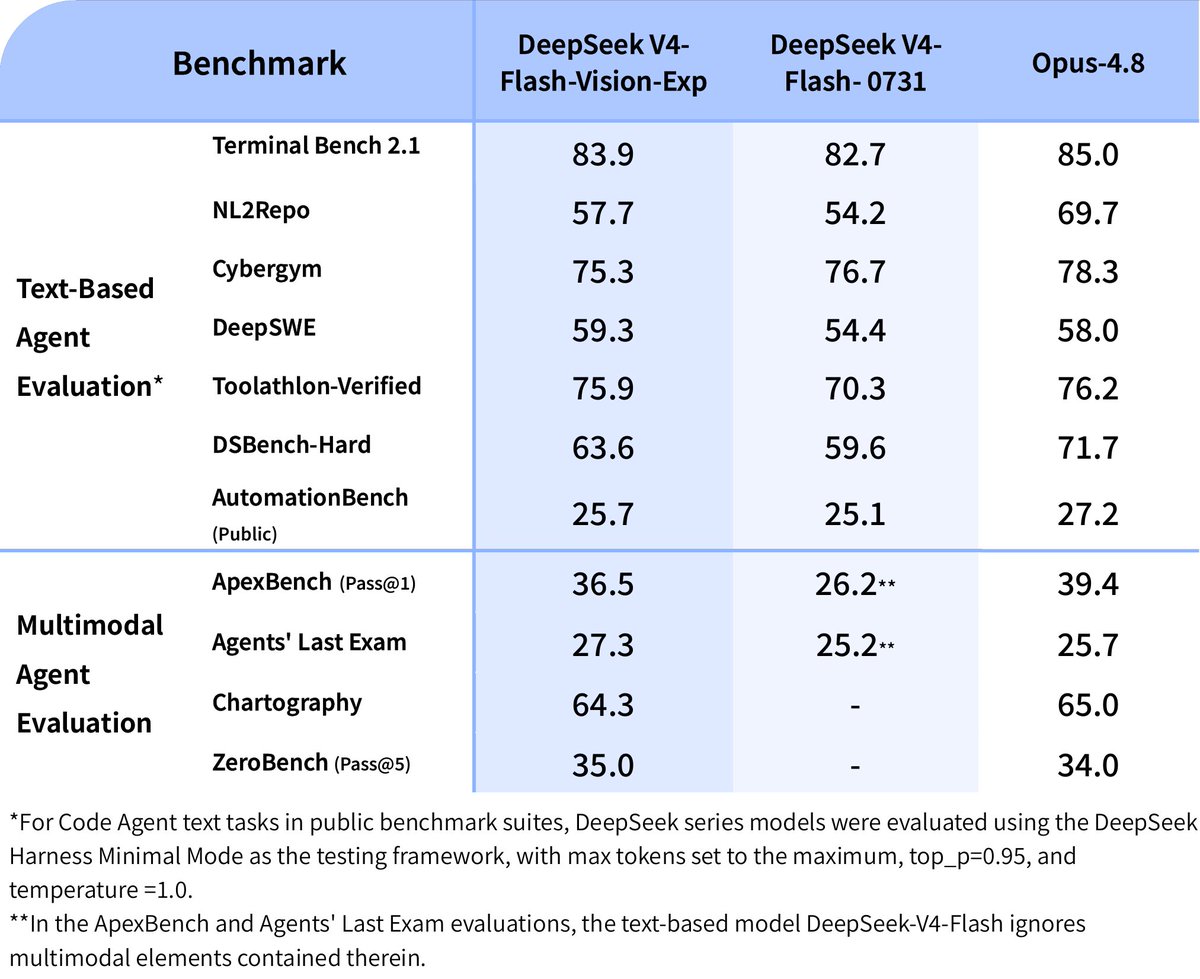
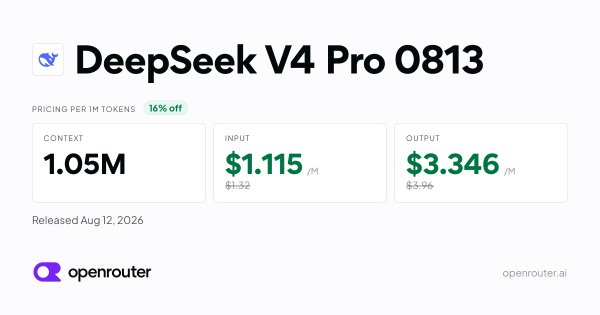
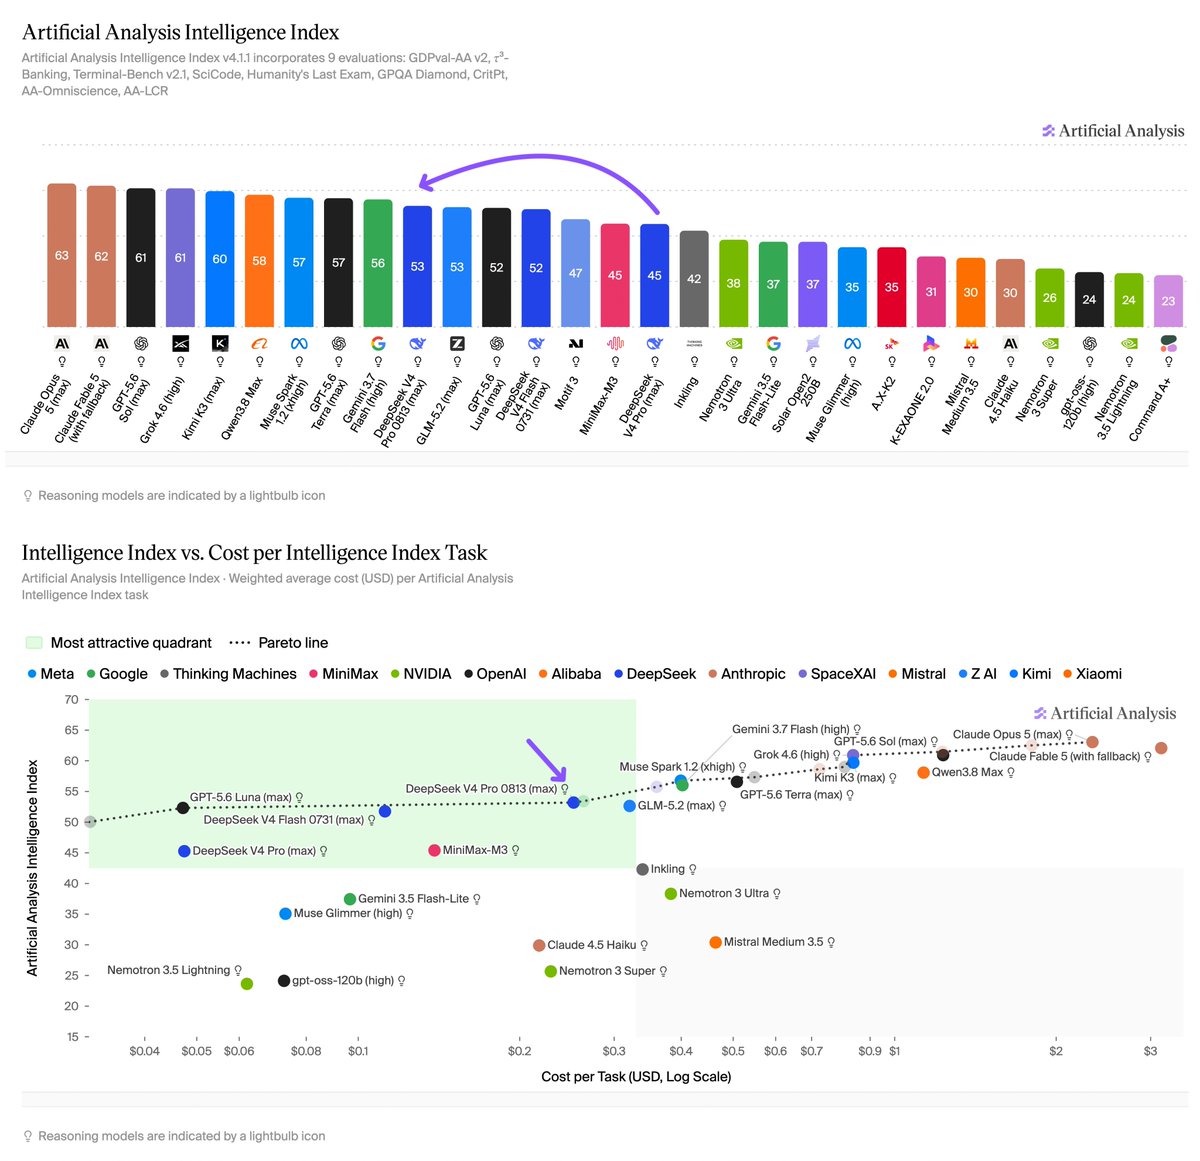
The headline claim, "major agent upgrades with strong production gains," comes with no figures in the post's text. Artificial Analysis's evaluation, posted on August 15, calls the model DeepSeek V4 Pro 0813 and compares it with an April model also named V4 Pro, which suggests this launch updates an existing model line rather than adding a new one. The same thread's second post changes API pricing.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.

Checking sign-in…
Loading comments…