Sonnet 5.5 lands in Devin with a 64.4% FrontierCode score
- Source
- Cognition
- Date

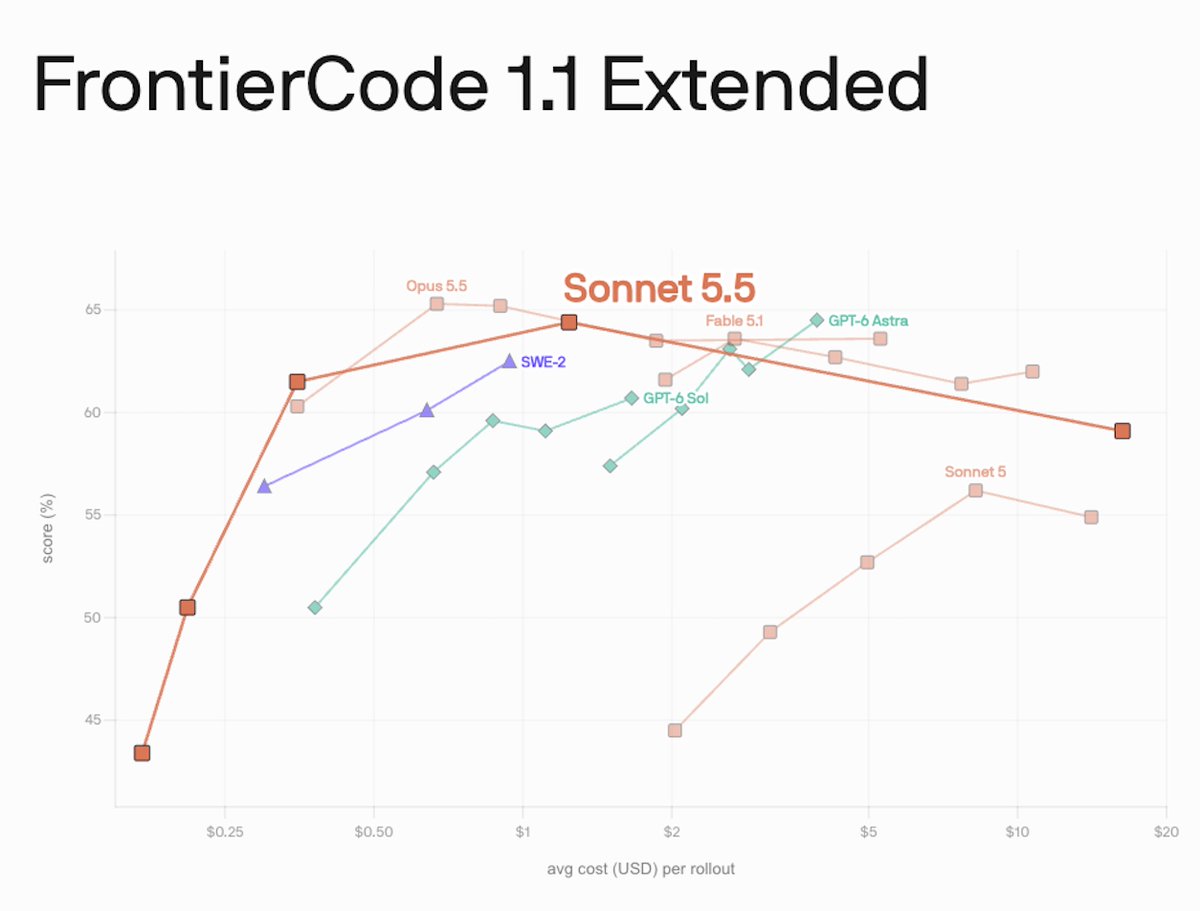
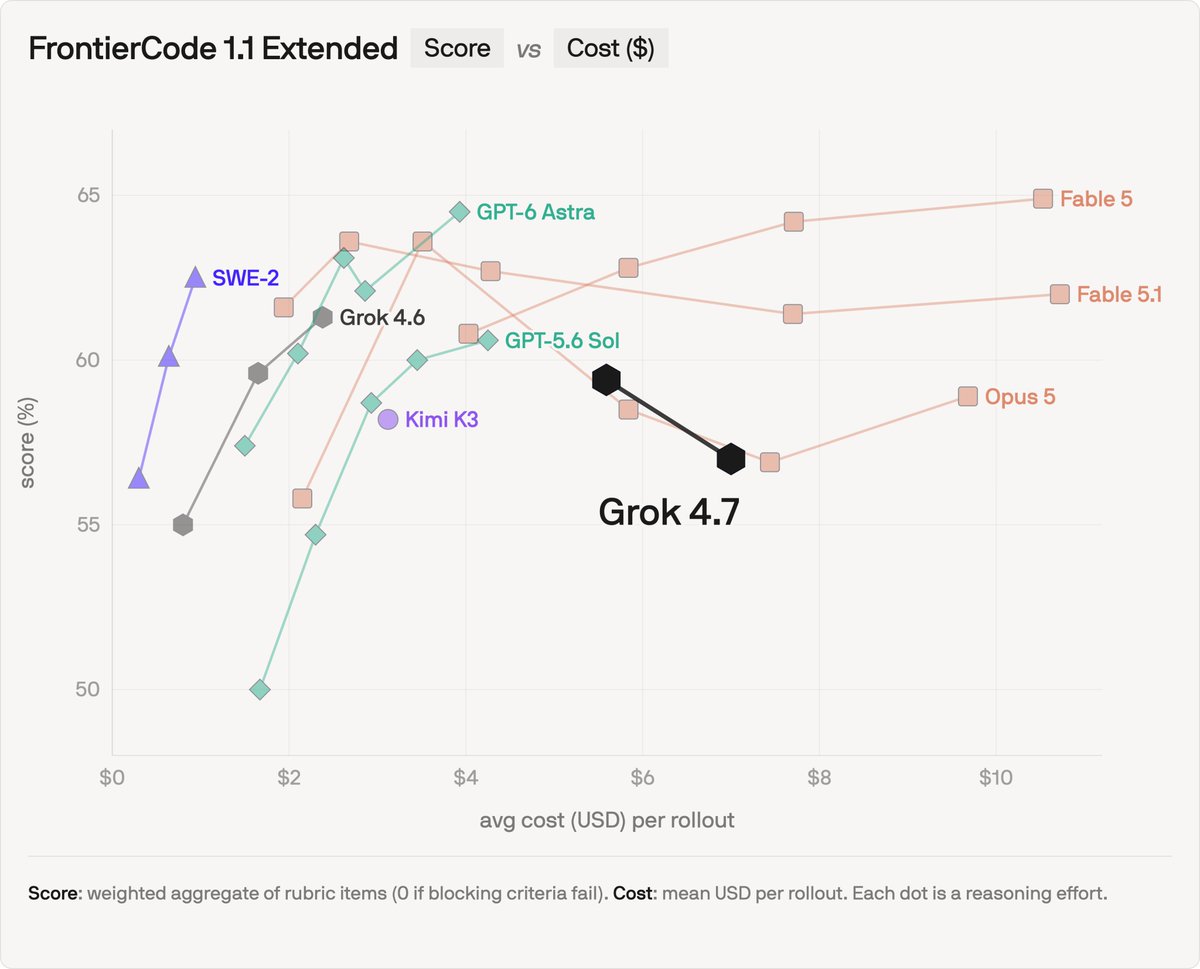
Claude Sonnet 5.5 is now available in Devin Desktop and Devin CLI. On FrontierCode 1.1 Main, it scores 64.4%, a significant improvement from Sonnet 5 (56.2%), surpassing Fable 5.1 at extra high reasoning effort.
Context
Sonnet 5.5, Anthropic's latest model, is now available in Devin Desktop and Devin CLI, Cognition's coding products. On Cognition's own FrontierCode 1.1 Main , a suite the company uses to score models on realistic software engineering tasks, Sonnet 5.5 reportedly scores 64.4%, up from 56.2% for the prior Sonnet 5, and ahead of Claude Fable 5.1 even when Fable is run at its highest reasoning effort setting.
Because FrontierCode is Cognition's own benchmark rather than an independently run one, these numbers describe how Sonnet 5.5 performs on the specific coding tasks Cognition chose to measure, not a broader claim about coding ability. Cognition has also shipped its own coding model, SWE-2, on the same benchmark family, so FrontierCode scores now double as a way the company compares outside models against its own.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…