Grok 4.7 arrives in Devin with 59.4% on FrontierCode Extended
- Source
- x.com
- Date

Grok 4.7 is now available in Devin. On FrontierCode 1.1, Grok 4.7 scores 59.4% on Extended. In our evaluation, we see the model performs very well on hard backend engineering tasks.

Context
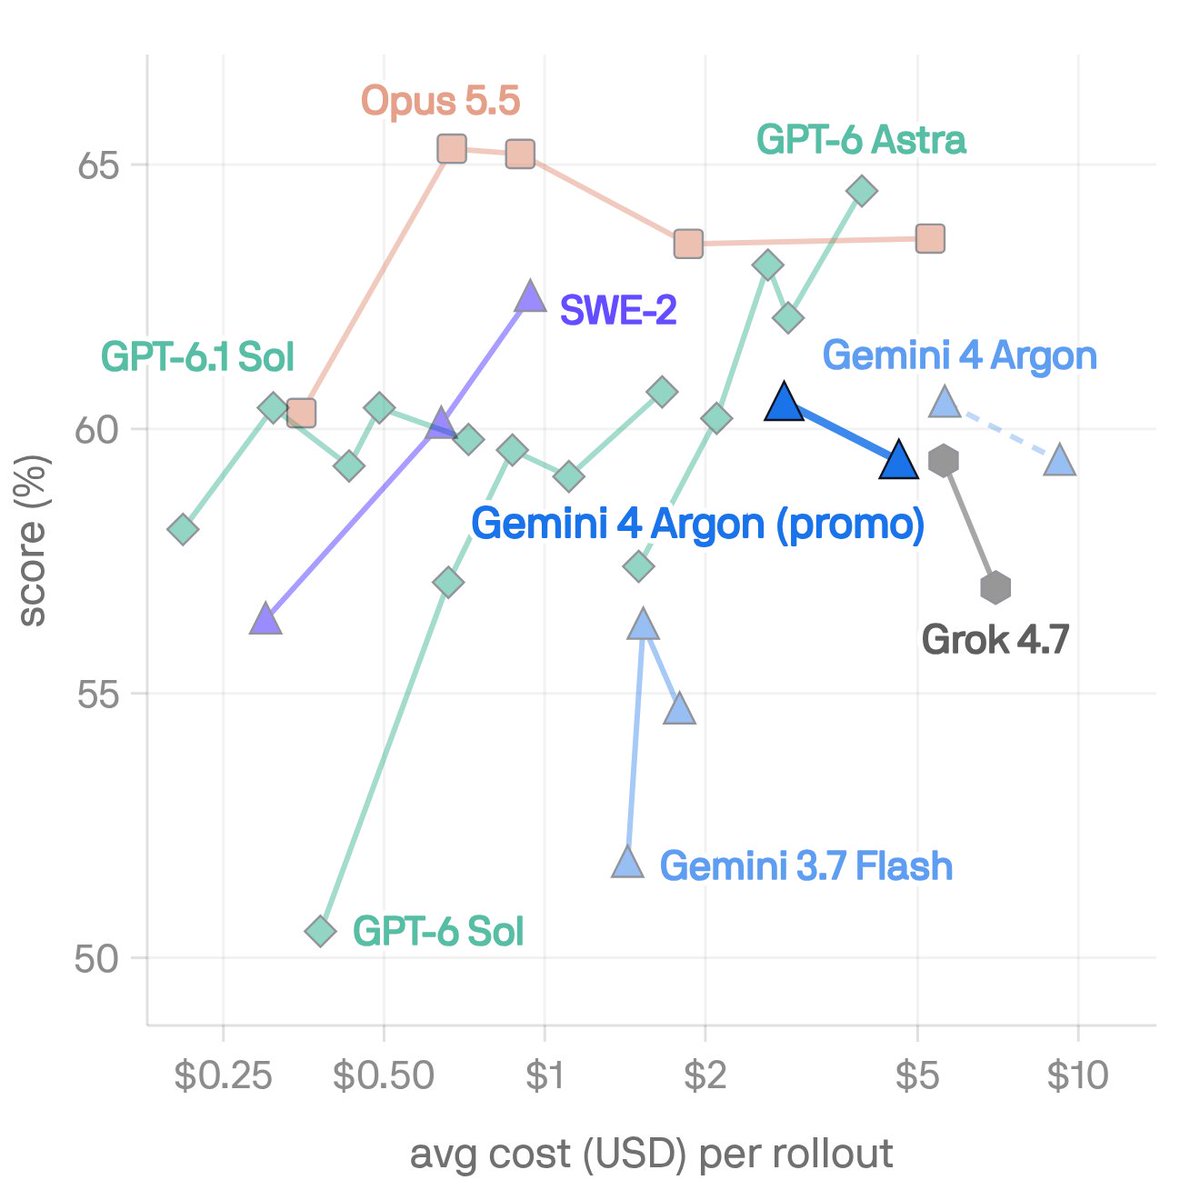
Cognition, the company behind the Devin coding , has added xAI's Grok 4.7 as a model option and reports that it scores 59.4% on the Extended set of FrontierCode 1.1. FrontierCode is Cognition's own , built with open-source maintainers to test whether a model's code change is one a maintainer would actually merge. According to the chart attached to the post, the score is a weighted total of rubric items, and an attempt that fails any blocking requirement scores zero. So 59.4% is not the share of tasks solved; it blends how often the model clears the hard requirements with how clean its changes are.
The chart says more than the post's text. It plots each model's score against its average cost per attempt, with one point per reasoning-effort setting. Read from the chart, Grok 4.7's best point is the 59.4% at roughly $5.60 per attempt, and its other point scores lower, about 57%, at about $7. The earlier Grok 4.6 reaches about 61% at around $2.40. GPT-6 Astra sits near 64.5% for under $4, and Fable 5 near 65% at about $10.50. On Cognition's own measurements, then, Grok 4.7 is the weaker and more expensive of the two Grok models on this test. Cognition says the model does very well on hard backend engineering tasks, but the chart does not separate those tasks out, so that claim cannot be checked from what was posted.
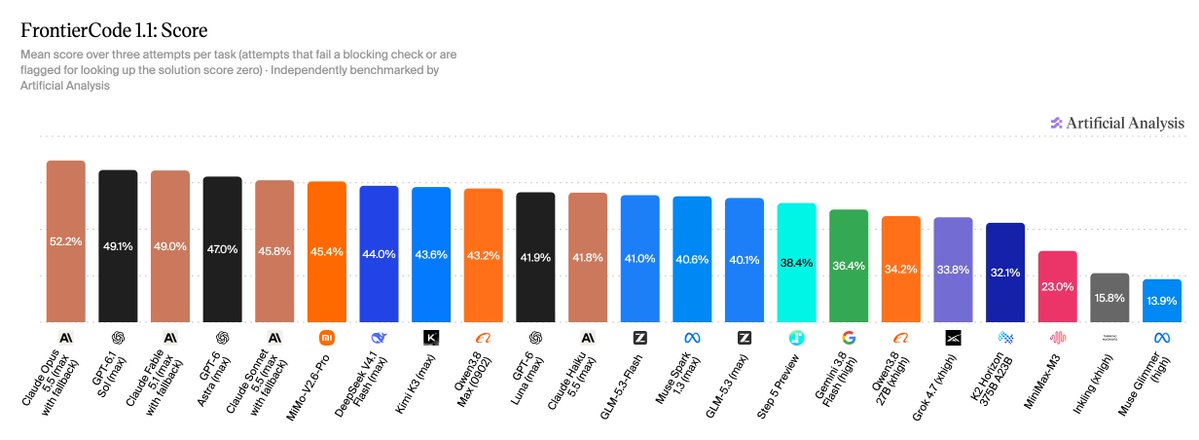
Two things limit how far the number travels. It comes from Cognition's own of the Extended set, while the FrontierCode leaderboard Artificial Analysis launched in October runs only the benchmark's 100-task Main set in its own , so the two sets of scores are not interchangeable. And the next day Cognition added Claude Opus 5.5, saying it took the top spot on FrontierCode 1.1 from Fable 5 at a fraction of the cost, which put one more model ahead of Grok 4.7 on Cognition's test.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.

Checking sign-in…
Loading comments…