Devin Adds GPT-6 Sol and Luna at Sharply Lower Cost
- Source
- x.com
- Date

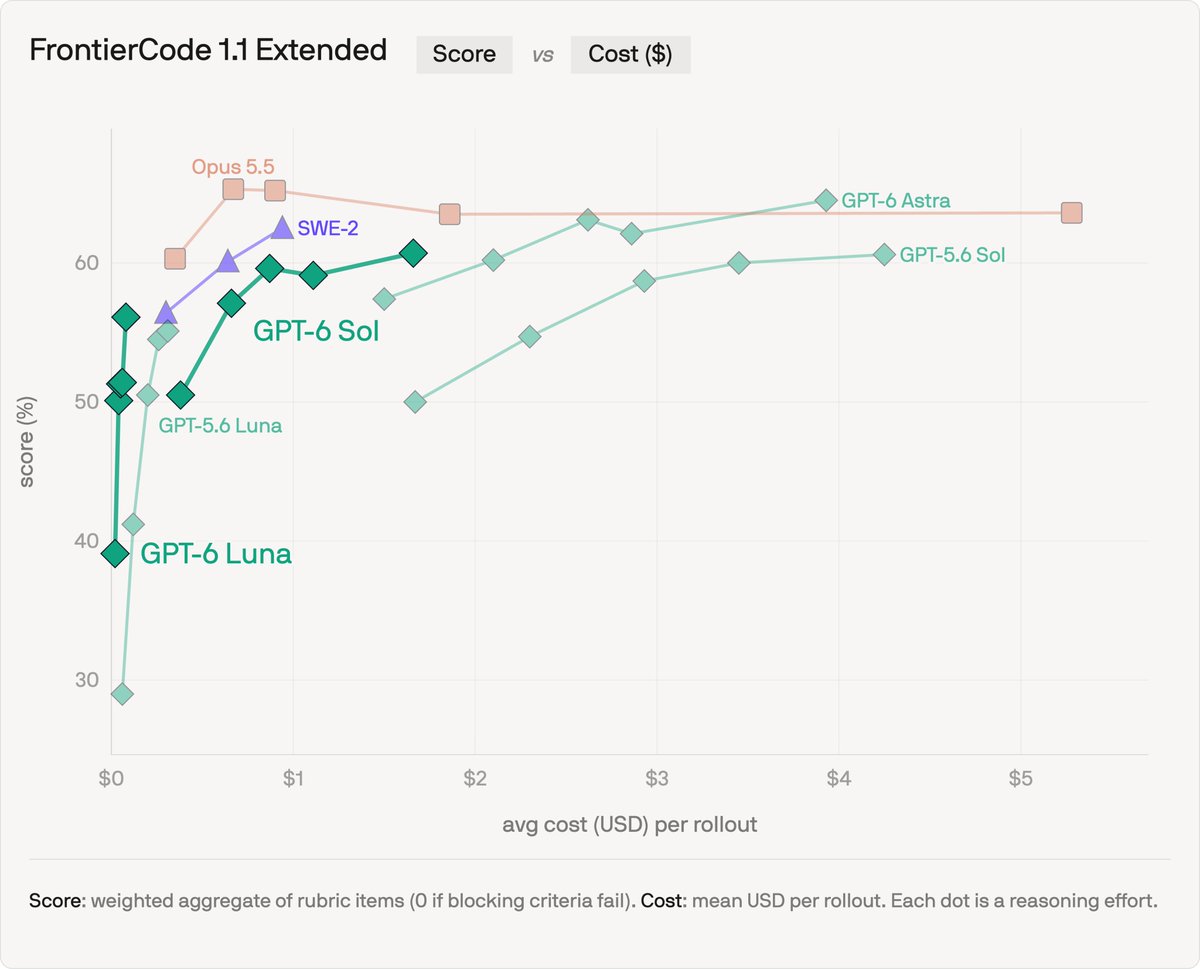
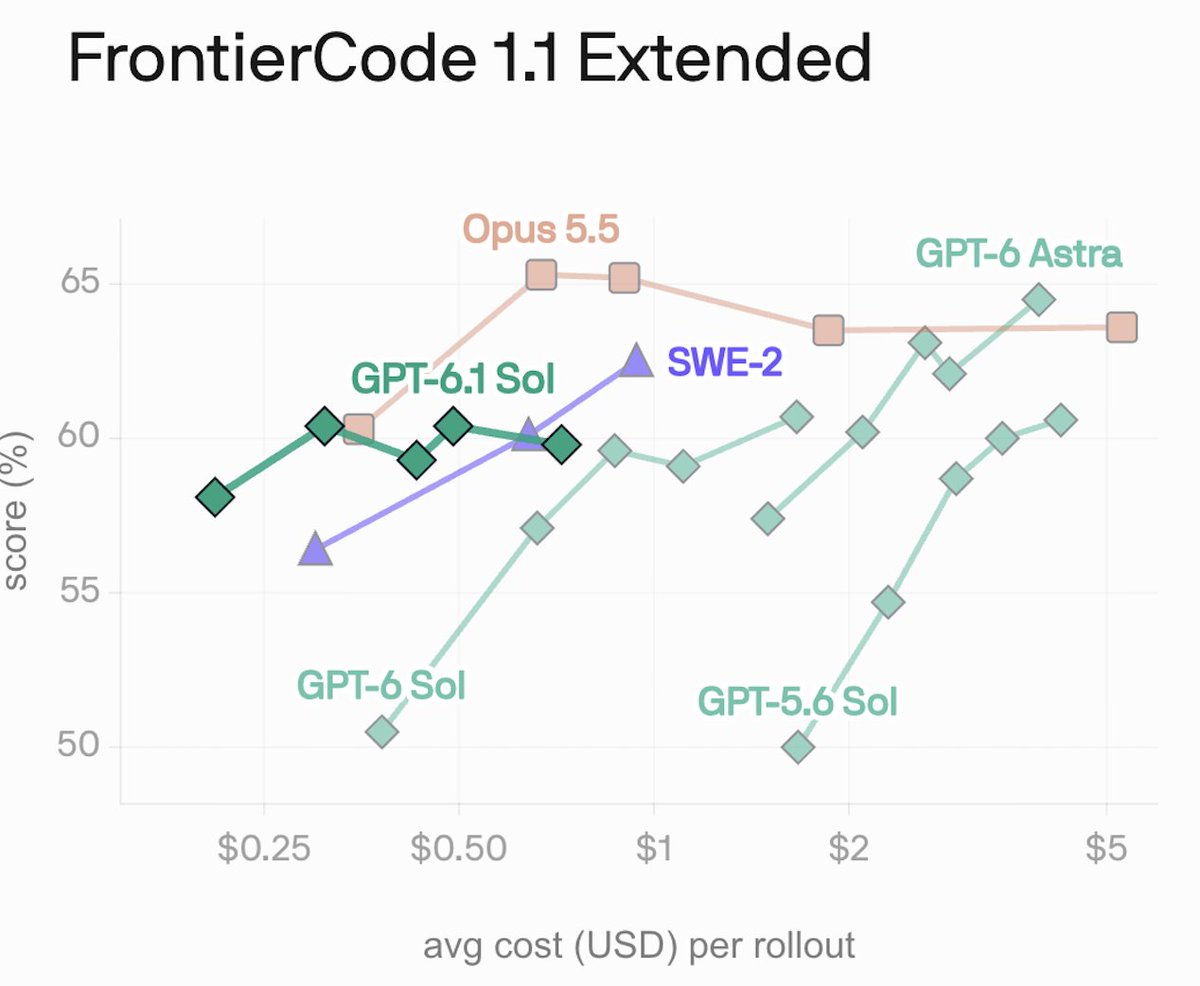
GPT-6 Sol and Luna are now available in Devin. On FrontierCode 1.1, GPT-6 Sol matches GPT-5.6 Sol’s score at 61% lower cost per task. GPT-6 Luna scores above GPT-5.6 Luna at about a quarter of the cost. At under $0.10 per task, it is the cheapest model on the leaderboard.
Context
Cognition, the company behind the coding Devin, says OpenAI's new GPT-6 Sol does the same quality of work on its coding for well under half the cost. In Cognition's post, GPT-6 Sol matches GPT-5.6 Sol's FrontierCode 1.1 score at 61% lower cost per task, and GPT-6 Luna scores above GPT-5.6 Luna at about a quarter of the cost. At under $0.10 per task, Cognition says, Luna is the cheapest model on its leaderboard. Devin added both models the day OpenAI released them at half the API price of GPT-5.6.
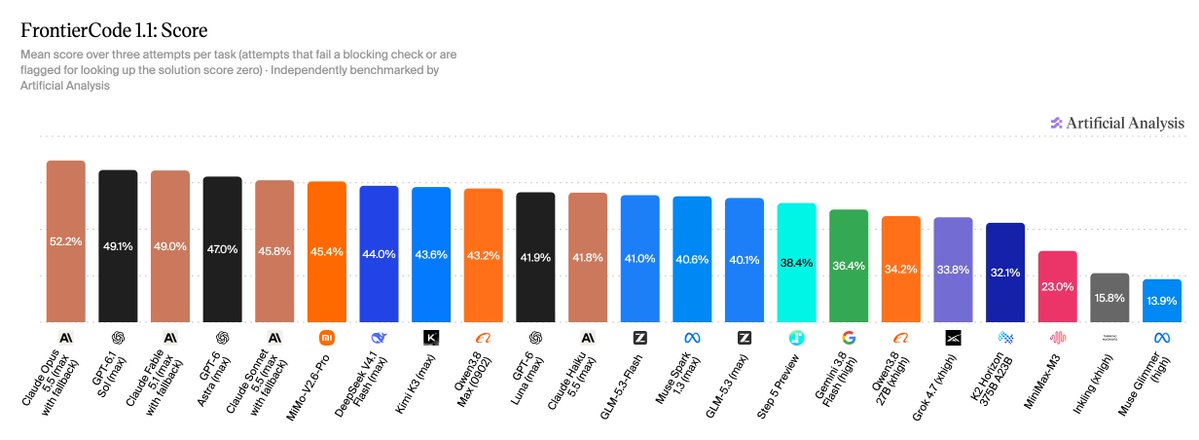
FrontierCode asks whether a maintainer would actually merge the agent's change, not only whether tests pass. Artificial Analysis, which later published its own FrontierCode 1.1 leaderboard, describes tasks built with open source maintainers who spent more than 40 hours on each one. The agent must change a real open source repository, and grading covers unit tests plus behaviour such as oversized diffs or edits to files outside the task. Failing any blocking check scores zero. A matching score therefore means the cheaper model produced changes that were as mergeable by this standard, not merely changes that compiled.
These are Cognition's own results, run in its own setup. The chart attached to the post is labelled FrontierCode 1.1 Extended, plots each model at several reasoning-effort settings, and measures cost as the average dollars per attempt; the post does not say which settings the 61% comparison uses or give the scores in text. Cost per task combines the per- price with how many tokens the agent spends, and Cognition does not separate the two, though OpenAI's 50% price cut, which Tibo also announced, would account for much of the change. For someone picking a model for agentic coding, the supported conclusion is narrow: on Cognition's run of this benchmark, the newer Sol kept its quality while getting much cheaper.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…