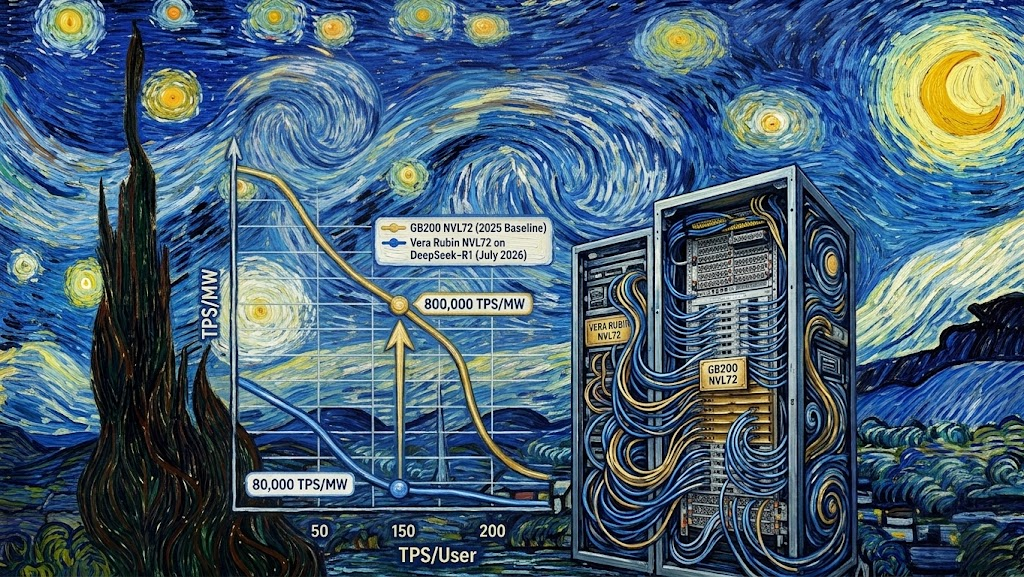
Agent serving is long-context and prefix-heavy, and this measures it directly. Vera Rubin delivers up to about 5.7x the throughput per megawatt of GB300 on DeepSeek V4 Pro, which signals where inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → cost for coding agents is heading.
Key takeaways · AI-distilled
In the October 15, 2026 AA-AgentPerf results, about 96% of counted throughput was cached input. Power covered GPUs and HBM, excluding CPUs, networking and cooling. The reported tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per megawatt were not generated tokens per datacenter megawatt.
AA-AgentPerf reported Vera Rubin's largest DeepSeek V4 Pro lead near 190 output tokens/s per user. Its peak-throughput advantage per megawatt was 1.14x. The October 2026 5.7x headline described one operating point, not every load.
The October 2026 DeepSeek V4 Pro comparison changed when first-token waiting time was included. GB300 matched or beat Vera Rubin's throughput per megawatt at most end-to-end speeds, despite Rubin's advantage on the decode-speed chart.
NVIDIA's October 2026 DeepSeek V4.1 Flash runs capped replies at 2,048 tokens versus 16,384 for other results. About 2% hit the cap and average replies were shorter, which Artificial Analysis said modestly favored Rubin throughput.
AA-AgentPerf replayed coding-AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → trajectories with tool pauses and growing context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →. In its October 2026 workload, an average 97% of input repeated the previous request, making cache reuse and session-aware routing central to serving performance.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.