PrismML puts a 1-bit vision-language model on Snapdragon smart glasses
- Source
- x.com
- Date

Today at Snapdragon Summit, we’re announcing 1-bit Bonsai vision-language model running locally on AI smart glasses powered by Snapdragon® AR1 Gen 1 Platform. With Qualcomm Technologies, we optimized Bonsai for Snapdragon Hexagon™ NPU, delivering 4x lower memory usage and 2x faster token generation for equivalent intelligence, making it possible to bring significantly more capable AI to run directly on highly constrained wearable devices. We believe model-hardware co-design will be critical to bringing increasingly capable AI from the cloud onto the devices people use every day.

Context
PrismML announced at Snapdragon Summit a 1-bit version of its Bonsai vision-, a model that takes images as well as text, running locally on AI smart glasses built on Qualcomm's Snapdragon AR1 Gen 1 platform. Running locally means the model works on the glasses rather than sending requests to the cloud. A 1-bit model stores each of its weights in a single bit, which cuts the memory the model needs on hardware PrismML calls highly constrained.
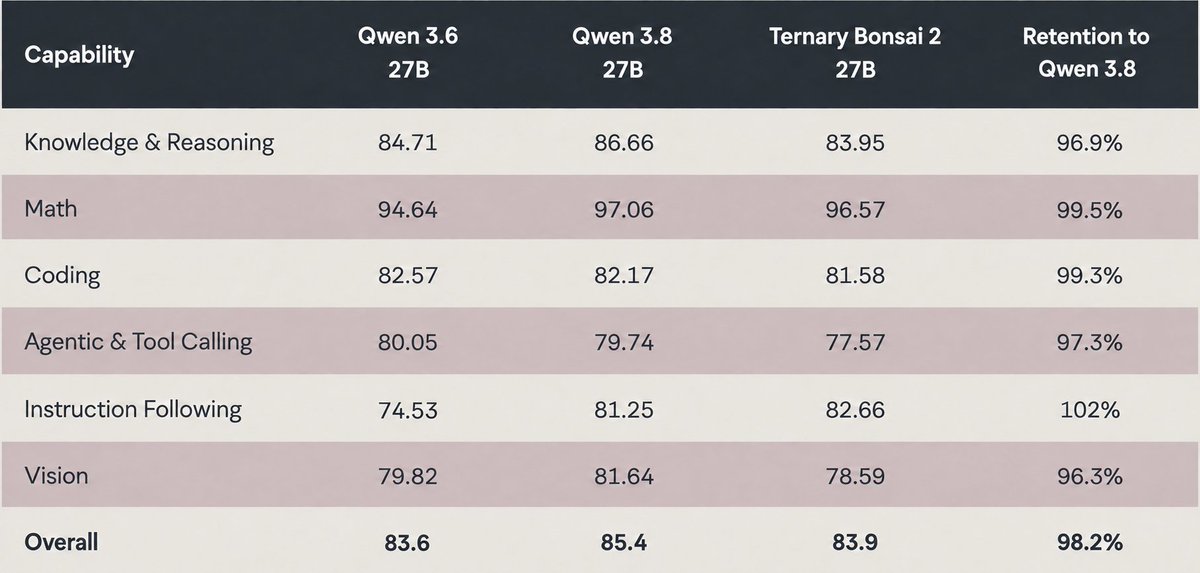
PrismML says it worked with Qualcomm Technologies to tune Bonsai for the chip's Hexagon NPU, the processor built for AI workloads, and reports 4x lower memory use and 2x faster generation "for equivalent intelligence." The announcement text does not say what those figures are measured against, such as which model or precision serves as the baseline, so they read as PrismML's claim rather than a comparison a reader can check. PrismML's broader argument is that designing models and hardware together will be how more capable AI moves from the cloud onto everyday devices. Bonsai is PrismML's line of compressed models, which earlier in September included the larger Bonsai 2 27B.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.

Checking sign-in…
Loading comments…