Nvidia Nemotron 3 Ultra Launch Announced
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
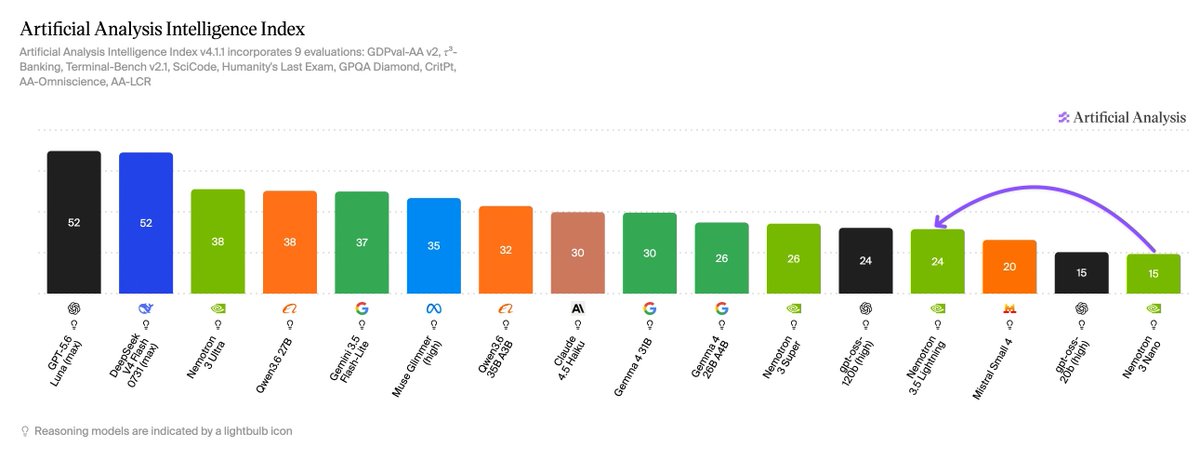
NVIDIA announced Nemotron 3 Ultra in Jensen Huang's Computex keynote, and Artificial Analysis, which partnered with NVIDIA to evaluate it before release, puts it at the top of US open-weights models (artificialanalysis.ai). It scores 48 on the Artificial Analysis Intelligence Index, well ahead of the next US open-weights models: Gemma 4 31B at 39, Nemotron 3 Super at 36 and gpt-oss-120b at 33. It is not the open-weights leader overall. The Chinese-led frontier is still ahead, with Moonshot AI's Kimi K2.6 at 54.
The model has about 550 billion total parameters, of which 55 billion are active, a sparsity of about 90%: only a small fraction of the network is used for each . That makes it the largest Nemotron 3 model so far, and Artificial Analysis calls it the largest recent US open-weights release. The scores were measured on the BF16 weights. As with Nemotron 3 Super, the model will also be offered in NVFP4, a lower-precision format intended for higher performance.
Artificial Analysis also measured speed on a pre-release DeepInfra endpoint, where the model served over 300 tokens per second. It says similar-sized models from China-based labs such as DeepSeek and Moonshot are generally served at 50 to 100 tokens per second today, while gpt-oss-120b is served at similar speeds but with significantly lower intelligence. These were early figures, and Artificial Analysis said it would share fuller analysis and benchmarks at release, which it did in its release-day analysis four days later.
- Artificial Analysis evaluated the BF16 weights with NVIDIA; as with Nemotron 3 Super, the model will also ship in NVFP4 quantization for higher inference performance.
- Its score of 48 is well ahead of other US open-weights models, Gemma 4 31B (39), Nemotron 3 Super (36) and gpt-oss-120b (33), but behind China-led Kimi K2.6 at 54.
- Similar-size models from DeepSeek and Moonshot are generally served at 50-100 tokens per second; gpt-oss-120b reaches speeds comparable to Nemotron 3 Ultra but with much lower intelligence.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.




Checking sign-in…
Loading comments…