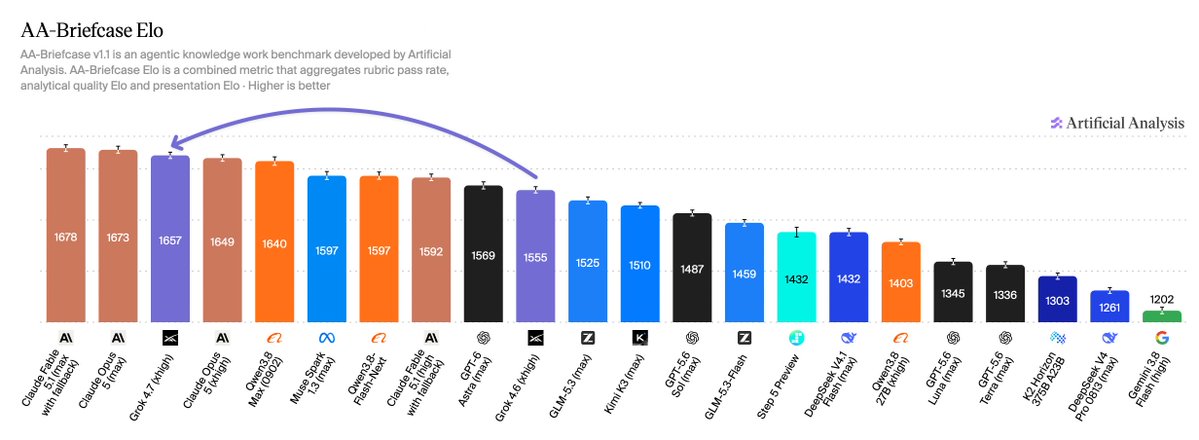
Better analysis does not guarantee a better-looking deliverable. Artificial Analysis' Grok 4.7 evaluation reported that its knowledge-work gains were driven by analytical quality, while its presentation score was slightly lower than Grok 4.6's.
The report also distinguishes coding results obtained with Grok Build from the standardized agent harnessThe scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.Full definition → used for its broader intelligence tests. That prevents a gain in one AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → setup from being read as a universal model improvement. For document-heavy work, the component results are more informative than the headline alone: stronger reasoning, polished output and economical tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → use are separate qualities.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.