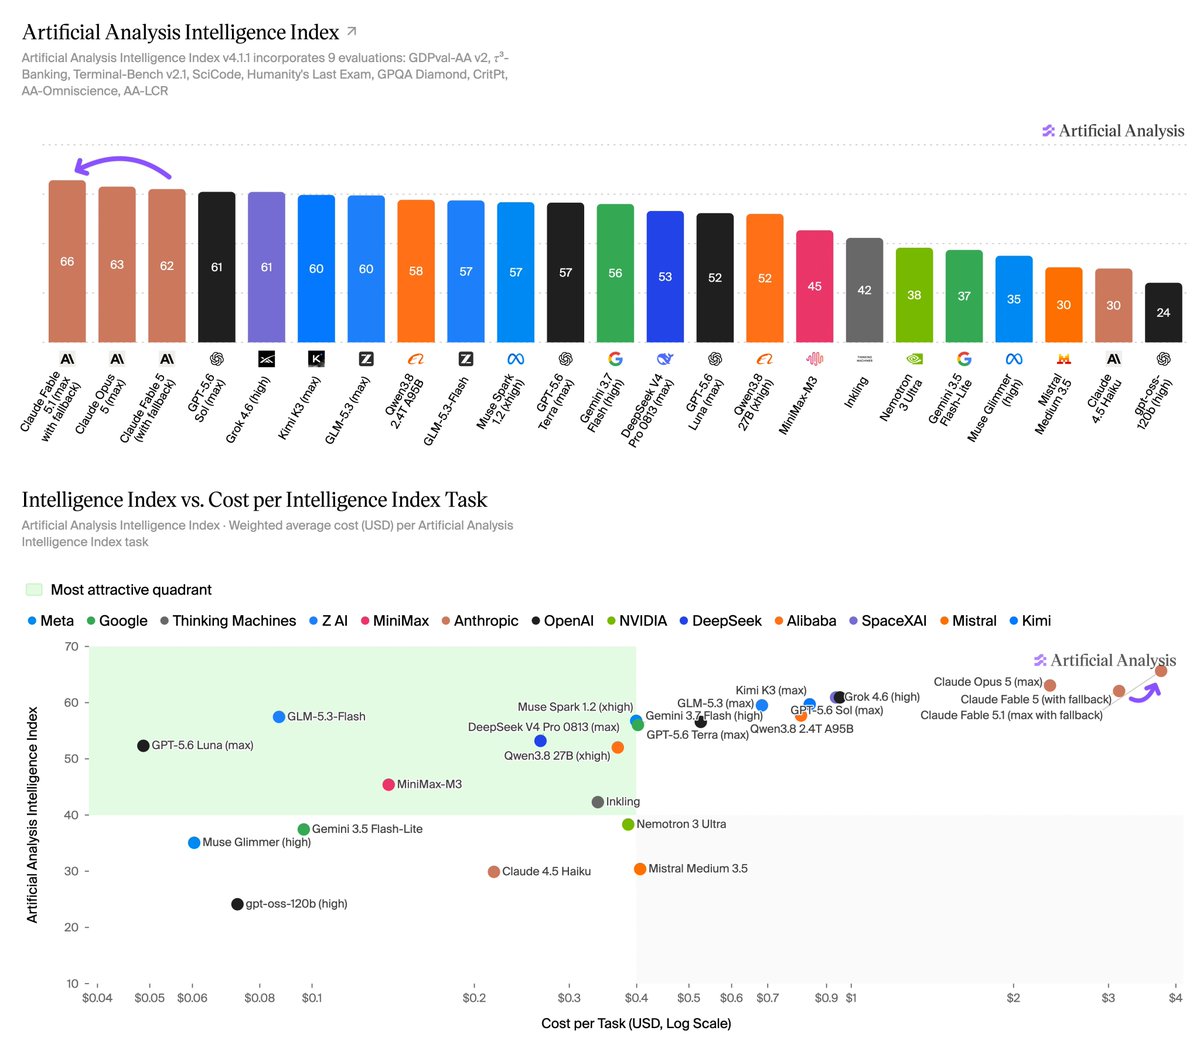
Fable 5.1 tops the index at 66 but costs 20% more per task than Fable 5 despite a 75% cache read price cut, because it uses about 1.7x the output tokens.
Key takeaways · AI-distilled
Artificial Analysis evaluated Fable 5.1 with Anthropic's default fallback enabled. Opus 4.8 or Opus 5 served about 4% of output tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →, so the reported score describes that configured system.
Fable 5.1's reported cost per Intelligence Index task rose 20% despite a 75% cache-read price cut. Artificial Analysis attributes the increase to about 1.7 times as many output tokens as Fable 5.
Artificial Analysis reports that Fable 5.1 answers more factual questions correctly than Fable 5 but also answers more often when wrong. The effects offset each other on its AA-Omniscience Index.
Fable 5.1's GDPval-AA v2 lead over Opus 5 lies within overlapping confidence intervals. On AA-Briefcase, the near-equal overall scores hide stronger analytical quality and weaker presentation for Fable 5.1.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.