FrontierCode 1.1 leaderboard grades coding models on merge-readiness
- Source
- x.com
- Date
FrontierCode debuted from Cognition in June 2026 and has been updated to version 1.1. Artificial Analysis now runs it through a shared harness and publishes the results. The tasks are private, maintainer-grade changes to open-source projects, which reduces the chance that models have seen them during training. Scoring combines unit tests with merge-readiness criteria such as diff size and scope, so an agent that passes tests while rewriting half a module or wandering outside the request loses points. That matches a common complaint about coding agents in review: the change works but is too large or touches things nobody asked for. Hosting by a third party also makes cross-model comparisons easier to trust than vendor-run numbers. Teams choosing a coding model can use these results as one input on code quality, alongside pass-rate benchmarks and their own repositories.

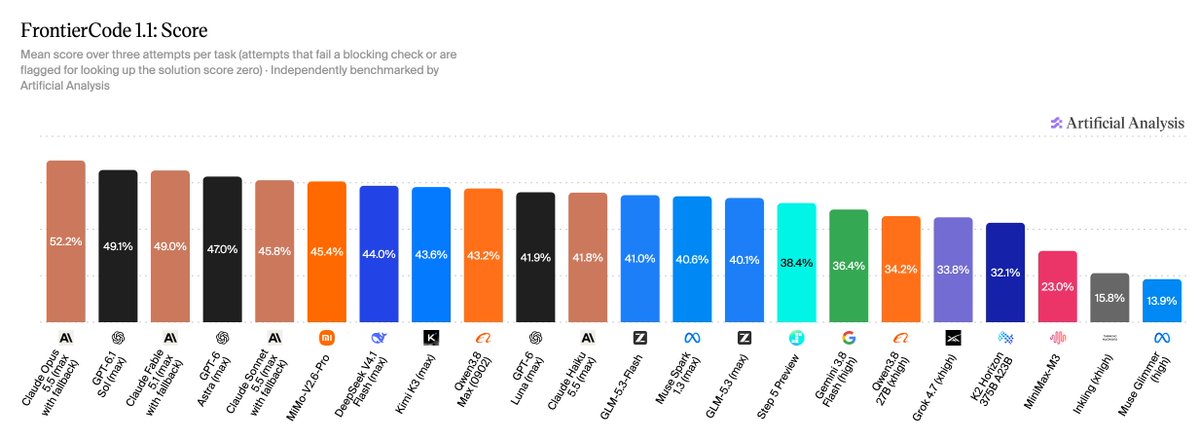
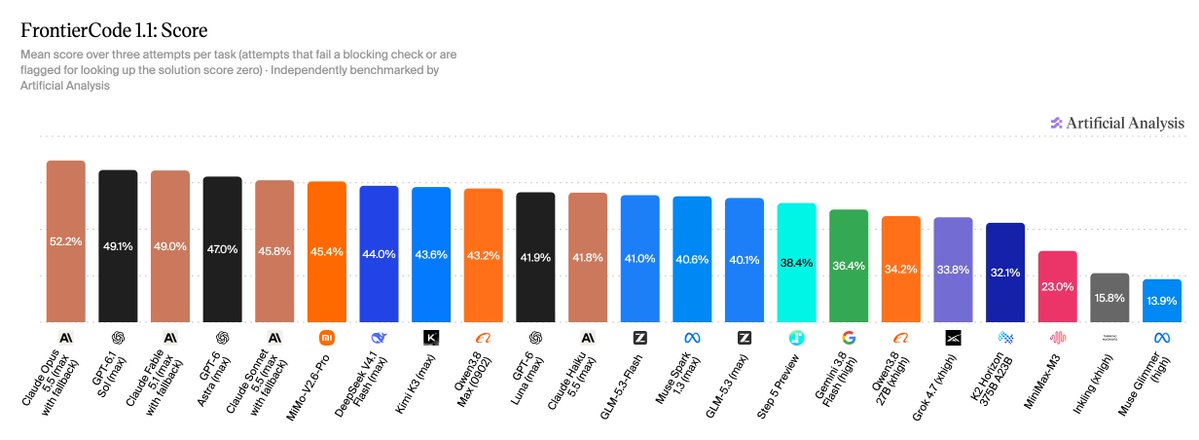
We're launching our leaderboard for FrontierCode 1.1, a private evaluation from Cognition that tests models on completing coding tasks in a way that would actually get merged by maintainers of real-world repositories @cognition announced FrontierCode in June 2026 and updated it to version 1.1 in July. Cognition built the dataset with open source maintainers who spent more than 40 hours per task. Each task requires the agent to make a change to a real open source repository, then checks both unit tests and qualitative tests for what maintainers would require to merge the change. We run FrontierCode 1.1 Main, the primary 100-task set of the benchmark's 150 tasks, using our Stirrup open source reference harness for apples-to-apples comparisons across models. All tasks are private to avoid contamination. Each attempt is graded with both blocking and non-blocking criteria. An attempt that fails any blocking check scores zero, and one that passes them all scores between 70% and 100%. Unlike other coding evaluations, FrontierCode has a more holistic view of success based on real usage. Models need to pass unit tests, but are also assessed on behaviors like making excessive changes and…
Context
Artificial Analysis' FrontierCode 1.1 announcement evaluates whether coding agents produce changes that meet maintainers' requirements. The private from Cognition checks tests alongside issues such as unnecessary edits and changes outside the task's scope. Artificial Analysis runs the 100-task Main set using the same reference across models.
The headline score combines mandatory checks with additional quality criteria. Failing any mandatory check earns zero; passing all of them earns between 70% and 100%. The reported leader, Anthropic's Claude Opus 5.5 (max with fallback), passed mandatory checks in 58% of attempts but scored 52% overall. That difference shows why the leaderboard score cannot be read as the percentage of tasks completed successfully.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
Checking sign-in…
Loading comments…