Meta has released Muse Spark 1.2. It's their third release in four months and sc
- Source
- x.com
- Date

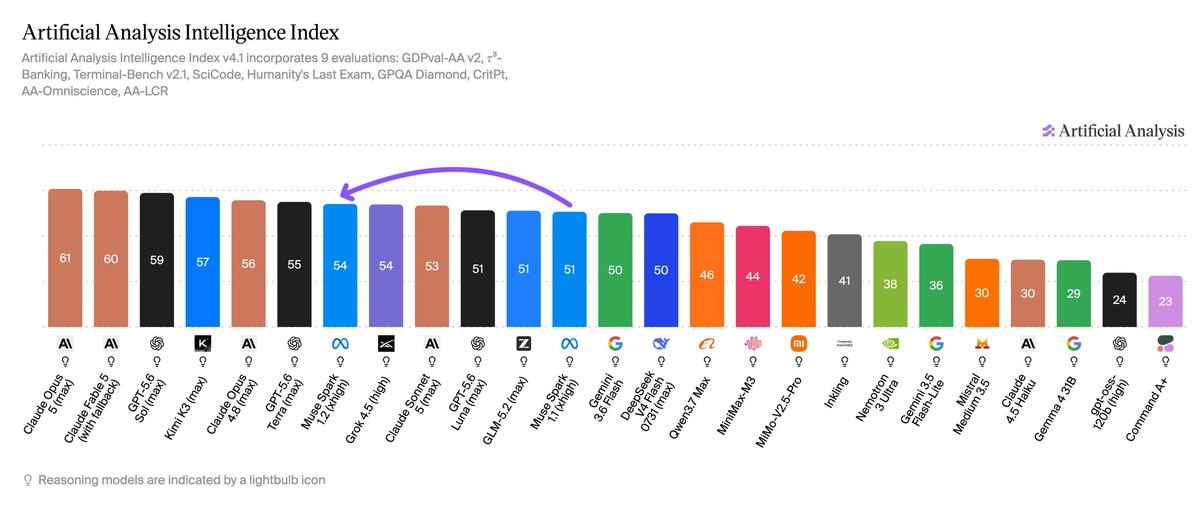
Meta has released Muse Spark 1.2. It's their third release in four months and scores 54 on the Artificial Analysis Intelligence Index, significantly improving agentic knowledge work capabilities over prior releases and putting Meta next to SpaceXAI in a tie for third place amongst US labs Muse Spark 1.2 (xhigh) lands at 54, up 3 points from Muse Spark 1.1 (51) and 11 points from Muse Spark 1.0 (43, April). It enters effectively tied with GPT-5.5 (xhigh, 55) and Grok 4.5 (high, 54), narrowly behind current frontier models Claude Opus 5 (max, 61), Claude Fable 5 (max w/ fallback, 60), GPT-5.6 Sol (max, 59), and Kimi K3 (max, 57) Congratulations to @AIatMeta, @finkd, and @alexandr_wang on the release! Key Takeaways: ➤ Muse Spark 1.2 gets closer to the frontier on agentic knowledge work. At Muse Spark 1.1's launch, we noted agentic knowledge work as its clearest gap; Muse Spark 1.2's gains help to close this. Its GDPval-AA v2 Elo rose 260 points to 1631, #5 among all models we have benchmarked and ahead of Claude Opus 4.8 (max, 1588). Terminal-Bench 2.1 gained 2 points (78% to 80%), and Tau3-Bench Banking rose 2 points (25% to 27%) ➤ Among the most cost-efficient models at its…
Context
Meta's Muse Spark 1.2 gained most of its ground on agentic knowledge work, where a model uses tools over many steps to produce finished work. Artificial Analysis, an independent firm that benchmarks AI models, scored it at 54 on its Intelligence Index on August 5, up from 51 for Muse Spark 1.1 and 43 for Muse Spark 1.0 in April. The firm's chart puts it level with Grok 4.5 and behind Claude Opus 5 at 61, and the firm describes Meta as tied with SpaceXAI for third place among US labs.
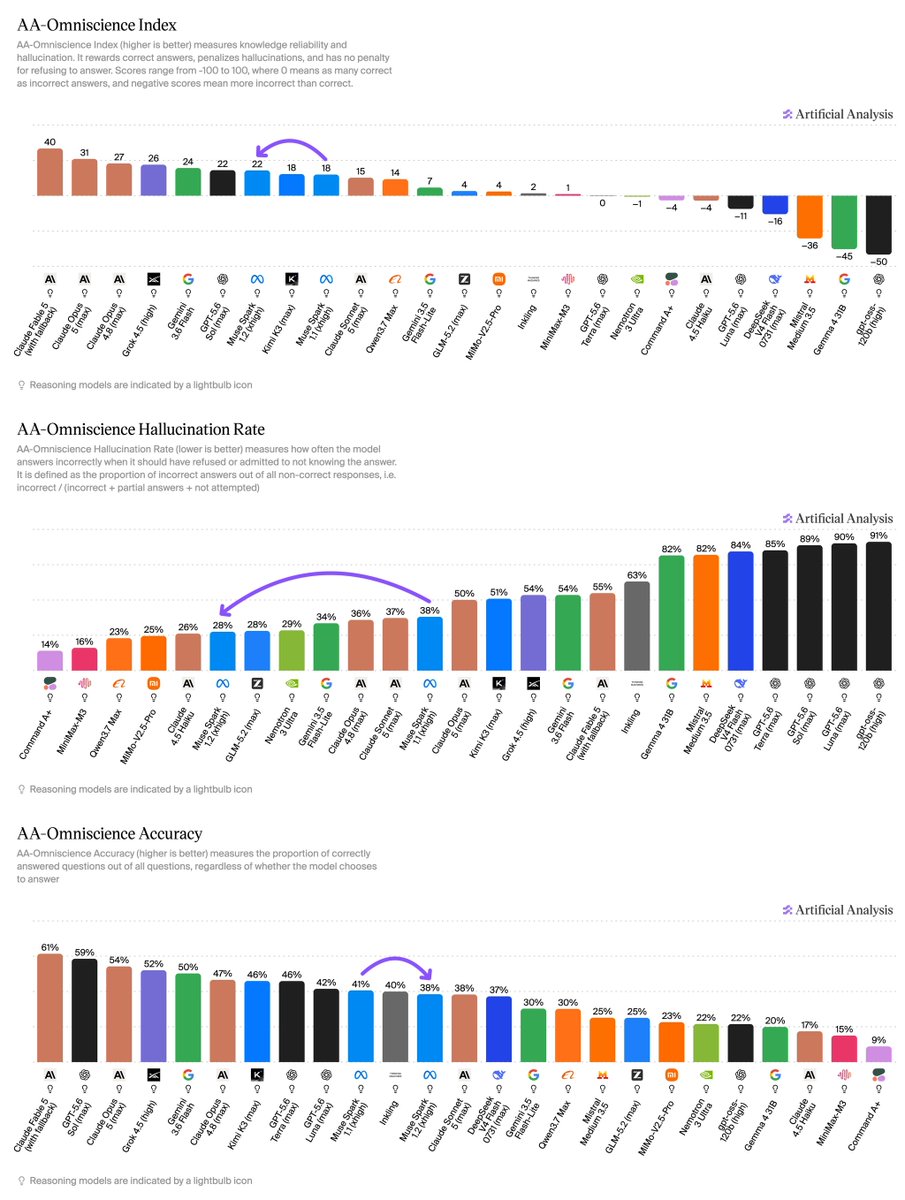
The Intelligence Index is a weighted composite of separate tests, so 54 is not a percentage of questions answered. The version in use that day, 4.1, combined nine evaluations, and the version history on the firm's methodology page shows that it weighted agentic tasks at 34%, coding and scientific reasoning at 24% each, and general knowledge at 18%. Muse Spark 1.2's largest change came on GDPval-AA v2, in which AI judges compare two models' finished work on tasks from 44 occupations and the results become an Elo rating: it rose 260 points to 1631, fifth among the models the firm has tested. Terminal-Bench 2.1 and the τ³-Banking customer-support test each rose 2 points, while the scientific reasoning tests barely moved, with a small gain on CritPt and small drops on SciCode and Humanity's Last Exam. Its AA-Omniscience result, which improved because the model declined more questions, is explained separately.
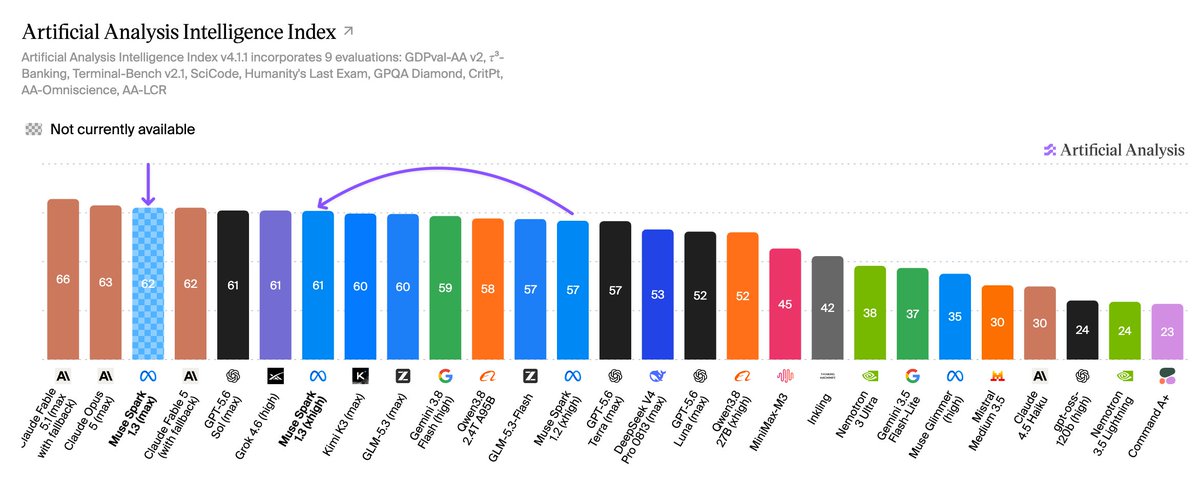
The 54 is a version 4.1 score and compares only with scores from that version. A day later the firm moved the index to version 4.1.1, which replaced grader models and updated τ³-Banking, so scores published after that patch are not directly comparable with this one. The index has since been rebuilt as version 5, which no longer includes GDPval-AA, so the test where Muse Spark 1.2 improved most no longer feeds the current index.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.





Checking sign-in…
Loading comments…