Gemini 4 Neon nears Opus 5.5 on FrontierCode 2.0 at a third of the cost
- Source
- x.com
- Date

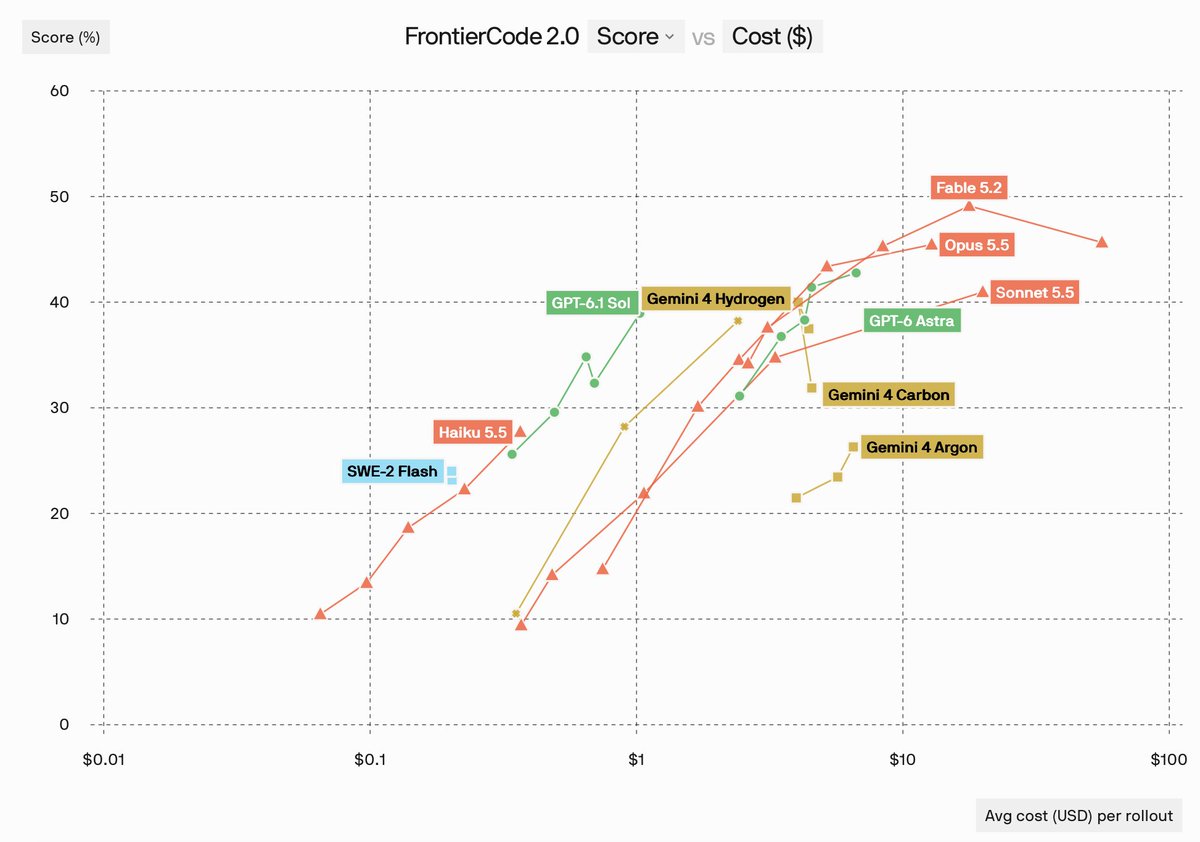
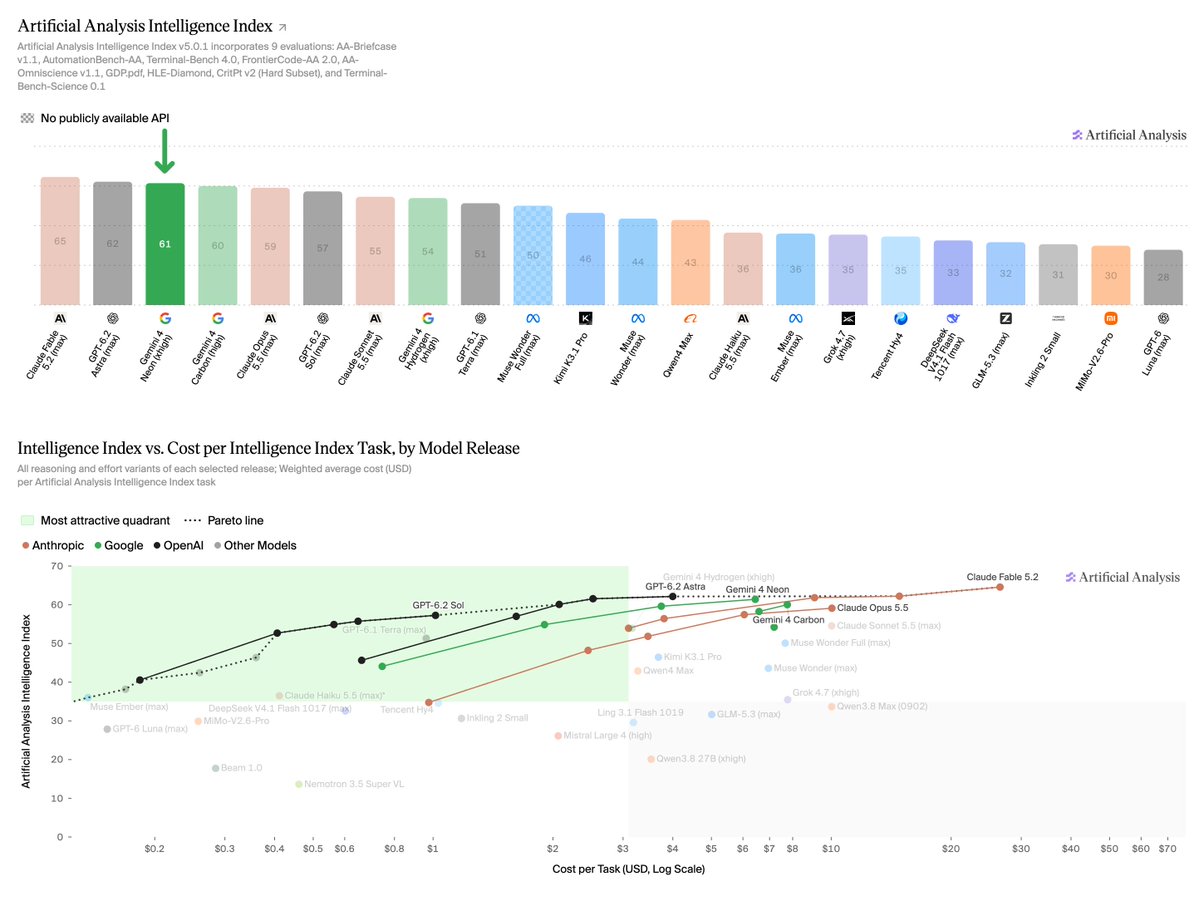
We’ve evaluated Gemini 4 Neon on FrontierCode 2.0, our benchmark that measures whether you should merge the PR, and found that it scores within one point of Opus 5.5 at about a third of the cost. It is the strongest of the Gemini model series with a score of 46.2% and a cost of $4.38 per task. Gemini 4 Neon is now available to use in Devin Desktop and Devin CLI!

Context
Cognition, the company behind the Devin coding , reports that Google's new Gemini 4 Neon scores 46.2% on FrontierCode 2.0, Cognition's own coding , at $4.38 per task, and has added the model to Devin Desktop and Devin CLI (post). Cognition says that puts Neon within one point of Anthropic's Claude Opus 5.5 at about a third of the cost. The post does not give Opus's score. The benchmark table in Google DeepMind's rollout post lists Opus 5.5 at 47.3% against Neon's 46.2%, so Opus still leads this test, by 1.1 points.
The percentage is not a share of tasks solved. According to the FrontierCode page, the benchmark asks whether a project's maintainer would actually merge the pull request a model produces. Its 132 tasks were written by open-source maintainers, who define what mergeable means in their own repositories, and grading combines unit tests, rubrics and other checks for correctness, test quality, scope and style. The score is a weighted total of rubric items, and a solution that fails any blocking criterion gets zero. Cost is the average spend per attempt at list API prices, so it reflects how much work the model does on each task as well as its price per . Read together, the two figures say Neon earns nearly the same partial credit as Opus 5.5 on these tasks while spending far less to do it.
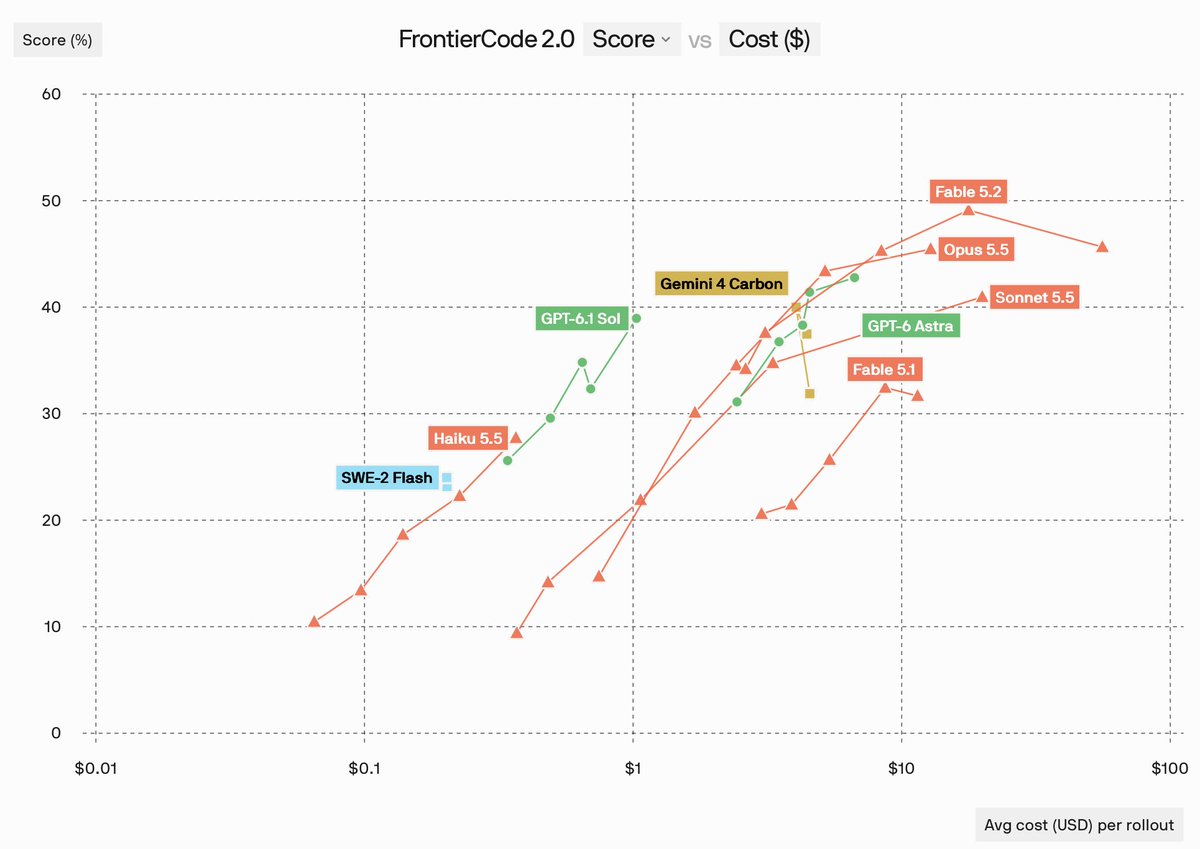
The comparison does not match settings model for model. The chart attached to the post plots each model at several reasoning settings without labeling them. Google's launch post says the 46.2% comes from Neon's default high setting, but neither source says which Opus setting produced 47.3%. On the chart, Opus's top point sits at roughly three times Neon's cost, consistent with Cognition's claim, and a more expensive Neon run scored lower than the 46.2% one. The chart also places Neon above Google's other Gemini 4 models and below Claude Fable 5.2, which Cognition reported as the benchmark's leader earlier this month. Cognition built and runs FrontierCode, and Google's launch post attributes its Neon figure to Cognition, so the two sources do not independently confirm the result. Cognition's full write-up was not read for this explanation.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…