Gemini 4 Hydrogen lands in Devin, scoring 38.2% on FrontierCode 2.0
- Source
- x.com
- Date

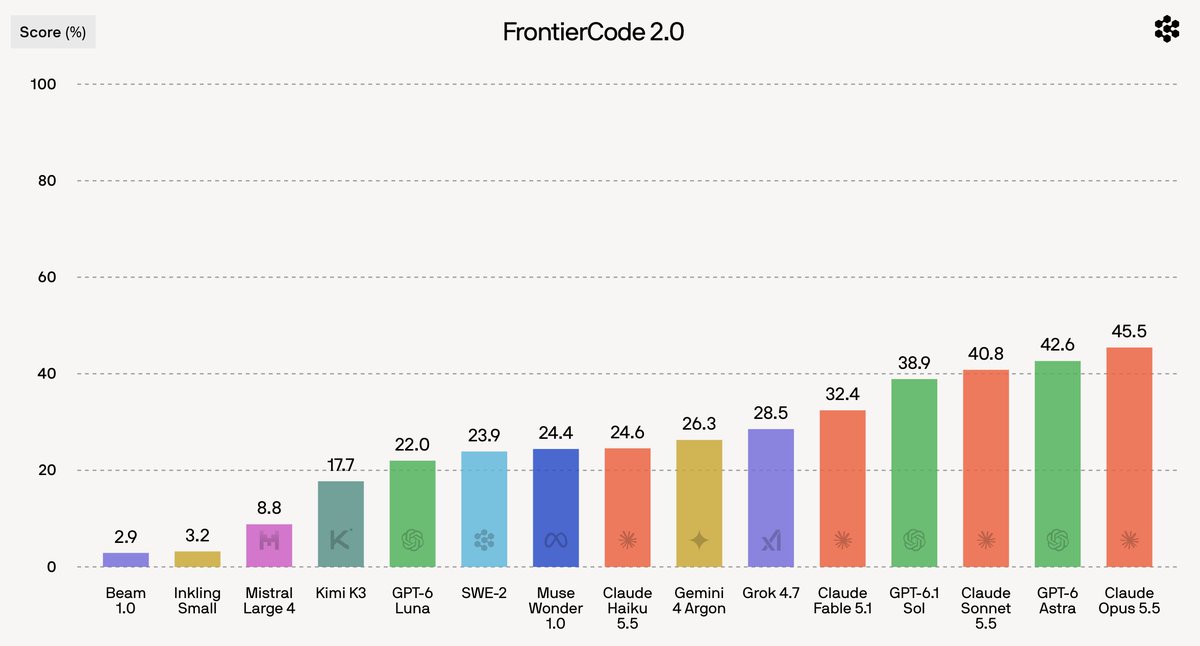
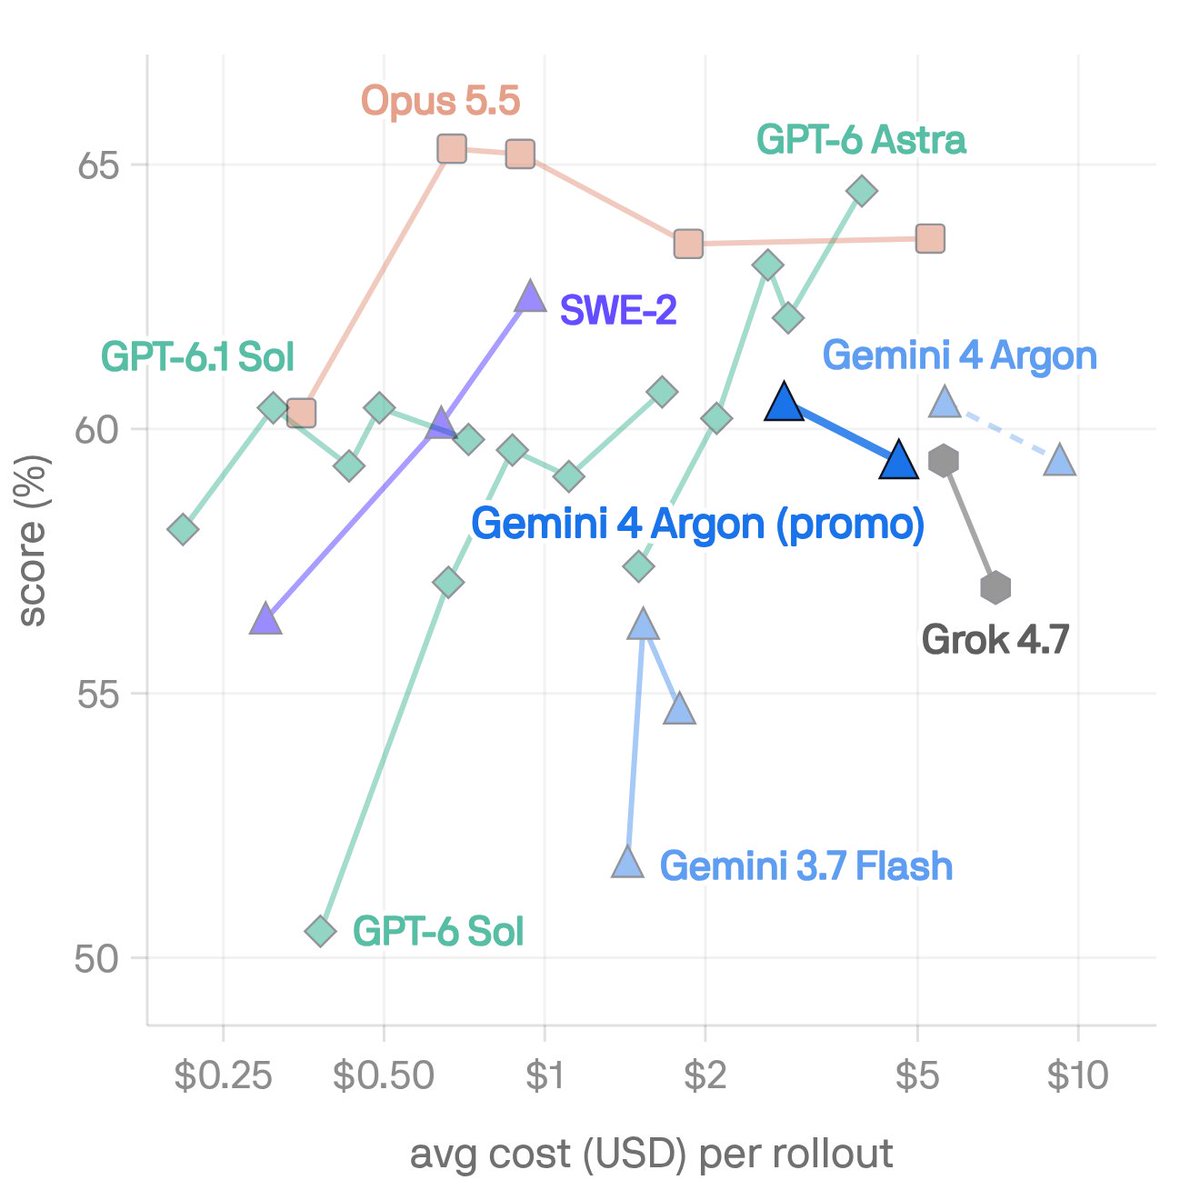
Gemini 4 Hydrogen is now live in Devin Desktop and Devin CLI. On FrontierCode 2.0, our benchmark that evaluates models on real-world engineering tasks based on quality and mergeability, Gemini 4 Hydrogen scores 38.2%, just behind GPT-6.1 Sol.

Context
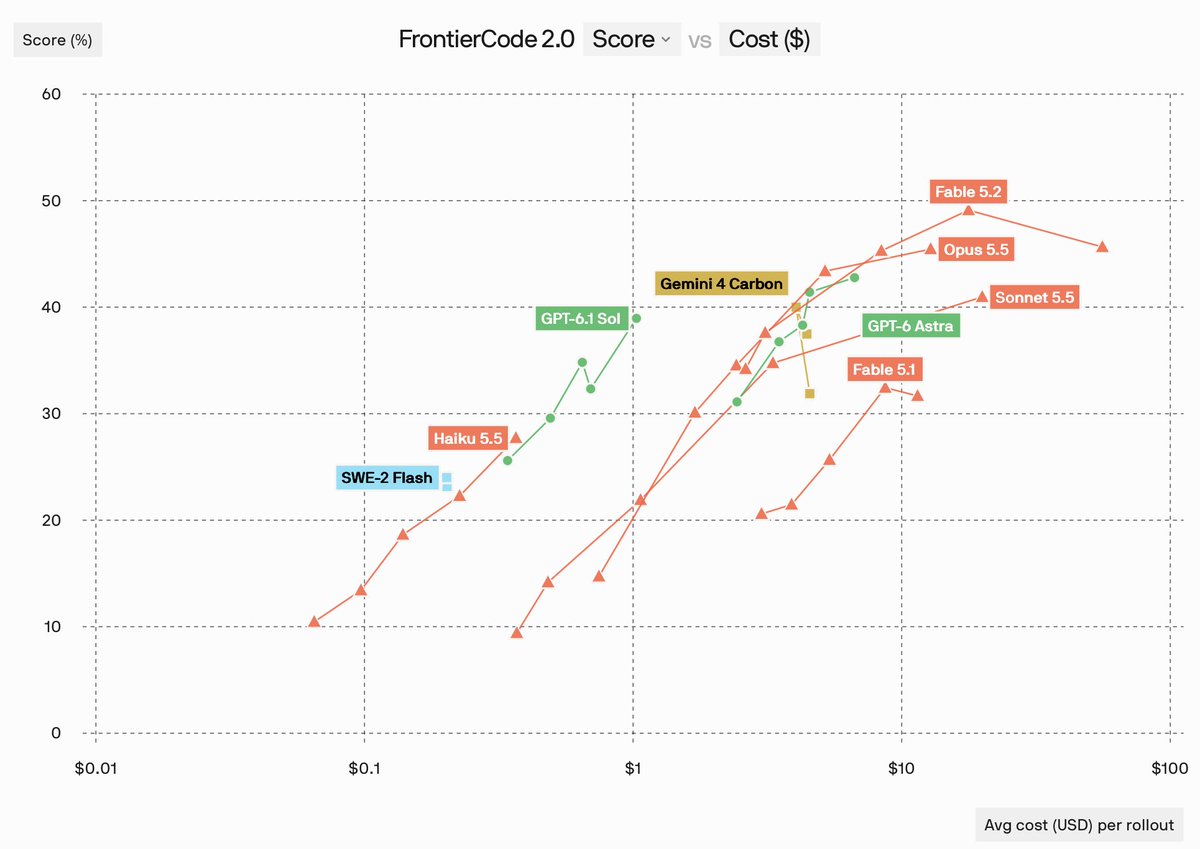
Cognition, the company behind the Devin coding , has added Google's Gemini 4 Hydrogen to Devin and reports that it scores 38.2% on FrontierCode 2.0, just behind GPT-6.1 Sol (announcement). The number looks low until you know the test. FrontierCode is Cognition's own , and instead of asking whether code passes a specification, it asks whether a project's maintainer would actually merge the pull request. According to the benchmark page, each task was built by the open-source maintainers of the repository it comes from, grading covers correctness, tests, scope discipline and style, and a solution that fails any blocking criterion scores zero. Version 2.0, released in late October, has 132 tasks and deliberately vague prompts that leave engineering decisions to the model. At its launch the top model scored 45%, and Claude Fable 5.2 has since taken first place at 49.1.
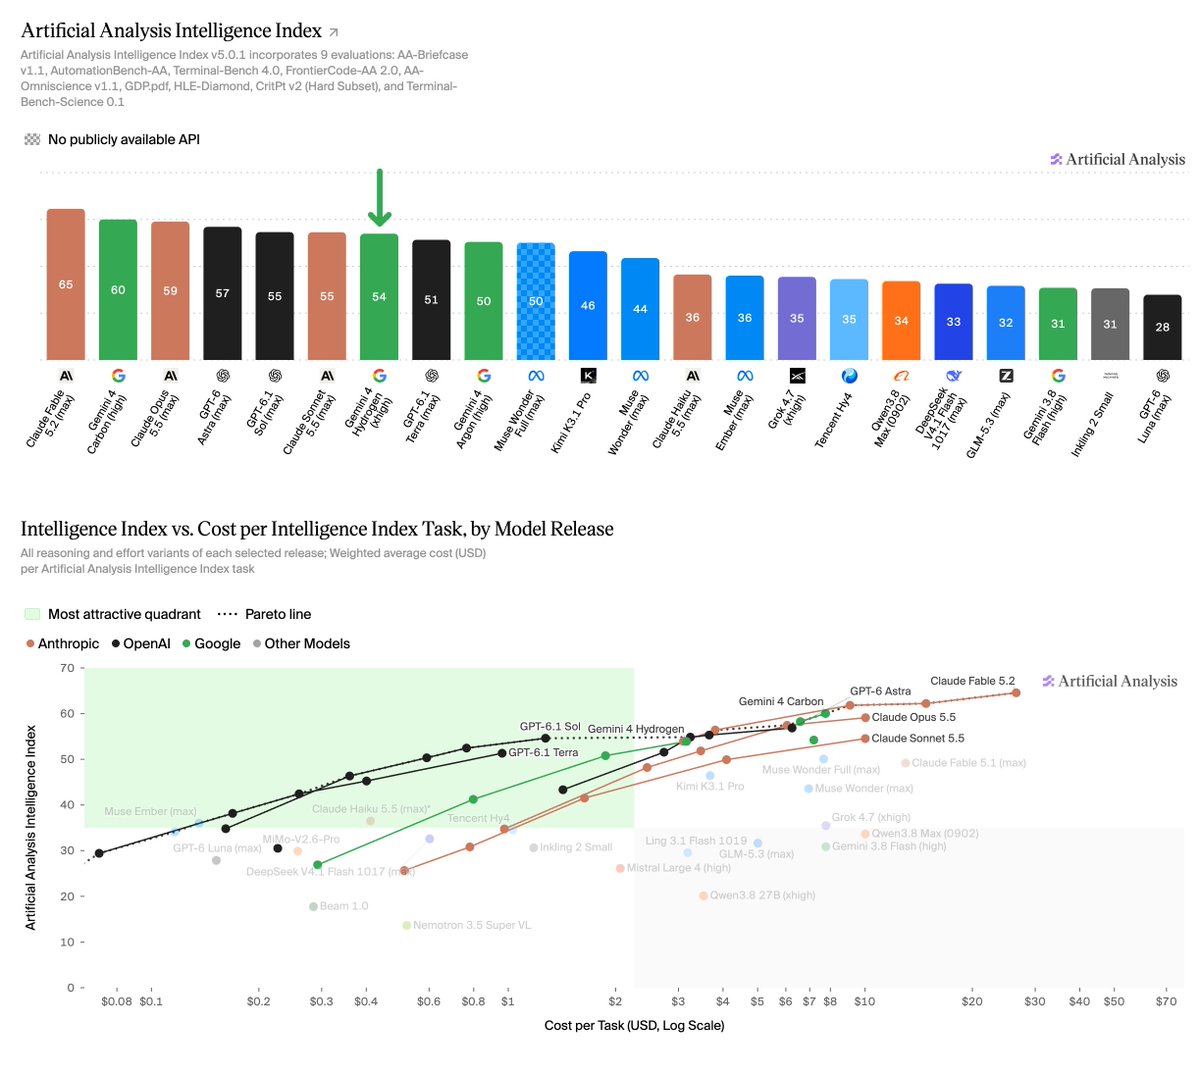
That changes what 38.2% says about Hydrogen. Google does not position Hydrogen as its strongest model. Its launch post describes a fast, cheaper model for everyday coding, priced at $1.50 per million input and $7.50 per million output tokens, meant to work on its own or as the execution engine beside Google's frontier models, Gemini 4 Carbon and Argon. Landing just behind GPT-6.1 Sol on a strict merge test, as Cognition describes it, would be a reasonable result for that role. Cognition's post does not give GPT-6.1 Sol's score, the reasoning level Hydrogen ran at, or the cost per task, and its linked material was not read here, so the size of the gap and the price trade-off cannot be judged from this announcement. Fable 5.2's 49.1 was also posted without a reasoning level, so the roughly 11-point gap to the leader compares headline figures, not matched settings. The score is also Cognition's measurement on its own benchmark rather than an independent one.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…