Introducing our Artifacts Hub and Adoption Dashboard
- Source
- interconnects.ai
- Author
- Nathan Lambert
- Date
Context
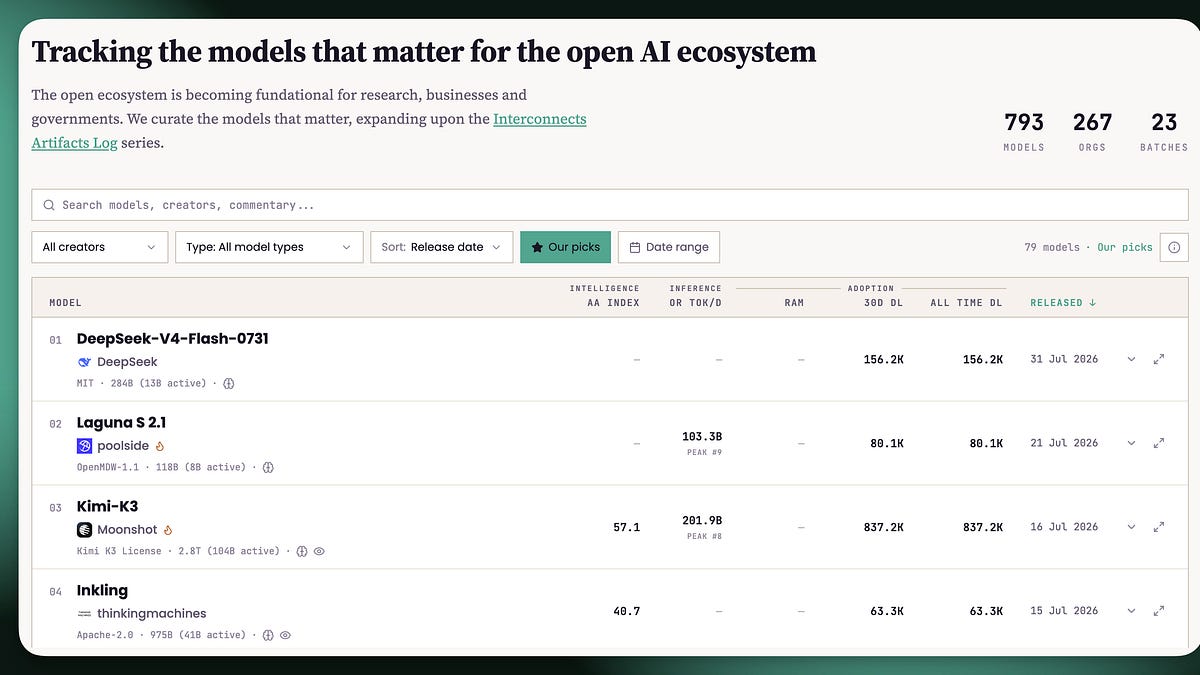
Nathan Lambert's Artifacts Hub puts model test results alongside evidence of adoption, making the two easier to compare without treating them as the same thing. The launch announcement describes a curated collection of 792 models, with scores, download measures and API usage data. Its relative adoption metric normalizes downloads by time and model size.
A companion Adoption Dashboard groups downloads and derivative models by organization and geography, with daily updates. These resources help distinguish tested capability from activity around a model. Their adoption measures describe the tracked services and repositories, rather than a census of users or the entire AI market.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
“The Artifacts Hub right now covers 792 models released in the last two years, across the core text-focused language models and multimodal generative models.”
“At Interconnects we follow the data of every model on Hugging Face, analyze the core few thousand LLMs (this list is public on GitHub and regularly updated), and hand select these core few hundred for further explanation.”
“Right now, as the world figures out how to use open models productively — especially in cost-competitive ways to frontier models — providing more transparency on what is happening is the best way for us to figure out what is working.”
Checking sign-in…
Loading comments…