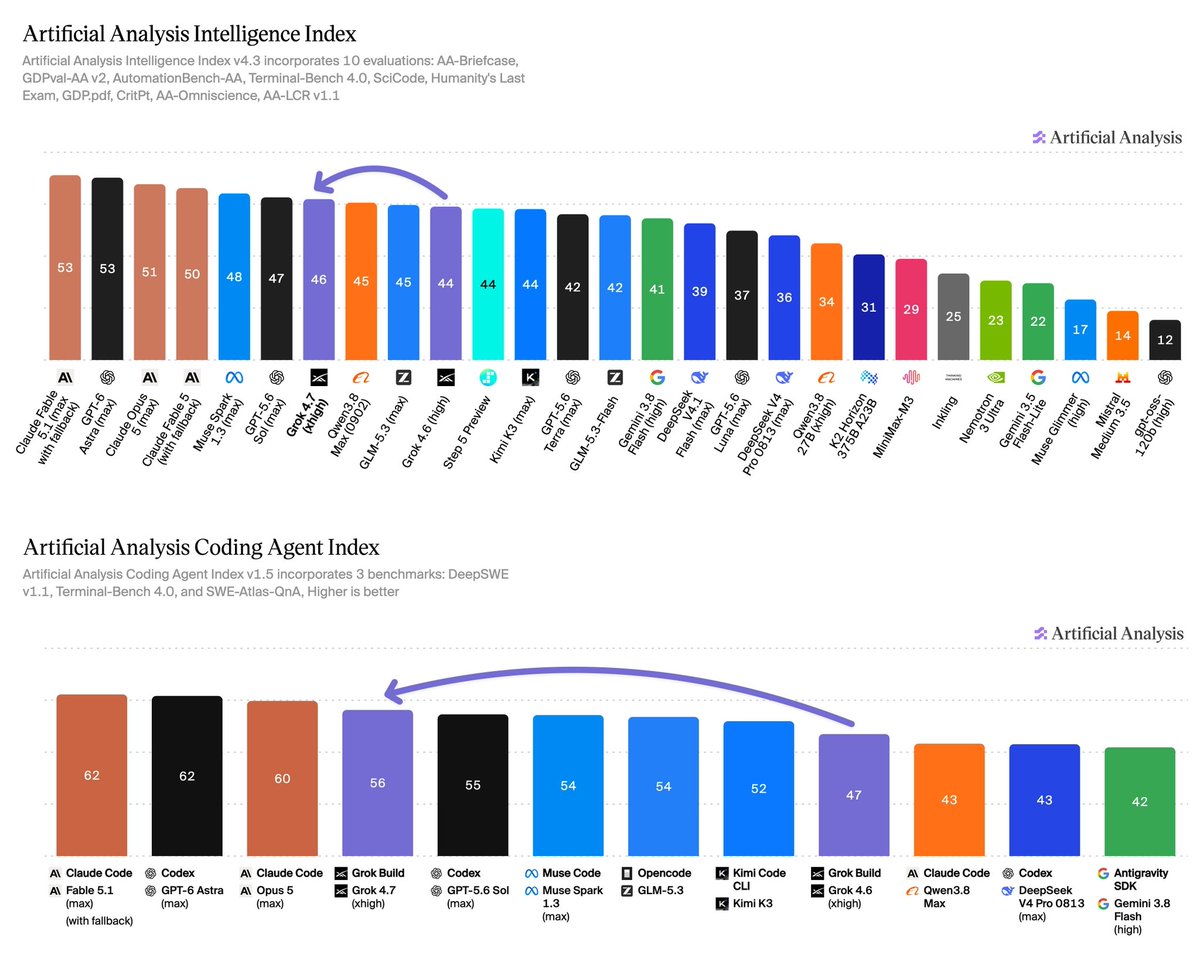
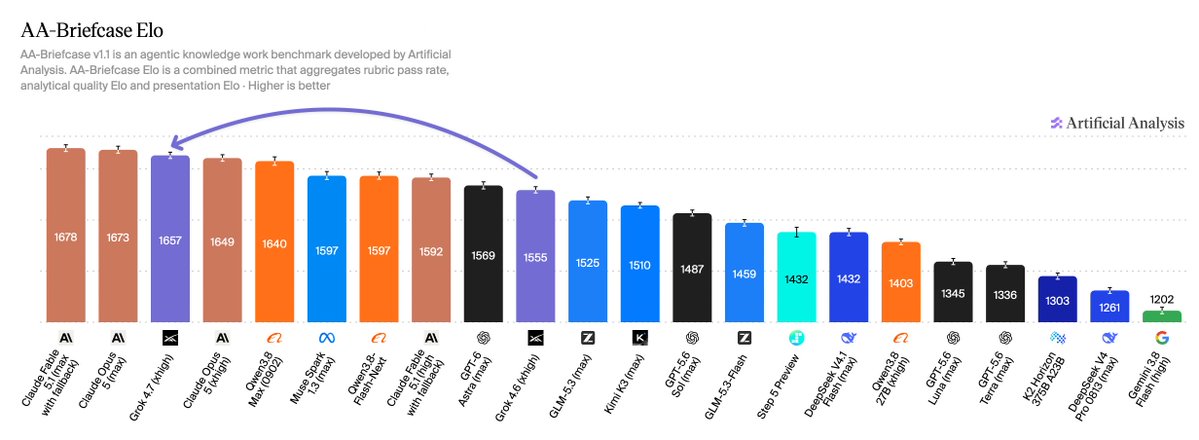
Grok 4.6 made large gains on AA-Briefcase, our agentic knowledge work benchmark…
- Source
- Artificial Analysis
- Date

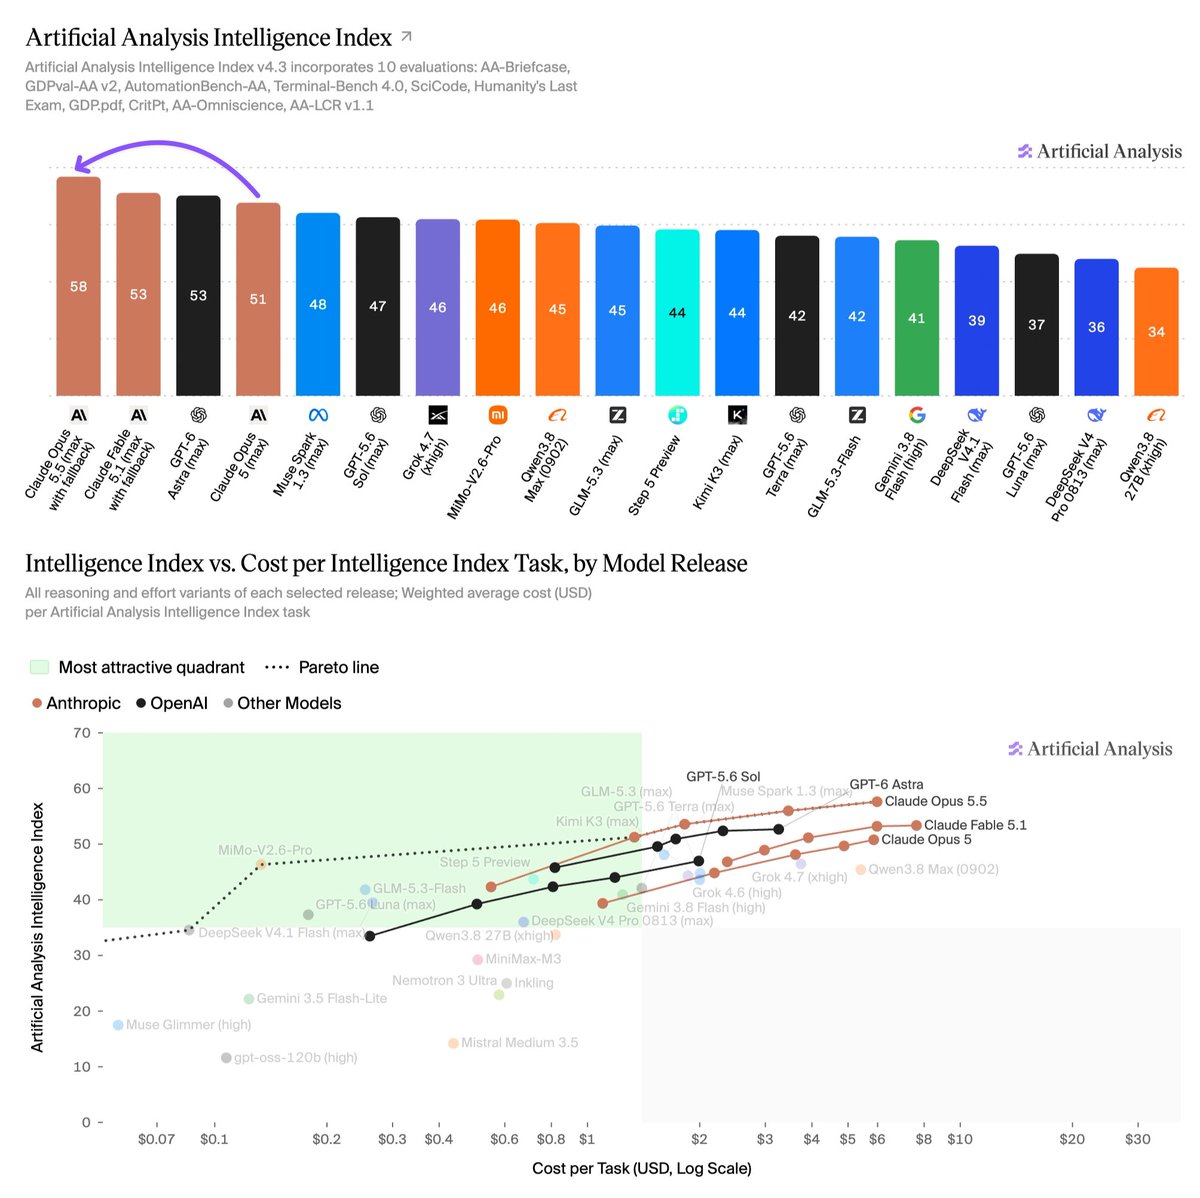
Grok 4.6 made large gains on AA-Briefcase, our agentic knowledge work benchmark and cost substantially less than other leading models AA-Briefcase tests models on long-horizon agentic knowledge work tasks. The test set is private to prevent contamination. Grok 4.6 is neck and neck with Claude Fable 5, with overlapping confidence intervals. The model is also substantially cheaper than other leading models on the benchmark at a Cost per Task of $4.42 compared to Claude Fable 5's $22.30, Claude Opus 5's $17.79 and Kimi K3's $6.73. Impressive release @SpaceXAI and @elonmusk.

Cost per task of $4.42 against $22.30 for a model with overlapping confidence intervals is the kind of price-performance datapoint that changes which model an pipeline is built on.
Checking sign-in…
Loading comments…